mirror of
https://github.com/seaweedfs/seaweedfs.git
synced 2026-10-01 20:26:27 +00:00
Compare commits
6
Commits
master
..
iam-phase1
| Author | SHA1 | Date | |
|---|---|---|---|
 Chris Lu |
18ae84e1ec | ||
|
Chris Lu
|
641bea825d | ||
|
Chris Lu
|
91fe0a5162 | ||
|
Chris Lu
|
64a60607c6 | ||
|
Chris Lu
|
d4365e2f37 | ||
|
Chris Lu
|
f9dfc0ea37 |
@@ -1,23 +0,0 @@
|
||||
[codespell]
|
||||
# Ref: https://github.com/codespell-project/codespell#using-a-config-file
|
||||
skip = .git,.git-meta,.gitignore,.gitattributes,*.svg,go.sum,vendor,*.lock,*.css,*.min.*,.codespellrc,*_templ.go
|
||||
check-hidden = true
|
||||
# Ignore camelCase and PascalCase identifiers (very common in Go/Rust/JS
|
||||
# source, e.g. allLocations, publishErr, ReadInside, FlushInterval).
|
||||
ignore-regex = \b[a-z]+[A-Z]\w*\b|\b[A-Z][a-z]+[A-Z]\w*\b
|
||||
# visibles: variable name for VisibleInterval collections in filer/mount code
|
||||
# fo: `*FilerOptions` receiver name (e.g. `func (fo *FilerOptions) ...`)
|
||||
# te: "truncate error" local variable (e.g. `if te := w.Truncate(end); te != nil`)
|
||||
# ser: Rust serde serializer variable (`serde_json::ser`, `let mut ser = ...`)
|
||||
# bject: intentional wildcard test data (e.g. `s3:Get?bject` matching `s3:GetObject`)
|
||||
# unparseable: accepted alternate spelling used throughout the codebase
|
||||
# keep-alives: correct plural of the technical term (SSH/HTTP keep-alive)
|
||||
# tread: valid English word in the idiom "tread carefully" (help text)
|
||||
# anc: variable abbreviation for "ancestor" in tree/path tests
|
||||
# ue: appears inside JSON test fixtures with embedded escaped quotes (Bl\"ue)
|
||||
# auther: local variable meaning "authenticator" (tls.go: `auther := Authenticator{}`)
|
||||
# thirdparty: literal Maven groupId `org.apache.hadoop.thirdparty` (external, cannot rename)
|
||||
# unknwon: GitHub username / Go module path (`github.com/unknwon/goconfig`)
|
||||
# atleast: CLI mode literal string in test/benchmark/fuse_db/bin/sqlite_verify.py
|
||||
# sme: local variable for a *streamMutateError in mount tests
|
||||
ignore-words-list = visibles,fo,te,ser,bject,unparseable,keep-alives,tread,anc,ue,auther,thirdparty,unknwon,atleast,sme
|
||||
@@ -1,66 +0,0 @@
|
||||
name: Fix fusermount3 setuid
|
||||
description: >
|
||||
Make sure the fusermount3 an unprivileged mount will find can actually mount.
|
||||
Some runner images carry a second, source-built fusermount3 in /usr/local/bin
|
||||
that shadows the distro one in PATH; it is neither setuid nor root-owned, so
|
||||
every mount fails with "mount failed: Operation not permitted". Both the Go
|
||||
mount and sw-fuse resolve the helper through PATH.
|
||||
Run it after the step that apt-installs fuse3.
|
||||
|
||||
runs:
|
||||
using: composite
|
||||
steps:
|
||||
- name: Point PATH at a fusermount3 that can mount
|
||||
shell: bash
|
||||
run: |
|
||||
set -euo pipefail
|
||||
|
||||
# setuid only grants root when root owns the file, and exec follows
|
||||
# symlinks, so judge the target.
|
||||
can_mount() {
|
||||
[ -u "$1" ] && [ "$(stat -Lc %u "$1")" = 0 ]
|
||||
}
|
||||
|
||||
bin=$(command -v fusermount3 || true)
|
||||
if [ -z "$bin" ]; then
|
||||
echo "no fusermount3 in PATH" >&2
|
||||
exit 1
|
||||
fi
|
||||
if can_mount "$bin"; then
|
||||
ls -l "$bin"
|
||||
exit 0
|
||||
fi
|
||||
echo "$bin cannot mount unprivileged:"
|
||||
ls -l "$bin"
|
||||
|
||||
# The distro fusermount3 is setuid root and is the one meant to be used.
|
||||
# Reach it through a symlink earlier in PATH: exec resolves the link, so
|
||||
# the target keeps its setuid bit, and nothing on the image is modified.
|
||||
for distro in /usr/bin/fusermount3 /bin/fusermount3; do
|
||||
if [ "$distro" != "$bin" ] && can_mount "$distro"; then
|
||||
mkdir -p "$RUNNER_TEMP/fuse-bin"
|
||||
ln -sf "$distro" "$RUNNER_TEMP/fuse-bin/fusermount3"
|
||||
echo "$RUNNER_TEMP/fuse-bin" >> "$GITHUB_PATH"
|
||||
echo "using $distro instead"
|
||||
ls -l "$distro"
|
||||
exit 0
|
||||
fi
|
||||
done
|
||||
|
||||
# No usable distro binary, so setting the bit is the only way out - but
|
||||
# the target came from PATH: do that only for a root-owned system binary,
|
||||
# never for anything else that happens to sit there.
|
||||
case "$bin" in
|
||||
/bin/*|/sbin/*|/usr/bin/*|/usr/sbin/*|/usr/local/bin/*|/usr/local/sbin/*) ;;
|
||||
*) echo "refusing to setuid $bin: outside the system bin paths" >&2; exit 1 ;;
|
||||
esac
|
||||
if [ -L "$bin" ] || [ ! -f "$bin" ] || [ ! -x "$bin" ]; then
|
||||
echo "refusing to setuid $bin: not a regular executable file" >&2
|
||||
exit 1
|
||||
fi
|
||||
if [ "$(stat -c %u "$bin")" != 0 ] || [ "$(stat -c %g "$bin")" != 0 ]; then
|
||||
echo "refusing to setuid $bin: not owned by root:root" >&2
|
||||
exit 1
|
||||
fi
|
||||
sudo chmod u+s "$bin"
|
||||
ls -l "$bin"
|
||||
@@ -1,44 +0,0 @@
|
||||
name: Sign container images
|
||||
description: >
|
||||
Keyless cosign signature on each image, then a verification pass against the
|
||||
identity the signature should carry, so a misconfigured job fails here and not
|
||||
on someone's cluster. That identity is the calling workflow's own,
|
||||
https://github.com/<owner>/<repo>/.github/workflows/<file>@<ref>.
|
||||
The calling job needs `id-token: write` and a registry login for every image.
|
||||
|
||||
inputs:
|
||||
images:
|
||||
description: Image references by digest (name@sha256:...), whitespace separated.
|
||||
required: true
|
||||
|
||||
runs:
|
||||
using: composite
|
||||
steps:
|
||||
- name: Install cosign
|
||||
uses: sigstore/cosign-installer@v4.1.2
|
||||
|
||||
- name: Sign
|
||||
shell: bash
|
||||
env:
|
||||
IMAGES: ${{ inputs.images }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
# The .sig tag layout: the OCI-referrer bundle cosign 3 writes by default
|
||||
# is not read by the Kyverno and policy-controller releases in use today.
|
||||
# Cosign 3 also defaults to --use-signing-config, which insists on a
|
||||
# bundle for its output; turning it off falls back to the default
|
||||
# Fulcio and Rekor URLs, which is all the .sig layout ever used.
|
||||
cosign sign --yes --recursive \
|
||||
--new-bundle-format=false --use-signing-config=false \
|
||||
$IMAGES
|
||||
|
||||
- name: Verify
|
||||
shell: bash
|
||||
env:
|
||||
IMAGES: ${{ inputs.images }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
cosign verify \
|
||||
--certificate-oidc-issuer https://token.actions.githubusercontent.com \
|
||||
--certificate-identity "https://github.com/$GITHUB_WORKFLOW_REF" \
|
||||
$IMAGES
|
||||
@@ -1,9 +1,7 @@
|
||||
version: 2
|
||||
updates:
|
||||
- package-ecosystem: "github-actions"
|
||||
directories:
|
||||
- "/"
|
||||
- "/.github/actions/sign-image"
|
||||
directory: "/"
|
||||
schedule:
|
||||
interval: "weekly"
|
||||
- package-ecosystem: gomod
|
||||
|
||||
@@ -1,87 +0,0 @@
|
||||
#!/usr/bin/env python3
|
||||
"""Render the repository's star history to note/star_history.svg.
|
||||
|
||||
Uses the GitHub REST stargazers endpoint with the starred-at accept header,
|
||||
which caps at 40,000 entries (400 pages of 100). The chart is regenerated on
|
||||
a schedule; if the repo grows past that cap the script stops at 40,000 and
|
||||
logs a warning rather than under-reporting.
|
||||
"""
|
||||
import json
|
||||
import os
|
||||
import sys
|
||||
import urllib.request
|
||||
from datetime import datetime
|
||||
|
||||
import matplotlib
|
||||
|
||||
matplotlib.use("Agg")
|
||||
import matplotlib.pyplot as plt # noqa: E402
|
||||
from matplotlib.dates import AutoDateLocator, DateFormatter # noqa: E402
|
||||
|
||||
REPO = "seaweedfs/seaweedfs"
|
||||
TOKEN = os.environ["GITHUB_TOKEN"]
|
||||
OUT = os.environ.get("OUT", "note/star_history.svg")
|
||||
PAGE_CAP = 400 # GitHub's hard limit on stargazer pagination
|
||||
|
||||
|
||||
def fetch_stargazers():
|
||||
stars = []
|
||||
page = 1
|
||||
while page <= PAGE_CAP:
|
||||
url = f"https://api.github.com/repos/{REPO}/stargazers?per_page=100&page={page}"
|
||||
req = urllib.request.Request(
|
||||
url,
|
||||
headers={
|
||||
"Accept": "application/vnd.github.star+json",
|
||||
"Authorization": f"Bearer {TOKEN}",
|
||||
"X-GitHub-Api-Version": "2022-11-28",
|
||||
"User-Agent": "seaweedfs-star-history",
|
||||
},
|
||||
)
|
||||
with urllib.request.urlopen(req) as resp:
|
||||
batch = json.load(resp)
|
||||
if not batch:
|
||||
break
|
||||
for u in batch:
|
||||
sa = u.get("starred_at")
|
||||
if sa:
|
||||
stars.append(datetime.fromisoformat(sa.replace("Z", "+00:00")))
|
||||
if len(batch) < 100:
|
||||
break
|
||||
page += 1
|
||||
if page > PAGE_CAP:
|
||||
print(
|
||||
f"::warning::Hit the {PAGE_CAP}-page stargazer pagination cap; "
|
||||
"chart reflects the first 40,000 stars only."
|
||||
)
|
||||
return stars
|
||||
|
||||
|
||||
def render(stars, out):
|
||||
stars.sort()
|
||||
counts = list(range(1, len(stars) + 1))
|
||||
fig, ax = plt.subplots(figsize=(10, 6), dpi=130)
|
||||
ax.plot(stars, counts, color="#0969da", linewidth=1.6)
|
||||
ax.set_xlabel("Date")
|
||||
ax.set_ylabel("Stars")
|
||||
ax.set_title(f"{REPO} star history")
|
||||
ax.grid(True, linestyle="--", alpha=0.3)
|
||||
ax.xaxis.set_major_locator(AutoDateLocator())
|
||||
ax.xaxis.set_major_formatter(DateFormatter("%Y-%m"))
|
||||
fig.autofmt_xdate()
|
||||
fig.tight_layout()
|
||||
fig.savefig(out, format="svg", transparent=False)
|
||||
plt.close(fig)
|
||||
|
||||
|
||||
def main():
|
||||
stars = fetch_stargazers()
|
||||
if not stars:
|
||||
print("::error::No stargazers fetched; not updating the chart.")
|
||||
sys.exit(1)
|
||||
render(stars, OUT)
|
||||
print(f"Rendered {len(stars)} stars to {OUT}")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -3,11 +3,6 @@ name: "go: build dev binaries"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/binaries_dev.yml'
|
||||
|
||||
concurrency:
|
||||
group: binaries-dev-${{ github.ref }}
|
||||
@@ -48,7 +43,7 @@ jobs:
|
||||
steps:
|
||||
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1 # v2
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v2
|
||||
|
||||
- name: Set BUILD_TIME env
|
||||
run: echo BUILD_TIME=$(date -u +%Y%m%d-%H%M) >> ${GITHUB_ENV}
|
||||
@@ -97,7 +92,7 @@ jobs:
|
||||
steps:
|
||||
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1 # v2
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v2
|
||||
|
||||
- name: Set BUILD_TIME env
|
||||
run: echo BUILD_TIME=$(date -u +%Y%m%d-%H%M) >> ${GITHUB_ENV}
|
||||
|
||||
@@ -28,7 +28,7 @@ jobs:
|
||||
# Steps represent a sequence of tasks that will be executed as part of the job
|
||||
steps:
|
||||
# Checks-out your repository under $GITHUB_WORKSPACE, so your job can access it
|
||||
- uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1 # v2
|
||||
- uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v2
|
||||
- name: Go Release Binaries Normal Volume Size
|
||||
uses: wangyoucao577/go-release-action@279495102627de7960cbc33434ab01a12bae144b # v1.22
|
||||
with:
|
||||
|
||||
@@ -2,11 +2,6 @@ name: "Code Scanning - Action"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- '**/*.go'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/codeql.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/codeql
|
||||
@@ -23,11 +18,11 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout repository
|
||||
uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd
|
||||
|
||||
# Initializes the CodeQL tools for scanning.
|
||||
- name: Initialize CodeQL
|
||||
uses: github/codeql-action/init@v4.38.2
|
||||
uses: github/codeql-action/init@v4
|
||||
# Override language selection by uncommenting this and choosing your languages
|
||||
with:
|
||||
languages: go
|
||||
@@ -35,7 +30,7 @@ jobs:
|
||||
# Autobuild attempts to build any compiled languages (C/C++, C#, or Java).
|
||||
# If this step fails, then you should remove it and run the build manually (see below).
|
||||
- name: Autobuild
|
||||
uses: github/codeql-action/autobuild@v4.38.2
|
||||
uses: github/codeql-action/autobuild@v4
|
||||
|
||||
# ℹ️ Command-line programs to run using the OS shell.
|
||||
# 📚 See https://docs.github.com/en/actions/using-workflows/workflow-syntax-for-github-actions#jobsjob_idstepsrun
|
||||
@@ -49,4 +44,4 @@ jobs:
|
||||
# make release
|
||||
|
||||
- name: Perform CodeQL Analysis
|
||||
uses: github/codeql-action/analyze@v4.38.2
|
||||
uses: github/codeql-action/analyze@v4
|
||||
|
||||
@@ -1,23 +0,0 @@
|
||||
# Codespell configuration is within .codespellrc
|
||||
---
|
||||
name: Codespell
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [master]
|
||||
pull_request:
|
||||
branches: [master]
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
codespell:
|
||||
name: Check for spelling errors
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
- name: Codespell
|
||||
uses: codespell-project/actions-codespell@8f01853be192eb0f849a5c7d721450e7a467c579 # v2.2
|
||||
@@ -3,22 +3,13 @@ name: "docker: build dev containers"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'seaweed-volume/**'
|
||||
- 'seaweed-common/**'
|
||||
- 'seaweed-worker/**'
|
||||
- 'docker/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/container_dev.yml'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
|
||||
# ── Pre-build the Rust binaries natively ────────────────────────────
|
||||
# ── Pre-build Rust volume server binaries natively ──────────────────
|
||||
build-rust-binaries:
|
||||
runs-on: ubuntu-22.04
|
||||
strategy:
|
||||
@@ -31,7 +22,10 @@ jobs:
|
||||
cross: true
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
@@ -51,32 +45,16 @@ jobs:
|
||||
echo "CFLAGS_aarch64_unknown_linux_musl=-U_FORTIFY_SOURCE" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
seaweed-worker/target/${{ matrix.target }}/release
|
||||
key: rust-docker-dev-${{ matrix.target }}-${{ hashFiles('seaweed-volume/Cargo.lock', 'seaweed-worker/Cargo.lock') }}
|
||||
key: rust-docker-dev-${{ matrix.target }}-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-docker-dev-${{ matrix.target }}-
|
||||
|
||||
# lance's build scripts compile their own protos and look for a protoc.
|
||||
# Point them at the one protoc-bin-vendored ships, which seaweed-worker's
|
||||
# own build already uses, so no job depends on a system package and every
|
||||
# build sees the same version.
|
||||
- name: Use the vendored protoc
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo fetch
|
||||
# The version from the lock, not whatever else a restored cache holds.
|
||||
version=$(awk '/^name = "protoc-bin-vendored-linux-x86_64"$/{found=1; next} found && /^version = /{gsub(/"/,"",$3); print $3; exit}' Cargo.lock)
|
||||
test -n "$version" || { echo "protoc-bin-vendored-linux-x86_64 is not in Cargo.lock" >&2; exit 1; }
|
||||
protoc=$(find ~/.cargo/registry/src -path "*protoc-bin-vendored-linux-x86_64-$version/bin/protoc" | head -1)
|
||||
test -x "$protoc" || { echo "no vendored protoc $version in the registry" >&2; exit 1; }
|
||||
echo "PROTOC=$protoc" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Build normal variant
|
||||
env:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
@@ -85,35 +63,24 @@ jobs:
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features
|
||||
cp target/${{ matrix.target }}/release/weed-volume ../weed-volume-normal-${{ matrix.arch }}
|
||||
|
||||
- name: Build the Rust maintenance worker
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo build --release -p weed-lance-worker --target ${{ matrix.target }}
|
||||
cp target/${{ matrix.target }}/release/weed-worker ../weed-worker-${{ matrix.arch }}
|
||||
|
||||
- name: Upload artifacts
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: rust-bins-${{ matrix.arch }}
|
||||
path: |
|
||||
weed-volume-normal-${{ matrix.arch }}
|
||||
weed-worker-${{ matrix.arch }}
|
||||
name: rust-volume-${{ matrix.arch }}
|
||||
path: weed-volume-normal-${{ matrix.arch }}
|
||||
|
||||
build-dev-containers:
|
||||
needs: [build-rust-binaries]
|
||||
runs-on: [ubuntu-latest]
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Download pre-built Rust binaries
|
||||
uses: actions/download-artifact@v8
|
||||
with:
|
||||
pattern: rust-bins-*
|
||||
pattern: rust-volume-*
|
||||
merge-multiple: true
|
||||
path: ./rust-bins
|
||||
|
||||
@@ -127,16 +94,7 @@ jobs:
|
||||
echo "Placed pre-built Rust binary for ${arch}"
|
||||
fi
|
||||
done
|
||||
mkdir -p docker/weed-worker-prebuilt
|
||||
for arch in amd64 arm64; do
|
||||
src="./rust-bins/weed-worker-${arch}"
|
||||
if [ -f "$src" ]; then
|
||||
cp "$src" "docker/weed-worker-prebuilt/weed-worker-${arch}"
|
||||
echo "Placed pre-built Rust worker for ${arch}"
|
||||
fi
|
||||
done
|
||||
ls -la docker/weed-volume-prebuilt/
|
||||
ls -la docker/weed-worker-prebuilt/
|
||||
|
||||
- name: Docker meta
|
||||
id: docker_meta
|
||||
@@ -153,7 +111,7 @@ jobs:
|
||||
org.opencontainers.image.vendor=Chris Lu
|
||||
|
||||
- name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@v4.4.0
|
||||
uses: docker/setup-qemu-action@v4
|
||||
|
||||
- name: Create BuildKit config
|
||||
run: |
|
||||
@@ -170,21 +128,20 @@ jobs:
|
||||
|
||||
- name: Login to Docker Hub
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
- name: Login to GHCR
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
password: ${{ secrets.GHCR_TOKEN }}
|
||||
|
||||
- name: Build
|
||||
id: build
|
||||
uses: docker/build-push-action@v7
|
||||
with:
|
||||
context: ./docker
|
||||
@@ -193,11 +150,3 @@ jobs:
|
||||
platforms: linux/amd64, linux/arm64
|
||||
tags: ${{ steps.docker_meta.outputs.tags }}
|
||||
labels: ${{ steps.docker_meta.outputs.labels }}
|
||||
|
||||
- name: Sign
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: ./.github/actions/sign-image
|
||||
with:
|
||||
images: >-
|
||||
chrislusf/seaweedfs@${{ steps.build.outputs.digest }}
|
||||
ghcr.io/chrislusf/seaweedfs@${{ steps.build.outputs.digest }}
|
||||
|
||||
@@ -30,13 +30,10 @@ permissions:
|
||||
jobs:
|
||||
build-foundationdb-image:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
with:
|
||||
fetch-depth: 0
|
||||
|
||||
@@ -61,7 +58,7 @@ jobs:
|
||||
sudo ldconfig
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: go.mod
|
||||
|
||||
@@ -129,35 +126,30 @@ jobs:
|
||||
echo "seaweedfs_ref=$seaweed" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@v4.4.0
|
||||
uses: docker/setup-qemu-action@v4
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Login to Docker Hub
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
- name: Determine branch to build
|
||||
id: branch
|
||||
env:
|
||||
INPUT_REF: ${{ inputs.seaweedfs_ref }}
|
||||
HEAD_REF: ${{ github.head_ref }}
|
||||
REF_NAME: ${{ github.ref_name }}
|
||||
run: |
|
||||
if [ -n "$INPUT_REF" ]; then
|
||||
echo "branch=$INPUT_REF" >> "$GITHUB_OUTPUT"
|
||||
if [ -n "${{ inputs.seaweedfs_ref }}" ]; then
|
||||
echo "branch=${{ inputs.seaweedfs_ref }}" >> "$GITHUB_OUTPUT"
|
||||
elif [ "${{ github.event_name }}" = "pull_request" ]; then
|
||||
echo "branch=$HEAD_REF" >> "$GITHUB_OUTPUT"
|
||||
echo "branch=${{ github.head_ref }}" >> "$GITHUB_OUTPUT"
|
||||
else
|
||||
echo "branch=$REF_NAME" >> "$GITHUB_OUTPUT"
|
||||
echo "branch=${{ github.ref_name }}" >> "$GITHUB_OUTPUT"
|
||||
fi
|
||||
|
||||
- name: Build and push image
|
||||
id: build
|
||||
uses: docker/build-push-action@v7
|
||||
with:
|
||||
context: ./docker
|
||||
@@ -175,8 +167,3 @@ jobs:
|
||||
org.opencontainers.image.description=SeaweedFS is a distributed storage system for blobs, objects, files, and data lake, to store and serve billions of files fast!
|
||||
org.opencontainers.image.vendor=Chris Lu
|
||||
|
||||
- name: Sign
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: ./.github/actions/sign-image
|
||||
with:
|
||||
images: chrislusf/seaweedfs@${{ steps.build.outputs.digest }}
|
||||
|
||||
@@ -1,10 +1,9 @@
|
||||
name: "docker: build latest container"
|
||||
|
||||
# Manual fallback only. On tag push, container_release_unified.yml already
|
||||
# re-tags the released versioned image as `latest` / `latest_large_disk`,
|
||||
# so a full rebuild here is unnecessary. Run this manually if you need to
|
||||
# rebuild `latest` from an arbitrary ref.
|
||||
on:
|
||||
push:
|
||||
tags:
|
||||
- '*'
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
source_ref:
|
||||
@@ -59,7 +58,7 @@ jobs:
|
||||
echo "publish=true" >> "$GITHUB_OUTPUT"
|
||||
fi
|
||||
|
||||
# ── Pre-build the Rust binaries natively ────────────────────────────
|
||||
# ── Pre-build Rust volume server binaries natively ──────────────────
|
||||
build-rust-binaries:
|
||||
runs-on: ubuntu-22.04
|
||||
strategy:
|
||||
@@ -72,10 +71,13 @@ jobs:
|
||||
cross: true
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
with:
|
||||
ref: ${{ github.event_name == 'workflow_dispatch' && github.event.inputs.source_ref || github.ref }}
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
with:
|
||||
@@ -94,32 +96,16 @@ jobs:
|
||||
echo "CFLAGS_aarch64_unknown_linux_musl=-U_FORTIFY_SOURCE" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
seaweed-worker/target/${{ matrix.target }}/release
|
||||
key: rust-docker-${{ matrix.target }}-${{ hashFiles('seaweed-volume/Cargo.lock', 'seaweed-worker/Cargo.lock') }}
|
||||
key: rust-docker-${{ matrix.target }}-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-docker-${{ matrix.target }}-
|
||||
|
||||
# lance's build scripts compile their own protos and look for a protoc.
|
||||
# Point them at the one protoc-bin-vendored ships, which seaweed-worker's
|
||||
# own build already uses, so no job depends on a system package and every
|
||||
# build sees the same version.
|
||||
- name: Use the vendored protoc
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo fetch
|
||||
# The version from the lock, not whatever else a restored cache holds.
|
||||
version=$(awk '/^name = "protoc-bin-vendored-linux-x86_64"$/{found=1; next} found && /^version = /{gsub(/"/,"",$3); print $3; exit}' Cargo.lock)
|
||||
test -n "$version" || { echo "protoc-bin-vendored-linux-x86_64 is not in Cargo.lock" >&2; exit 1; }
|
||||
protoc=$(find ~/.cargo/registry/src -path "*protoc-bin-vendored-linux-x86_64-$version/bin/protoc" | head -1)
|
||||
test -x "$protoc" || { echo "no vendored protoc $version in the registry" >&2; exit 1; }
|
||||
echo "PROTOC=$protoc" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Build large-disk variant
|
||||
env:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
@@ -136,32 +122,25 @@ jobs:
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features
|
||||
cp target/${{ matrix.target }}/release/weed-volume ../weed-volume-normal-${{ matrix.arch }}
|
||||
|
||||
- name: Build the Rust maintenance worker
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo build --release -p weed-lance-worker --target ${{ matrix.target }}
|
||||
cp target/${{ matrix.target }}/release/weed-worker ../weed-worker-${{ matrix.arch }}
|
||||
|
||||
- name: Upload artifacts
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: rust-bins-${{ matrix.arch }}
|
||||
name: rust-volume-${{ matrix.arch }}
|
||||
path: |
|
||||
weed-volume-large-disk-${{ matrix.arch }}
|
||||
weed-volume-normal-${{ matrix.arch }}
|
||||
weed-worker-${{ matrix.arch }}
|
||||
|
||||
build:
|
||||
needs: [setup, build-rust-binaries]
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
matrix:
|
||||
platform: [amd64, arm64, arm, 386, ppc64le, s390x]
|
||||
platform: [amd64, arm64, arm, 386]
|
||||
variant: ${{ fromJSON(needs.setup.outputs.variants) }}
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
with:
|
||||
ref: ${{ github.event_name == 'workflow_dispatch' && github.event.inputs.source_ref || github.ref }}
|
||||
- name: Free Disk Space
|
||||
@@ -197,7 +176,7 @@ jobs:
|
||||
- name: Download pre-built Rust binaries
|
||||
uses: actions/download-artifact@v8
|
||||
with:
|
||||
pattern: rust-bins-*
|
||||
pattern: rust-volume-*
|
||||
merge-multiple: true
|
||||
path: ./rust-bins
|
||||
|
||||
@@ -211,16 +190,7 @@ jobs:
|
||||
echo "Placed pre-built Rust binary for ${arch}"
|
||||
fi
|
||||
done
|
||||
mkdir -p docker/weed-worker-prebuilt
|
||||
for arch in amd64 arm64; do
|
||||
src="./rust-bins/weed-worker-${arch}"
|
||||
if [ -f "$src" ]; then
|
||||
cp "$src" "docker/weed-worker-prebuilt/weed-worker-${arch}"
|
||||
echo "Placed pre-built Rust worker for ${arch}"
|
||||
fi
|
||||
done
|
||||
ls -la docker/weed-volume-prebuilt/
|
||||
ls -la docker/weed-worker-prebuilt/
|
||||
|
||||
- name: Docker meta
|
||||
id: docker_meta
|
||||
@@ -236,7 +206,7 @@ jobs:
|
||||
org.opencontainers.image.vendor=Chris Lu
|
||||
- name: Set up QEMU
|
||||
if: matrix.platform != 'amd64'
|
||||
uses: docker/setup-qemu-action@v4.4.0
|
||||
uses: docker/setup-qemu-action@v4
|
||||
- name: Create BuildKit config
|
||||
run: |
|
||||
cat > /tmp/buildkitd.toml <<EOF
|
||||
@@ -250,13 +220,13 @@ jobs:
|
||||
buildkitd-config: /tmp/buildkitd.toml
|
||||
- name: Login to Docker Hub
|
||||
if: needs.setup.outputs.publish == 'true'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
- name: Login to GHCR
|
||||
if: needs.setup.outputs.publish == 'true'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
@@ -304,21 +274,21 @@ jobs:
|
||||
fi
|
||||
- name: Login to GHCR
|
||||
if: needs.setup.outputs.publish == 'true'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
password: ${{ secrets.GHCR_TOKEN }}
|
||||
- name: Checkout for local scan build
|
||||
if: needs.setup.outputs.publish != 'true'
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
with:
|
||||
ref: ${{ github.event_name == 'workflow_dispatch' && github.event.inputs.source_ref || github.ref }}
|
||||
- name: Download pre-built Rust binaries for local scan
|
||||
if: needs.setup.outputs.publish != 'true'
|
||||
uses: actions/download-artifact@v8
|
||||
with:
|
||||
pattern: rust-bins-*
|
||||
pattern: rust-volume-*
|
||||
merge-multiple: true
|
||||
path: ./rust-bins
|
||||
- name: Place Rust binaries in Docker context for local scan
|
||||
@@ -336,16 +306,7 @@ jobs:
|
||||
echo "Placed pre-built Rust binary for ${arch}"
|
||||
fi
|
||||
done
|
||||
mkdir -p docker/weed-worker-prebuilt
|
||||
for arch in amd64 arm64; do
|
||||
src="./rust-bins/weed-worker-${arch}"
|
||||
if [ -f "$src" ]; then
|
||||
cp "$src" "docker/weed-worker-prebuilt/weed-worker-${arch}"
|
||||
echo "Placed pre-built Rust worker for ${arch}"
|
||||
fi
|
||||
done
|
||||
ls -la docker/weed-volume-prebuilt/
|
||||
ls -la docker/weed-worker-prebuilt/
|
||||
- name: Create BuildKit config for local scan build
|
||||
if: needs.setup.outputs.publish != 'true'
|
||||
run: |
|
||||
@@ -405,7 +366,7 @@ jobs:
|
||||
output: trivy-results.sarif
|
||||
exit-code: '0'
|
||||
- name: Upload Trivy scan results to GitHub Security
|
||||
uses: github/codeql-action/upload-sarif@v4.38.2
|
||||
uses: github/codeql-action/upload-sarif@v4
|
||||
if: always()
|
||||
with:
|
||||
sarif_file: trivy-results.sarif
|
||||
@@ -441,19 +402,15 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
needs: [setup, build, trivy-scan]
|
||||
if: needs.setup.outputs.publish == 'true' && github.event_name != 'pull_request'
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
strategy:
|
||||
matrix:
|
||||
variant: ${{ fromJSON(needs.setup.outputs.variants) }}
|
||||
steps:
|
||||
- name: Checkout the signing action
|
||||
uses: actions/checkout@v7
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v6
|
||||
with:
|
||||
sparse-checkout: .github/actions
|
||||
persist-credentials: false
|
||||
|
||||
ref: ${{ github.event_name == 'workflow_dispatch' && github.event.inputs.source_ref || github.ref }}
|
||||
|
||||
- name: Configure variant
|
||||
id: config
|
||||
run: |
|
||||
@@ -472,12 +429,12 @@ jobs:
|
||||
ghcr.io/chrislusf/seaweedfs
|
||||
tags: type=raw,value=${{ github.event_name == 'workflow_dispatch' && github.event.inputs.image_tag || 'latest' }},suffix=${{ steps.config.outputs.tag_suffix }}
|
||||
- name: Login to Docker Hub
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
- name: Login to GHCR
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
@@ -486,31 +443,21 @@ jobs:
|
||||
run: |
|
||||
# Install crane for efficient multi-arch image copying
|
||||
cd $(mktemp -d)
|
||||
curl -sLO https://github.com/google/go-containerregistry/releases/download/v0.22.0/go-containerregistry_Linux_x86_64.tar.gz
|
||||
echo "edb74d53fad9a596860f59d1c5d04a43dfb5f441dc71f57060dd0bf39483c833 go-containerregistry_Linux_x86_64.tar.gz" | sha256sum -c -
|
||||
tar xzf go-containerregistry_Linux_x86_64.tar.gz crane
|
||||
curl -sL "https://github.com/google/go-containerregistry/releases/latest/download/go-containerregistry_Linux_x86_64.tar.gz" | tar xz
|
||||
sudo mv crane /usr/local/bin/
|
||||
crane version
|
||||
- name: Create and push manifest
|
||||
id: manifest
|
||||
env:
|
||||
BASE_TAG: ${{ github.event_name == 'workflow_dispatch' && github.event.inputs.image_tag || 'latest' }}
|
||||
run: |
|
||||
SUFFIX="${{ steps.config.outputs.tag_suffix }}"
|
||||
BASE_TAG="${{ github.event_name == 'workflow_dispatch' && github.event.inputs.image_tag || 'latest' }}"
|
||||
|
||||
# Create manifest on GHCR first (no rate limits)
|
||||
echo "Creating GHCR manifest (no rate limits)..."
|
||||
docker buildx imagetools create -t ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX} \
|
||||
--metadata-file /tmp/manifest.json \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-amd64 \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-arm64 \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-arm \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-386 \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-ppc64le \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-s390x
|
||||
# The copy and the signature below use the digest this run pushed, not whatever the tag points at by then.
|
||||
DIGEST=$(jq -er '."containerimage.descriptor".digest' /tmp/manifest.json)
|
||||
echo "digest=${DIGEST}" >> "$GITHUB_OUTPUT"
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-386
|
||||
|
||||
# Copy the complete multi-arch image from GHCR to Docker Hub
|
||||
# This only requires one pull from GHCR (no rate limit) and one push to Docker Hub
|
||||
@@ -546,25 +493,16 @@ jobs:
|
||||
# Use crane or skopeo to copy, fallback to docker if not available
|
||||
if command -v crane &> /dev/null; then
|
||||
echo "Using crane to copy..."
|
||||
retry_with_backoff crane copy ghcr.io/chrislusf/seaweedfs@${DIGEST} chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}
|
||||
retry_with_backoff crane copy ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX} chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}
|
||||
elif command -v skopeo &> /dev/null; then
|
||||
echo "Using skopeo to copy..."
|
||||
retry_with_backoff skopeo copy --all docker://ghcr.io/chrislusf/seaweedfs@${DIGEST} docker://chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}
|
||||
retry_with_backoff skopeo copy --all docker://ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX} docker://chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}
|
||||
else
|
||||
echo "Using docker buildx imagetools (pulling 6 images from Docker Hub)..."
|
||||
echo "Using docker buildx imagetools (pulling 4 images from Docker Hub)..."
|
||||
# Fallback: create manifest directly on Docker Hub (pulls from Docker Hub - rate limited)
|
||||
retry_with_backoff docker buildx imagetools create -t chrislusf/seaweedfs:${BASE_TAG}${SUFFIX} \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-amd64 \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-arm64 \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-arm \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-386 \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-ppc64le \
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-s390x
|
||||
ghcr.io/chrislusf/seaweedfs:${BASE_TAG}${SUFFIX}-386
|
||||
fi
|
||||
|
||||
- name: Sign
|
||||
uses: ./.github/actions/sign-image
|
||||
with:
|
||||
images: >-
|
||||
ghcr.io/chrislusf/seaweedfs@${{ steps.manifest.outputs.digest }}
|
||||
chrislusf/seaweedfs@${{ steps.manifest.outputs.digest }}
|
||||
|
||||
@@ -21,14 +21,11 @@ jobs:
|
||||
|
||||
build-large-release-container_foundationdb:
|
||||
runs-on: [ubuntu-latest]
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
|
||||
steps:
|
||||
-
|
||||
name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
-
|
||||
name: Docker meta
|
||||
id: docker_meta
|
||||
@@ -46,14 +43,14 @@ jobs:
|
||||
org.opencontainers.image.vendor=Chris Lu
|
||||
-
|
||||
name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@v4.4.0
|
||||
uses: docker/setup-qemu-action@v4
|
||||
-
|
||||
name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
-
|
||||
name: Login to Docker Hub
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
@@ -68,7 +65,6 @@ jobs:
|
||||
fi
|
||||
-
|
||||
name: Build
|
||||
id: build
|
||||
uses: docker/build-push-action@v7
|
||||
with:
|
||||
context: ./docker
|
||||
@@ -80,10 +76,4 @@ jobs:
|
||||
platforms: linux/amd64
|
||||
tags: ${{ steps.docker_meta.outputs.tags }}
|
||||
labels: ${{ steps.docker_meta.outputs.labels }}
|
||||
-
|
||||
name: Sign
|
||||
if: github.event_name != 'pull_request'
|
||||
uses: ./.github/actions/sign-image
|
||||
with:
|
||||
images: chrislusf/seaweedfs@${{ steps.build.outputs.digest }}
|
||||
|
||||
|
||||
@@ -29,11 +29,9 @@ on:
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
security-events: write
|
||||
|
||||
env:
|
||||
RELEASE_TAG: ${{ github.event_name == 'workflow_dispatch' && github.event.inputs.release_tag || github.ref_name }}
|
||||
IMAGE: ghcr.io/chrislusf/seaweedfs
|
||||
|
||||
# Limit concurrent builds to avoid rate limits
|
||||
concurrency:
|
||||
@@ -42,10 +40,9 @@ concurrency:
|
||||
|
||||
jobs:
|
||||
|
||||
# ── Pre-build the Rust binaries natively ────────────────────────────
|
||||
# The volume server and the Rust maintenance worker, cross-compiled for
|
||||
# amd64 and arm64 without QEMU, turning a 5-hour emulated cargo build into
|
||||
# ~15 minutes of native compilation.
|
||||
# ── Pre-build Rust volume server binaries natively ──────────────────
|
||||
# Cross-compiles for amd64 and arm64 without QEMU, turning a 5-hour
|
||||
# emulated cargo build into ~15 minutes of native compilation.
|
||||
build-rust-binaries:
|
||||
runs-on: ubuntu-22.04
|
||||
strategy:
|
||||
@@ -58,7 +55,10 @@ jobs:
|
||||
cross: true
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
@@ -78,32 +78,16 @@ jobs:
|
||||
echo "CFLAGS_aarch64_unknown_linux_musl=-U_FORTIFY_SOURCE" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
seaweed-worker/target/${{ matrix.target }}/release
|
||||
key: rust-docker-${{ matrix.target }}-${{ hashFiles('seaweed-volume/Cargo.lock', 'seaweed-worker/Cargo.lock') }}
|
||||
key: rust-docker-${{ matrix.target }}-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-docker-${{ matrix.target }}-
|
||||
|
||||
# lance's build scripts compile their own protos and look for a protoc.
|
||||
# Point them at the one protoc-bin-vendored ships, which seaweed-worker's
|
||||
# own build already uses, so no job depends on a system package and every
|
||||
# build sees the same version.
|
||||
- name: Use the vendored protoc
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo fetch
|
||||
# The version from the lock, not whatever else a restored cache holds.
|
||||
version=$(awk '/^name = "protoc-bin-vendored-linux-x86_64"$/{found=1; next} found && /^version = /{gsub(/"/,"",$3); print $3; exit}' Cargo.lock)
|
||||
test -n "$version" || { echo "protoc-bin-vendored-linux-x86_64 is not in Cargo.lock" >&2; exit 1; }
|
||||
protoc=$(find ~/.cargo/registry/src -path "*protoc-bin-vendored-linux-x86_64-$version/bin/protoc" | head -1)
|
||||
test -x "$protoc" || { echo "no vendored protoc $version in the registry" >&2; exit 1; }
|
||||
echo "PROTOC=$protoc" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Build large-disk variant
|
||||
env:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
@@ -120,70 +104,73 @@ jobs:
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features
|
||||
cp target/${{ matrix.target }}/release/weed-volume ../weed-volume-normal-${{ matrix.arch }}
|
||||
|
||||
- name: Build the Rust maintenance worker
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo build --release -p weed-lance-worker --target ${{ matrix.target }}
|
||||
cp target/${{ matrix.target }}/release/weed-worker ../weed-worker-${{ matrix.arch }}
|
||||
|
||||
- name: Upload artifacts
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: rust-bins-${{ matrix.arch }}
|
||||
name: rust-volume-${{ matrix.arch }}
|
||||
path: |
|
||||
weed-volume-large-disk-${{ matrix.arch }}
|
||||
weed-volume-normal-${{ matrix.arch }}
|
||||
weed-worker-${{ matrix.arch }}
|
||||
|
||||
# One job per (variant, platform) on a native runner, pushed by digest;
|
||||
# the merge job stitches the digests into one multi-arch tag.
|
||||
# ── Build Docker containers ─────────────────────────────────────────
|
||||
build:
|
||||
needs: [build-rust-binaries]
|
||||
runs-on: ${{ matrix.runner }}
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
fail-fast: false
|
||||
# Build sequentially to avoid rate limits
|
||||
max-parallel: 2
|
||||
matrix:
|
||||
include:
|
||||
# Normal volume - multi-arch
|
||||
- { variant: normal, tag_suffix: "", dockerfile: ./docker/Dockerfile.go_build, build_args: "", rust_variant: normal, platform: linux/amd64, arch: amd64, runner: ubuntu-latest, qemu: false }
|
||||
- { variant: normal, tag_suffix: "", dockerfile: ./docker/Dockerfile.go_build, build_args: "", rust_variant: normal, platform: linux/arm64, arch: arm64, runner: ubuntu-24.04-arm, qemu: false }
|
||||
- { variant: normal, tag_suffix: "", dockerfile: ./docker/Dockerfile.go_build, build_args: "", rust_variant: normal, platform: linux/arm/v7, arch: armv7, runner: ubuntu-latest, qemu: true }
|
||||
- { variant: normal, tag_suffix: "", dockerfile: ./docker/Dockerfile.go_build, build_args: "", rust_variant: normal, platform: linux/386, arch: i386, runner: ubuntu-latest, qemu: false }
|
||||
- { variant: normal, tag_suffix: "", dockerfile: ./docker/Dockerfile.go_build, build_args: "", rust_variant: normal, platform: linux/ppc64le, arch: ppc64le, runner: ubuntu-latest, qemu: true }
|
||||
- { variant: normal, tag_suffix: "", dockerfile: ./docker/Dockerfile.go_build, build_args: "", rust_variant: normal, platform: linux/s390x, arch: s390x, runner: ubuntu-latest, qemu: true }
|
||||
- variant: normal
|
||||
platforms: linux/amd64,linux/arm64,linux/arm/v7,linux/386
|
||||
dockerfile: ./docker/Dockerfile.go_build
|
||||
build_args: ""
|
||||
tag_suffix: ""
|
||||
rust_variant: normal
|
||||
|
||||
# Large disk - multi-arch
|
||||
- { variant: large_disk, tag_suffix: _large_disk, dockerfile: ./docker/Dockerfile.go_build, build_args: TAGS=5BytesOffset, rust_variant: large-disk, platform: linux/amd64, arch: amd64, runner: ubuntu-latest, qemu: false }
|
||||
- { variant: large_disk, tag_suffix: _large_disk, dockerfile: ./docker/Dockerfile.go_build, build_args: TAGS=5BytesOffset, rust_variant: large-disk, platform: linux/arm64, arch: arm64, runner: ubuntu-24.04-arm, qemu: false }
|
||||
- { variant: large_disk, tag_suffix: _large_disk, dockerfile: ./docker/Dockerfile.go_build, build_args: TAGS=5BytesOffset, rust_variant: large-disk, platform: linux/arm/v7, arch: armv7, runner: ubuntu-latest, qemu: true }
|
||||
- { variant: large_disk, tag_suffix: _large_disk, dockerfile: ./docker/Dockerfile.go_build, build_args: TAGS=5BytesOffset, rust_variant: large-disk, platform: linux/386, arch: i386, runner: ubuntu-latest, qemu: false }
|
||||
- { variant: large_disk, tag_suffix: _large_disk, dockerfile: ./docker/Dockerfile.go_build, build_args: TAGS=5BytesOffset, rust_variant: large-disk, platform: linux/ppc64le, arch: ppc64le, runner: ubuntu-latest, qemu: true }
|
||||
- { variant: large_disk, tag_suffix: _large_disk, dockerfile: ./docker/Dockerfile.go_build, build_args: TAGS=5BytesOffset, rust_variant: large-disk, platform: linux/s390x, arch: s390x, runner: ubuntu-latest, qemu: true }
|
||||
- variant: large_disk
|
||||
platforms: linux/amd64,linux/arm64,linux/arm/v7,linux/386
|
||||
dockerfile: ./docker/Dockerfile.go_build
|
||||
build_args: TAGS=5BytesOffset
|
||||
tag_suffix: _large_disk
|
||||
rust_variant: large-disk
|
||||
|
||||
# Full tags - multi-arch
|
||||
- { variant: full, tag_suffix: _full, dockerfile: ./docker/Dockerfile.go_build, build_args: "TAGS=elastic,gocdk,rclone,sqlite,tarantool,tikv,ydb", rust_variant: normal, platform: linux/amd64, arch: amd64, runner: ubuntu-latest, qemu: false }
|
||||
- { variant: full, tag_suffix: _full, dockerfile: ./docker/Dockerfile.go_build, build_args: "TAGS=elastic,gocdk,rclone,sqlite,tarantool,tikv,ydb", rust_variant: normal, platform: linux/arm64, arch: arm64, runner: ubuntu-24.04-arm, qemu: false }
|
||||
- variant: full
|
||||
platforms: linux/amd64,linux/arm64
|
||||
dockerfile: ./docker/Dockerfile.go_build
|
||||
build_args: TAGS=elastic,gocdk,rclone,sqlite,tarantool,tikv,ydb
|
||||
tag_suffix: _full
|
||||
rust_variant: normal
|
||||
|
||||
# Large disk + full tags - multi-arch
|
||||
- { variant: large_disk_full, tag_suffix: _large_disk_full, dockerfile: ./docker/Dockerfile.go_build, build_args: "TAGS=5BytesOffset,elastic,gocdk,rclone,sqlite,tarantool,tikv,ydb", rust_variant: large-disk, platform: linux/amd64, arch: amd64, runner: ubuntu-latest, qemu: false }
|
||||
- { variant: large_disk_full, tag_suffix: _large_disk_full, dockerfile: ./docker/Dockerfile.go_build, build_args: "TAGS=5BytesOffset,elastic,gocdk,rclone,sqlite,tarantool,tikv,ydb", rust_variant: large-disk, platform: linux/arm64, arch: arm64, runner: ubuntu-24.04-arm, qemu: false }
|
||||
- variant: large_disk_full
|
||||
platforms: linux/amd64,linux/arm64
|
||||
dockerfile: ./docker/Dockerfile.go_build
|
||||
build_args: TAGS=5BytesOffset,elastic,gocdk,rclone,sqlite,tarantool,tikv,ydb
|
||||
tag_suffix: _large_disk_full
|
||||
rust_variant: large-disk
|
||||
|
||||
# RocksDB large disk - amd64 only
|
||||
- { variant: rocksdb, tag_suffix: _large_disk_rocksdb, dockerfile: ./docker/Dockerfile.rocksdb_large, build_args: "", rust_variant: large-disk, platform: linux/amd64, arch: amd64, runner: ubuntu-latest, qemu: false }
|
||||
- variant: rocksdb
|
||||
platforms: linux/amd64
|
||||
dockerfile: ./docker/Dockerfile.rocksdb_large
|
||||
build_args: ""
|
||||
tag_suffix: _large_disk_rocksdb
|
||||
rust_variant: large-disk
|
||||
|
||||
steps:
|
||||
- name: Skip unselected variant
|
||||
if: github.event_name == 'workflow_dispatch' && github.event.inputs.variant != 'all' && github.event.inputs.variant != matrix.variant
|
||||
run: echo "Skipping ${{ matrix.variant }} (${{ matrix.platform }})" && exit 0
|
||||
|
||||
- name: Checkout
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Download pre-built Rust binaries
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: actions/download-artifact@v8
|
||||
with:
|
||||
pattern: rust-bins-*
|
||||
pattern: rust-volume-*
|
||||
merge-multiple: true
|
||||
path: ./rust-bins
|
||||
|
||||
@@ -198,45 +185,41 @@ jobs:
|
||||
echo "Placed pre-built Rust binary for ${arch}"
|
||||
fi
|
||||
done
|
||||
mkdir -p docker/weed-worker-prebuilt
|
||||
for arch in amd64 arm64; do
|
||||
src="./rust-bins/weed-worker-${arch}"
|
||||
if [ -f "$src" ]; then
|
||||
cp "$src" "docker/weed-worker-prebuilt/weed-worker-${arch}"
|
||||
echo "Placed pre-built Rust worker for ${arch}"
|
||||
fi
|
||||
done
|
||||
ls -la docker/weed-volume-prebuilt/
|
||||
ls -la docker/weed-worker-prebuilt/
|
||||
|
||||
- name: Free Disk Space
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
run: |
|
||||
echo "Available disk space before cleanup:"
|
||||
df -h
|
||||
sudo rm -rf /usr/share/dotnet /usr/local/lib/android /opt/ghc /opt/hostedtoolcache/CodeQL
|
||||
sudo apt-get clean
|
||||
sudo rm -rf /var/lib/apt/lists/*
|
||||
sudo docker system prune -af --volumes
|
||||
[ -d ~/.cache/go-build ] && rm -rf ~/.cache/go-build || true
|
||||
[ -d /go/pkg ] && rm -rf /go/pkg || true
|
||||
echo "Available disk space after cleanup:"
|
||||
df -h
|
||||
|
||||
|
||||
- name: Docker meta
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
id: docker_meta
|
||||
uses: docker/metadata-action@v6
|
||||
with:
|
||||
images: ${{ env.IMAGE }}
|
||||
images: |
|
||||
chrislusf/seaweedfs
|
||||
ghcr.io/chrislusf/seaweedfs
|
||||
tags: type=raw,value=${{ env.RELEASE_TAG }}${{ matrix.tag_suffix }}
|
||||
flavor: latest=false
|
||||
labels: |
|
||||
org.opencontainers.image.title=seaweedfs
|
||||
org.opencontainers.image.description=SeaweedFS is a distributed storage system for blobs, objects, files, and data lake, to store and serve billions of files fast!
|
||||
org.opencontainers.image.vendor=Chris Lu
|
||||
|
||||
|
||||
- name: Set up QEMU
|
||||
if: (github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant) && matrix.qemu
|
||||
uses: docker/setup-qemu-action@v4.4.0
|
||||
|
||||
if: (github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant) && contains(matrix.platforms, 'arm')
|
||||
uses: docker/setup-qemu-action@v4
|
||||
|
||||
- name: Create BuildKit config
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
run: |
|
||||
@@ -244,312 +227,150 @@ jobs:
|
||||
[registry."docker.io"]
|
||||
mirrors = ["https://mirror.gcr.io"]
|
||||
EOF
|
||||
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: docker/setup-buildx-action@v4
|
||||
with:
|
||||
buildkitd-config: /tmp/buildkitd.toml
|
||||
|
||||
|
||||
- name: Login to Docker Hub
|
||||
if: (github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant) && github.event_name != 'pull_request'
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
- name: Login to GHCR
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: docker/login-action@v4.6.0
|
||||
if: (github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant) && github.event_name != 'pull_request'
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
password: ${{ secrets.GHCR_TOKEN }}
|
||||
|
||||
- name: Build and push ${{ matrix.variant }} (${{ matrix.platform }})
|
||||
|
||||
- name: Build and push ${{ matrix.variant }}
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
id: build
|
||||
uses: docker/build-push-action@v7
|
||||
env:
|
||||
DOCKER_BUILDKIT: 1
|
||||
with:
|
||||
context: ./docker
|
||||
push: ${{ github.event_name != 'pull_request' }}
|
||||
file: ${{ matrix.dockerfile }}
|
||||
platforms: ${{ matrix.platform }}
|
||||
platforms: ${{ matrix.platforms }}
|
||||
# Push to GHCR to avoid Docker Hub rate limits on pulls
|
||||
tags: |
|
||||
ghcr.io/chrislusf/seaweedfs:${{ env.RELEASE_TAG }}${{ matrix.tag_suffix }}
|
||||
labels: ${{ steps.docker_meta.outputs.labels }}
|
||||
# Flat single-platform manifest so imagetools create assembles cleanly.
|
||||
provenance: false
|
||||
outputs: type=image,name=${{ env.IMAGE }},push-by-digest=true,name-canonical=true,push=true
|
||||
cache-from: type=gha,scope=${{ matrix.variant }}-${{ matrix.arch }}
|
||||
# max only for rocksdb: its RocksDB compile is sha-independent and worth
|
||||
# keeping; go-build layers are sha-busted every release, so min elsewhere.
|
||||
cache-to: type=gha,mode=${{ matrix.variant == 'rocksdb' && 'max' || 'min' }},scope=${{ matrix.variant }}-${{ matrix.arch }}
|
||||
cache-from: type=gha,scope=${{ matrix.variant }}
|
||||
cache-to: type=gha,mode=max,scope=${{ matrix.variant }}
|
||||
build-args: |
|
||||
${{ matrix.build_args }}
|
||||
BUILDKIT_INLINE_CACHE=1
|
||||
BRANCH=${{ github.sha }}
|
||||
${{ matrix.variant == 'rocksdb' && format('ROCKSDB_VERSION={0}', github.event.inputs.rocksdb_version || 'v10.10.1') || '' }}
|
||||
|
||||
- name: Export digest
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
|
||||
- name: Clean up build artifacts
|
||||
if: always() && (github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant)
|
||||
run: |
|
||||
mkdir -p /tmp/digests
|
||||
digest="${{ steps.build.outputs.digest }}"
|
||||
touch "/tmp/digests/${digest#sha256:}"
|
||||
sudo docker system prune -f
|
||||
sudo rm -rf /tmp/go-build*
|
||||
|
||||
- name: Upload digest
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: digest-${{ matrix.variant }}-${{ matrix.arch }}
|
||||
path: /tmp/digests/*
|
||||
if-no-files-found: error
|
||||
retention-days: 1
|
||||
|
||||
# Assemble each variant's per-platform digests into one tag, mirror it to
|
||||
# Docker Hub, and sign the result on both registries.
|
||||
merge:
|
||||
needs: [build]
|
||||
copy-to-dockerhub:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
needs: [build]
|
||||
if: github.event_name != 'pull_request'
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
variant: [normal, large_disk, full, large_disk_full, rocksdb]
|
||||
include:
|
||||
- { variant: normal, tag_suffix: "" }
|
||||
- { variant: large_disk, tag_suffix: _large_disk }
|
||||
- { variant: full, tag_suffix: _full }
|
||||
- { variant: large_disk_full, tag_suffix: _large_disk_full }
|
||||
- { variant: rocksdb, tag_suffix: _large_disk_rocksdb }
|
||||
- variant: normal
|
||||
tag_suffix: ""
|
||||
- variant: large_disk
|
||||
tag_suffix: _large_disk
|
||||
- variant: full
|
||||
tag_suffix: _full
|
||||
- variant: large_disk_full
|
||||
tag_suffix: _large_disk_full
|
||||
- variant: rocksdb
|
||||
tag_suffix: _large_disk_rocksdb
|
||||
|
||||
steps:
|
||||
- name: Checkout the signing action
|
||||
- name: Login to Docker Hub
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: actions/checkout@v7
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
sparse-checkout: .github/actions
|
||||
persist-credentials: false
|
||||
|
||||
- name: Download digests
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: actions/download-artifact@v8
|
||||
with:
|
||||
pattern: digest-${{ matrix.variant }}-*
|
||||
merge-multiple: true
|
||||
path: /tmp/digests
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
- name: Login to GHCR
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: docker/login-action@v4.6.0
|
||||
uses: docker/login-action@v4.1.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
password: ${{ secrets.GHCR_TOKEN }}
|
||||
|
||||
- name: Create multi-arch tag on GHCR
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
id: manifest
|
||||
working-directory: /tmp/digests
|
||||
run: |
|
||||
docker buildx imagetools create \
|
||||
-t ${{ env.IMAGE }}:${{ env.RELEASE_TAG }}${{ matrix.tag_suffix }} \
|
||||
--metadata-file /tmp/manifest.json \
|
||||
$(printf '${{ env.IMAGE }}@sha256:%s ' *)
|
||||
docker buildx imagetools inspect ${{ env.IMAGE }}:${{ env.RELEASE_TAG }}${{ matrix.tag_suffix }}
|
||||
# The copy and the signature below use the digest this run pushed, not whatever the tag points at by then.
|
||||
digest=$(jq -er '."containerimage.descriptor".digest' /tmp/manifest.json)
|
||||
echo "digest=${digest}" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Login to Docker Hub
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: docker/login-action@v4.6.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
|
||||
- name: Install crane
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
run: |
|
||||
cd $(mktemp -d)
|
||||
curl -sLO https://github.com/google/go-containerregistry/releases/download/v0.22.0/go-containerregistry_Linux_x86_64.tar.gz
|
||||
echo "edb74d53fad9a596860f59d1c5d04a43dfb5f441dc71f57060dd0bf39483c833 go-containerregistry_Linux_x86_64.tar.gz" | sha256sum -c -
|
||||
tar xzf go-containerregistry_Linux_x86_64.tar.gz crane
|
||||
curl -sL "https://github.com/google/go-containerregistry/releases/latest/download/go-containerregistry_Linux_x86_64.tar.gz" | tar xz
|
||||
sudo mv crane /usr/local/bin/
|
||||
crane version
|
||||
|
||||
- name: Copy ${{ matrix.variant }} to Docker Hub
|
||||
|
||||
- name: Copy ${{ matrix.variant }} from GHCR to Docker Hub
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
run: |
|
||||
# Function to retry with exponential backoff
|
||||
retry_with_backoff() {
|
||||
local max_attempts=5
|
||||
local timeout=1
|
||||
local attempt=1
|
||||
local exit_code=0
|
||||
|
||||
while [ $attempt -le $max_attempts ]; do
|
||||
if "$@"; then
|
||||
return 0
|
||||
else
|
||||
exit_code=$?
|
||||
fi
|
||||
|
||||
if [ $attempt -lt $max_attempts ]; then
|
||||
echo "Attempt $attempt failed. Retrying in ${timeout}s..." >&2
|
||||
sleep $timeout
|
||||
timeout=$((timeout * 2))
|
||||
fi
|
||||
|
||||
attempt=$((attempt + 1))
|
||||
done
|
||||
|
||||
echo "Command failed after $max_attempts attempts" >&2
|
||||
return $exit_code
|
||||
}
|
||||
|
||||
|
||||
# Copy multi-arch image from GHCR to Docker Hub with retry
|
||||
# This is much more efficient than pulling/pushing individual arch images
|
||||
echo "Copying ${{ matrix.variant }} from GHCR to Docker Hub..."
|
||||
retry_with_backoff crane copy \
|
||||
${{ env.IMAGE }}@${{ steps.manifest.outputs.digest }} \
|
||||
ghcr.io/chrislusf/seaweedfs:${{ env.RELEASE_TAG }}${{ matrix.tag_suffix }} \
|
||||
chrislusf/seaweedfs:${{ env.RELEASE_TAG }}${{ matrix.tag_suffix }}
|
||||
echo "Copied ${{ matrix.variant }} to Docker Hub"
|
||||
|
||||
- name: Sign ${{ matrix.variant }}
|
||||
if: github.event_name != 'workflow_dispatch' || github.event.inputs.variant == 'all' || github.event.inputs.variant == matrix.variant
|
||||
uses: ./.github/actions/sign-image
|
||||
with:
|
||||
images: >-
|
||||
${{ env.IMAGE }}@${{ steps.manifest.outputs.digest }}
|
||||
chrislusf/seaweedfs@${{ steps.manifest.outputs.digest }}
|
||||
|
||||
# Report-only trivy scan: uploads fixable HIGH/CRITICAL findings to GitHub
|
||||
# Security for visibility, but never blocks the release. Releases (including
|
||||
# `latest`) ship regardless — vulnerabilities are tracked, not gated, since
|
||||
# we sometimes need to publish through known findings (e.g. unfixed upstream
|
||||
# CVE, base-image lag).
|
||||
trivy-scan:
|
||||
runs-on: ubuntu-latest
|
||||
needs: [merge]
|
||||
if: github.event_name == 'push'
|
||||
continue-on-error: true
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- source_suffix: ""
|
||||
variant: normal
|
||||
- source_suffix: _large_disk
|
||||
variant: large_disk
|
||||
steps:
|
||||
- name: Login to GHCR
|
||||
uses: docker/login-action@v4.6.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
password: ${{ secrets.GHCR_TOKEN }}
|
||||
|
||||
- name: Trivy report (${{ matrix.variant }})
|
||||
# Pin to SHA - mutable tags were compromised (GHSA-69fq-xp46-6x23)
|
||||
uses: aquasecurity/trivy-action@ed142fd0673e97e23eac54620cfb913e5ce36c25 # v0.36.0
|
||||
with:
|
||||
scan-type: image
|
||||
# Scan the multi-arch tag on GHCR (already pushed by the build job).
|
||||
# Trivy scans the runner's native platform; OS packages are identical
|
||||
# across architectures since they all share the same alpine base.
|
||||
image-ref: ${{ env.IMAGE }}:${{ env.RELEASE_TAG }}${{ matrix.source_suffix }}
|
||||
scanners: vuln
|
||||
vuln-type: os,library
|
||||
severity: HIGH,CRITICAL
|
||||
ignore-unfixed: true
|
||||
limit-severities-for-sarif: true
|
||||
format: sarif
|
||||
output: trivy-results.sarif
|
||||
exit-code: '0'
|
||||
|
||||
- name: Upload Trivy scan results to GitHub Security
|
||||
if: always()
|
||||
uses: github/codeql-action/upload-sarif@v4.38.2
|
||||
with:
|
||||
sarif_file: trivy-results.sarif
|
||||
category: trivy-${{ matrix.variant }}
|
||||
|
||||
# Point `latest` (and `latest_large_disk`) at the just-released versioned
|
||||
# image. crane tag adds an extra tag to an existing manifest — no rebuild,
|
||||
# no QEMU, no separate workflow. Replaces the old container_latest.yml
|
||||
# rebuild that often failed or lagged behind the release. Independent of
|
||||
# trivy-scan: vuln findings are reported but do not block `latest`. The
|
||||
# cosign signature is attached to the digest, so `latest` carries it too.
|
||||
tag-latest:
|
||||
runs-on: ubuntu-latest
|
||||
needs: [merge]
|
||||
if: github.event_name == 'push'
|
||||
strategy:
|
||||
matrix:
|
||||
include:
|
||||
- source_suffix: ""
|
||||
latest_tag: latest
|
||||
- source_suffix: _large_disk
|
||||
latest_tag: latest_large_disk
|
||||
steps:
|
||||
- name: Login to Docker Hub
|
||||
uses: docker/login-action@v4.6.0
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
- name: Login to GHCR
|
||||
uses: docker/login-action@v4.6.0
|
||||
with:
|
||||
registry: ghcr.io
|
||||
username: ${{ secrets.GHCR_USERNAME }}
|
||||
password: ${{ secrets.GHCR_TOKEN }}
|
||||
|
||||
- name: Install crane
|
||||
run: |
|
||||
cd $(mktemp -d)
|
||||
curl -sLO https://github.com/google/go-containerregistry/releases/download/v0.22.0/go-containerregistry_Linux_x86_64.tar.gz
|
||||
echo "edb74d53fad9a596860f59d1c5d04a43dfb5f441dc71f57060dd0bf39483c833 go-containerregistry_Linux_x86_64.tar.gz" | sha256sum -c -
|
||||
tar xzf go-containerregistry_Linux_x86_64.tar.gz crane
|
||||
sudo mv crane /usr/local/bin/
|
||||
crane version
|
||||
|
||||
- name: Re-tag ${{ env.RELEASE_TAG }}${{ matrix.source_suffix }} as ${{ matrix.latest_tag }}
|
||||
run: |
|
||||
retry_with_backoff() {
|
||||
local max_attempts=5
|
||||
local timeout=1
|
||||
local attempt=1
|
||||
local exit_code=0
|
||||
while [ $attempt -le $max_attempts ]; do
|
||||
if "$@"; then
|
||||
return 0
|
||||
else
|
||||
exit_code=$?
|
||||
fi
|
||||
if [ $attempt -lt $max_attempts ]; then
|
||||
echo "Attempt $attempt failed. Retrying in ${timeout}s..." >&2
|
||||
sleep $timeout
|
||||
timeout=$((timeout * 2))
|
||||
fi
|
||||
attempt=$((attempt + 1))
|
||||
done
|
||||
echo "Command failed after $max_attempts attempts" >&2
|
||||
return $exit_code
|
||||
}
|
||||
|
||||
SRC_TAG="${{ env.RELEASE_TAG }}${{ matrix.source_suffix }}"
|
||||
DST_TAG="${{ matrix.latest_tag }}"
|
||||
|
||||
echo "Tagging ${{ env.IMAGE }}:${SRC_TAG} as ${DST_TAG}"
|
||||
retry_with_backoff crane tag "${{ env.IMAGE }}:${SRC_TAG}" "${DST_TAG}"
|
||||
|
||||
echo "Tagging chrislusf/seaweedfs:${SRC_TAG} as ${DST_TAG}"
|
||||
retry_with_backoff crane tag "chrislusf/seaweedfs:${SRC_TAG}" "${DST_TAG}"
|
||||
|
||||
echo "✓ Successfully copied ${{ matrix.variant }} to Docker Hub"
|
||||
|
||||
helm-release:
|
||||
runs-on: ubuntu-latest
|
||||
needs: [build]
|
||||
needs: [copy-to-dockerhub]
|
||||
if: github.event_name == 'push' || github.event_name == 'workflow_dispatch'
|
||||
permissions:
|
||||
contents: write
|
||||
pages: write
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
- name: Publish Helm charts
|
||||
uses: stefanprodan/helm-gh-pages@v1.7.0
|
||||
with:
|
||||
with:
|
||||
token: ${{ secrets.GITHUB_TOKEN }}
|
||||
charts_dir: k8s/charts
|
||||
target_dir: helm
|
||||
|
||||
@@ -22,13 +22,10 @@ permissions:
|
||||
jobs:
|
||||
build-rocksdb-image:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: read
|
||||
id-token: write
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1 # v2
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd # v2
|
||||
|
||||
- name: Prepare Docker tag
|
||||
id: tag
|
||||
@@ -85,19 +82,18 @@ jobs:
|
||||
echo "seaweedfs_ref=$seaweed" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Set up QEMU
|
||||
uses: docker/setup-qemu-action@99012661954931238ded8c8b007157a8430204e1 # v1
|
||||
uses: docker/setup-qemu-action@ce360397dd3f832beb865e1373c09c0e9f86d70a # v1
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@4d04d5d9486b7bd6fa91e7baf45bbb4f8b9deedd # v1
|
||||
|
||||
- name: Login to Docker Hub
|
||||
uses: docker/login-action@dbcb813823bdd20940b903addbd779551569679f # v1
|
||||
uses: docker/login-action@4907a6ddec9925e35a0a9e82d7399ccc52663121 # v1
|
||||
with:
|
||||
username: ${{ secrets.DOCKER_USERNAME }}
|
||||
password: ${{ secrets.DOCKER_PASSWORD }}
|
||||
|
||||
- name: Build and push image
|
||||
id: build
|
||||
uses: docker/build-push-action@bcafcacb16a39f128d818304e6c9c0c18556b85f # v2
|
||||
with:
|
||||
context: ./docker
|
||||
@@ -112,8 +108,3 @@ jobs:
|
||||
org.opencontainers.image.title=seaweedfs
|
||||
org.opencontainers.image.description=SeaweedFS is a distributed storage system for blobs, objects, files, and data lake, to store and serve billions of files fast!
|
||||
org.opencontainers.image.vendor=Chris Lu
|
||||
|
||||
- name: Sign
|
||||
uses: ./.github/actions/sign-image
|
||||
with:
|
||||
images: chrislusf/seaweedfs@${{ steps.build.outputs.digest }}
|
||||
|
||||
@@ -21,62 +21,22 @@ jobs:
|
||||
deploy:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'telemetry/server/go.mod'
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Build Telemetry Server
|
||||
if: github.event_name == 'workflow_dispatch' && inputs.deploy
|
||||
run: |
|
||||
# telemetry/server is its own Go module; build from within it
|
||||
cd telemetry/server
|
||||
go mod tidy
|
||||
echo "Building telemetry server..."
|
||||
CGO_ENABLED=0 GOOS=linux GOARCH=amd64 go build -o ../../telemetry-server .
|
||||
cd ../..
|
||||
GOOS=linux GOARCH=amd64 go build -o telemetry-server ./telemetry/server/main.go
|
||||
ls -la telemetry-server
|
||||
echo "Build completed successfully"
|
||||
|
||||
- name: Generate Service Configuration
|
||||
if: github.event_name == 'workflow_dispatch' && (inputs.setup || inputs.deploy)
|
||||
env:
|
||||
REMOTE_USER: ${{ secrets.TELEMETRY_USER }}
|
||||
run: |
|
||||
# Create systemd service file
|
||||
echo "
|
||||
[Unit]
|
||||
Description=SeaweedFS Telemetry Server
|
||||
After=network.target
|
||||
|
||||
[Service]
|
||||
Type=simple
|
||||
User=$REMOTE_USER
|
||||
WorkingDirectory=/home/$REMOTE_USER/seaweedfs-telemetry
|
||||
ExecStart=/bin/sh -c 'exec /home/$REMOTE_USER/seaweedfs-telemetry/bin/telemetry-server -port=8353 >>/home/$REMOTE_USER/seaweedfs-telemetry/logs/telemetry.log 2>>/home/$REMOTE_USER/seaweedfs-telemetry/logs/telemetry.error.log'
|
||||
Restart=always
|
||||
RestartSec=5
|
||||
|
||||
[Install]
|
||||
WantedBy=multi-user.target" > telemetry.service
|
||||
|
||||
# Setup logrotate configuration
|
||||
echo "# SeaweedFS Telemetry service log rotation
|
||||
/home/$REMOTE_USER/seaweedfs-telemetry/logs/*.log {
|
||||
daily
|
||||
rotate 30
|
||||
compress
|
||||
delaycompress
|
||||
missingok
|
||||
notifempty
|
||||
create 644 $REMOTE_USER $REMOTE_USER
|
||||
postrotate
|
||||
systemctl restart telemetry.service
|
||||
endscript
|
||||
}" > telemetry_logrotate
|
||||
|
||||
- name: First-time Server Setup
|
||||
if: github.event_name == 'workflow_dispatch' && inputs.setup
|
||||
env:
|
||||
@@ -98,6 +58,40 @@ jobs:
|
||||
touch ~/seaweedfs-telemetry/logs/telemetry.log ~/seaweedfs-telemetry/logs/telemetry.error.log && \
|
||||
chmod 644 ~/seaweedfs-telemetry/logs/*.log"
|
||||
|
||||
# Create systemd service file
|
||||
echo "
|
||||
[Unit]
|
||||
Description=SeaweedFS Telemetry Server
|
||||
After=network.target
|
||||
|
||||
[Service]
|
||||
Type=simple
|
||||
User=$REMOTE_USER
|
||||
WorkingDirectory=/home/$REMOTE_USER/seaweedfs-telemetry
|
||||
ExecStart=/home/$REMOTE_USER/seaweedfs-telemetry/bin/telemetry-server -port=8353
|
||||
Restart=always
|
||||
RestartSec=5
|
||||
StandardOutput=append:/home/$REMOTE_USER/seaweedfs-telemetry/logs/telemetry.log
|
||||
StandardError=append:/home/$REMOTE_USER/seaweedfs-telemetry/logs/telemetry.error.log
|
||||
|
||||
[Install]
|
||||
WantedBy=multi-user.target" > telemetry.service
|
||||
|
||||
# Setup logrotate configuration
|
||||
echo "# SeaweedFS Telemetry service log rotation
|
||||
/home/$REMOTE_USER/seaweedfs-telemetry/logs/*.log {
|
||||
daily
|
||||
rotate 30
|
||||
compress
|
||||
delaycompress
|
||||
missingok
|
||||
notifempty
|
||||
create 644 $REMOTE_USER $REMOTE_USER
|
||||
postrotate
|
||||
systemctl restart telemetry.service
|
||||
endscript
|
||||
}" > telemetry_logrotate
|
||||
|
||||
# Copy configuration files
|
||||
scp -i ~/.ssh/deploy_key telemetry/grafana-dashboard.json $REMOTE_USER@$REMOTE_HOST:~/seaweedfs-telemetry/
|
||||
scp -i ~/.ssh/deploy_key telemetry/prometheus.yml $REMOTE_USER@$REMOTE_HOST:~/seaweedfs-telemetry/
|
||||
@@ -140,18 +134,11 @@ jobs:
|
||||
scp -i ~/.ssh/deploy_key telemetry/grafana-dashboard.json $REMOTE_USER@$REMOTE_HOST:~/seaweedfs-telemetry/
|
||||
scp -i ~/.ssh/deploy_key telemetry/prometheus.yml $REMOTE_USER@$REMOTE_HOST:~/seaweedfs-telemetry/
|
||||
|
||||
# Copy updated service and logrotate files
|
||||
scp -i ~/.ssh/deploy_key telemetry.service telemetry_logrotate $REMOTE_USER@$REMOTE_HOST:~/seaweedfs-telemetry/
|
||||
|
||||
# Check if service exists and deploy accordingly
|
||||
ssh -i ~/.ssh/deploy_key $REMOTE_USER@$REMOTE_HOST "
|
||||
if systemctl list-unit-files telemetry.service >/dev/null 2>&1; then
|
||||
echo 'Service exists, performing update...'
|
||||
set -e
|
||||
sudo systemctl stop telemetry.service
|
||||
sudo mv ~/seaweedfs-telemetry/telemetry.service /etc/systemd/system/
|
||||
sudo mv ~/seaweedfs-telemetry/telemetry_logrotate /etc/logrotate.d/seaweedfs-telemetry
|
||||
sudo systemctl daemon-reload
|
||||
mkdir -p ~/seaweedfs-telemetry/bin
|
||||
mv ~/seaweedfs-telemetry/tmp/telemetry-server ~/seaweedfs-telemetry/bin/
|
||||
chmod +x ~/seaweedfs-telemetry/bin/telemetry-server
|
||||
|
||||
@@ -9,6 +9,6 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: 'Checkout Repository'
|
||||
uses: actions/checkout@3d3c42e5aac5ba805825da76410c181273ba90b1
|
||||
uses: actions/checkout@de0fac2e4500dabe0009e67214ff5f5447ce83dd
|
||||
- name: 'Dependency Review'
|
||||
uses: actions/dependency-review-action@a1d282b36b6f3519aa1f3fc636f609c47dddb294
|
||||
uses: actions/dependency-review-action@2031cfc080254a8a887f58cffee85186f0e49e48
|
||||
|
||||
+12
-34
@@ -3,20 +3,8 @@ name: "End to End"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'docker/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/e2e.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'docker/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/e2e.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/e2e
|
||||
@@ -36,23 +24,18 @@ jobs:
|
||||
timeout-minutes: 30
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Cache Docker layers
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: /tmp/.buildx-cache
|
||||
key: ${{ runner.os }}-buildx-e2e-${{ github.sha }}
|
||||
@@ -61,22 +44,25 @@ jobs:
|
||||
|
||||
- name: Install dependencies
|
||||
run: |
|
||||
# Use faster mirrors and install with timeout
|
||||
sudo rm -f /etc/apt/sources.list.d/azure-cli.list /etc/apt/sources.list.d/microsoft-prod.list
|
||||
# Same helper the e2e image installs through: the runner's own list is
|
||||
# azure-only too, and an outage there fails this step outright.
|
||||
sudo ./apt-install fuse
|
||||
echo "deb http://azure.archive.ubuntu.com/ubuntu/ $(lsb_release -cs) main restricted universe multiverse" | sudo tee /etc/apt/sources.list
|
||||
echo "deb http://azure.archive.ubuntu.com/ubuntu/ $(lsb_release -cs)-updates main restricted universe multiverse" | sudo tee -a /etc/apt/sources.list
|
||||
|
||||
sudo apt-get update --fix-missing
|
||||
sudo DEBIAN_FRONTEND=noninteractive apt-get install -y --no-install-recommends fuse
|
||||
|
||||
# Verify FUSE installation
|
||||
echo "FUSE version: $(fusermount --version 2>&1 || echo 'fusermount not found')"
|
||||
echo "FUSE device: $(ls -la /dev/fuse 2>&1 || echo '/dev/fuse not found')"
|
||||
|
||||
- name: Start SeaweedFS
|
||||
timeout-minutes: 15
|
||||
timeout-minutes: 10
|
||||
run: |
|
||||
# Enable Docker buildkit for better caching
|
||||
export DOCKER_BUILDKIT=1
|
||||
export COMPOSE_DOCKER_CLI_BUILD=1
|
||||
|
||||
|
||||
# Build with retry logic
|
||||
for i in {1..3}; do
|
||||
echo "Build attempt $i/3"
|
||||
@@ -91,18 +77,10 @@ jobs:
|
||||
sleep 30
|
||||
fi
|
||||
done
|
||||
|
||||
|
||||
# Start services with wait
|
||||
docker compose -f ./compose/e2e-mount.yml up --wait
|
||||
|
||||
- name: Rotate buildx cache
|
||||
if: always()
|
||||
run: |
|
||||
# Without this, --cache-to writes to .buildx-cache-new but actions/cache only
|
||||
# uploads .buildx-cache, so layers (notably the slow apt RUN) never persist.
|
||||
rm -rf /tmp/.buildx-cache
|
||||
if [ -d /tmp/.buildx-cache-new ]; then mv /tmp/.buildx-cache-new /tmp/.buildx-cache; fi
|
||||
|
||||
- name: Run FIO 4k
|
||||
timeout-minutes: 15
|
||||
run: |
|
||||
|
||||
@@ -3,20 +3,8 @@ name: "EC Integration Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/erasure_coding/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/ec-integration-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/erasure_coding/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/ec-integration-tests.yml'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
@@ -28,13 +16,13 @@ jobs:
|
||||
timeout-minutes: 30
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Build weed binary
|
||||
run: |
|
||||
@@ -43,10 +31,7 @@ jobs:
|
||||
- name: Run EC Integration Tests
|
||||
working-directory: test/erasure_coding
|
||||
run: |
|
||||
# The suite now includes the interruption matrix and runs close to Go's
|
||||
# default 10m binary timeout on slower runners; bound it by the job's
|
||||
# 30m budget instead.
|
||||
go test -v -timeout 25m
|
||||
go test -v
|
||||
|
||||
- name: Collect server logs on failure
|
||||
if: failure()
|
||||
|
||||
@@ -0,0 +1,49 @@
|
||||
name: EC Integration Tests
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/admin/**'
|
||||
- 'weed/worker/**'
|
||||
- 'test/erasure_coding/admin_dockertest/**'
|
||||
- '.github/workflows/ec-integration.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/admin/**'
|
||||
- 'weed/worker/**'
|
||||
- 'test/erasure_coding/admin_dockertest/**'
|
||||
- '.github/workflows/ec-integration.yml'
|
||||
|
||||
jobs:
|
||||
ec-integration-test:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 15
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Build weed binary
|
||||
run: |
|
||||
cd weed
|
||||
go build -o ../weed_bin
|
||||
|
||||
- name: Run EC integration tests
|
||||
run: |
|
||||
cd test/erasure_coding/admin_dockertest
|
||||
go test -v -timeout 15m ec_integration_test.go
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: ec-test-logs
|
||||
path: test/erasure_coding/admin_dockertest/tmp/logs/
|
||||
retention-days: 7
|
||||
@@ -8,7 +8,6 @@ on:
|
||||
- 'weed/cluster/**'
|
||||
- 'test/fuse_dlm/**'
|
||||
- '.github/workflows/fuse-dlm-integration.yml'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
push:
|
||||
branches: [master]
|
||||
paths:
|
||||
@@ -16,7 +15,6 @@ on:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/cluster/**'
|
||||
- 'test/fuse_dlm/**'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/fuse-dlm-integration
|
||||
@@ -33,24 +31,20 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Configure FUSE
|
||||
- name: Install FUSE dependencies
|
||||
run: |
|
||||
# Nothing to install: fuse3 ships fusermount3 and is pre-installed,
|
||||
# and go-fuse is pure Go, so the libfuse headers were never linked
|
||||
# against.
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y libfuse3-dev
|
||||
echo 'user_allow_other' | sudo tee -a /etc/fuse.conf
|
||||
sudo chmod 644 /etc/fuse.conf
|
||||
|
||||
- name: Repair the fusermount3 setuid bit
|
||||
uses: ./.github/actions/fix-fusermount-setuid
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: go build -o weed/weed -buildvcs=false ./weed
|
||||
|
||||
|
||||
@@ -1,76 +0,0 @@
|
||||
name: "FUSE Volume Server Failover Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/command/mount*.go'
|
||||
- 'weed/mount/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/wdclient/**'
|
||||
- 'weed/operation/upload_content.go'
|
||||
- 'test/fuse_failover/**'
|
||||
- '.github/workflows/fuse-failover.yml'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
push:
|
||||
branches: [master]
|
||||
paths:
|
||||
- 'weed/command/mount*.go'
|
||||
- 'weed/mount/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/wdclient/**'
|
||||
- 'weed/operation/upload_content.go'
|
||||
- 'test/fuse_failover/**'
|
||||
- '.github/workflows/fuse-failover.yml'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/fuse-failover
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
fuse-failover:
|
||||
name: FUSE Volume Server Failover
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 40
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Configure FUSE
|
||||
run: |
|
||||
# Nothing to install: fuse3 ships fusermount3 and is pre-installed,
|
||||
# and go-fuse is pure Go, so the libfuse headers were never linked
|
||||
# against.
|
||||
echo 'user_allow_other' | sudo tee -a /etc/fuse.conf
|
||||
sudo chmod 644 /etc/fuse.conf
|
||||
|
||||
- name: Repair the fusermount3 setuid bit
|
||||
uses: ./.github/actions/fix-fusermount-setuid
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: go build -o weed/weed -buildvcs=false ./weed
|
||||
|
||||
- name: Run failover integration tests
|
||||
timeout-minutes: 35
|
||||
env:
|
||||
WEED_BINARY: ${{ github.workspace }}/weed/weed
|
||||
run: go test -v -count=1 -timeout=30m ./test/fuse_failover/...
|
||||
|
||||
- name: Upload logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: fuse-failover-test-logs
|
||||
path: /tmp/seaweedfs-fuse-failover-logs/
|
||||
retention-days: 3
|
||||
@@ -7,14 +7,12 @@ on:
|
||||
- 'weed/**'
|
||||
- 'test/fuse_integration/**'
|
||||
- '.github/workflows/fuse-integration.yml'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
pull_request:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/fuse_integration/**'
|
||||
- '.github/workflows/fuse-integration.yml'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/fuse-integration
|
||||
@@ -31,17 +29,19 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Configure FUSE
|
||||
- name: Install FUSE and dependencies
|
||||
run: |
|
||||
# Nothing to install: fuse3 ships fusermount3 and is pre-installed, and
|
||||
# go-fuse is pure Go, so the libfuse headers were never linked against.
|
||||
sudo apt-get update
|
||||
# fuse3 is pre-installed on ubuntu-22.04 runners and conflicts
|
||||
# with the legacy fuse package, so only install the dev headers.
|
||||
sudo apt-get install -y libfuse3-dev
|
||||
# Allow non-root FUSE mounts with allow_other
|
||||
echo 'user_allow_other' | sudo tee -a /etc/fuse.conf
|
||||
sudo chmod 644 /etc/fuse.conf
|
||||
@@ -49,9 +49,6 @@ jobs:
|
||||
fusermount3 --version || fusermount --version || true
|
||||
ls -la /dev/fuse
|
||||
|
||||
- name: Repair the fusermount3 setuid bit
|
||||
uses: ./.github/actions/fix-fusermount-setuid
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
cd weed
|
||||
|
||||
@@ -11,7 +11,6 @@ on:
|
||||
- 'weed/pb/filer.proto'
|
||||
- 'test/fuse_p2p/**'
|
||||
- '.github/workflows/fuse-p2p-integration.yml'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
push:
|
||||
branches: [master]
|
||||
paths:
|
||||
@@ -22,7 +21,6 @@ on:
|
||||
- 'weed/pb/mount_peer.proto'
|
||||
- 'weed/pb/filer.proto'
|
||||
- 'test/fuse_p2p/**'
|
||||
- '.github/actions/fix-fusermount-setuid/**'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/fuse-p2p-integration
|
||||
@@ -39,24 +37,20 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Configure FUSE
|
||||
- name: Install FUSE dependencies
|
||||
run: |
|
||||
# Nothing to install: fuse3 ships fusermount3 and is pre-installed,
|
||||
# and go-fuse is pure Go, so the libfuse headers were never linked
|
||||
# against.
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y libfuse3-dev
|
||||
echo 'user_allow_other' | sudo tee -a /etc/fuse.conf
|
||||
sudo chmod 644 /etc/fuse.conf
|
||||
|
||||
- name: Repair the fusermount3 setuid bit
|
||||
uses: ./.github/actions/fix-fusermount-setuid
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: go build -o weed/weed -buildvcs=false ./weed
|
||||
|
||||
|
||||
@@ -3,18 +3,8 @@ name: "go: build binary"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- '**/*.go'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/go.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- '**/*.go'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/go.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/go
|
||||
@@ -30,9 +20,9 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
- name: Get dependencies
|
||||
@@ -47,104 +37,28 @@ jobs:
|
||||
# Fail only if there are actual vet errors (not counting the filtered lock warnings)
|
||||
if grep -q "vet:" vet-output.txt; then exit 1; fi
|
||||
|
||||
vet-32bit:
|
||||
name: Go Vet 32-bit
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
- name: Go Vet linux/386 (type-checks code and tests for 32-bit int overflows)
|
||||
run: |
|
||||
GOOS=linux GOARCH=386 go vet ./... 2>&1 | grep -v "MessageState contains sync.Mutex" | grep -v "IdentityAccessManagement contains sync.RWMutex" | tee vet-32bit-output.txt
|
||||
if grep -q "vet:" vet-32bit-output.txt; then exit 1; fi
|
||||
|
||||
build:
|
||||
name: Build
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
- name: Build
|
||||
run: cd weed; go build -tags "elastic gocdk sqlite ydb tarantool tikv rclone" -v .
|
||||
|
||||
build-cross:
|
||||
name: Build cross-platform (${{ matrix.goos }}/${{ matrix.goarch }})
|
||||
runs-on: ubuntu-latest
|
||||
strategy:
|
||||
# One target's breakage should not hide the other three.
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- { goos: windows, goarch: amd64 }
|
||||
- { goos: windows, goarch: arm64 }
|
||||
- { goos: freebsd, goarch: amd64 }
|
||||
- { goos: darwin, goarch: arm64 }
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
# Nothing else on a PR compiles these, so per-OS syscall constants creep
|
||||
# back into shared files unnoticed and only a release build catches it.
|
||||
- name: Cross-compile
|
||||
env:
|
||||
GOOS: ${{ matrix.goos }}
|
||||
GOARCH: ${{ matrix.goarch }}
|
||||
run: |
|
||||
go build ./weed/...
|
||||
# Tests too: they reach for per-OS syscall constants the build does
|
||||
# not, and only compiling them catches an untagged one.
|
||||
go vet ./weed/mount/... ./weed/command/... 2>&1 |
|
||||
grep -v "MessageState contains sync.Mutex" | tee /tmp/vet.txt
|
||||
if grep -q "vet:" /tmp/vet.txt; then exit 1; fi
|
||||
|
||||
test:
|
||||
name: Test
|
||||
runs-on: ubuntu-latest
|
||||
services:
|
||||
redis:
|
||||
image: redis:8
|
||||
ports:
|
||||
- 6379:6379
|
||||
options: >-
|
||||
--health-cmd "redis-cli ping"
|
||||
--health-interval 10s
|
||||
--health-timeout 5s
|
||||
--health-retries 5
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
- name: Test
|
||||
env:
|
||||
RUN_REDIS_TESTS: "1"
|
||||
run: cd weed; go test -tags "elastic gocdk sqlite ydb tarantool tikv rclone" -v ./...
|
||||
|
||||
test-32bit:
|
||||
name: Test 32-bit
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
# 386 test binaries run natively on the amd64 runner. This catches what vet
|
||||
# can't: unaligned 64-bit atomics and arithmetic that wraps at runtime.
|
||||
# -short skips the e2e suites already covered on amd64.
|
||||
- name: Test linux/386
|
||||
run: cd weed; GOOS=linux GOARCH=386 go test -short ./...
|
||||
|
||||
+23
-1662
File diff suppressed because it is too large
Load Diff
@@ -15,7 +15,7 @@ jobs:
|
||||
helm-release:
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
with:
|
||||
fetch-depth: 0
|
||||
|
||||
|
||||
@@ -25,16 +25,16 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Java
|
||||
uses: actions/setup-java@v6
|
||||
uses: actions/setup-java@v5
|
||||
with:
|
||||
java-version: ${{ matrix.java }}
|
||||
distribution: 'temurin'
|
||||
|
||||
@@ -1,183 +0,0 @@
|
||||
name: "release: java clients"
|
||||
|
||||
# Publishes the SeaweedFS Java clients (seaweedfs-client and
|
||||
# seaweedfs-hadoop3-client) to Maven Central via the Sonatype Central Portal.
|
||||
#
|
||||
# Required repository secrets:
|
||||
# MAVEN_CENTRAL_USERNAME - Central Portal user token username (central.sonatype.com -> Account -> Generate User Token)
|
||||
# MAVEN_CENTRAL_PASSWORD - Central Portal user token password
|
||||
# MAVEN_GPG_PRIVATE_KEY - ASCII-armored signing key:
|
||||
# gpg --homedir <keyring> --armor --export-secret-keys <KEYID> > key.asc
|
||||
# MAVEN_GPG_PASSPHRASE - passphrase for that key
|
||||
#
|
||||
# A plain run publishes to Central. Check dry_run to exercise secrets, GPG
|
||||
# signing, and the build without committing or publishing.
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
version:
|
||||
description: "Version to publish, e.g. 4.39. Leave blank to use the current SeaweedFS version."
|
||||
type: string
|
||||
required: false
|
||||
dry_run:
|
||||
description: "Build and GPG-sign only; skip the version commit and the Central upload"
|
||||
type: boolean
|
||||
default: false
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
|
||||
concurrency:
|
||||
group: java-release
|
||||
cancel-in-progress: false
|
||||
|
||||
env:
|
||||
# Java 17 needs these opens for the Maven publishing plugins' reflective access.
|
||||
MAVEN_OPTS: >-
|
||||
--add-opens=java.base/java.util=ALL-UNNAMED
|
||||
--add-opens=java.base/java.lang.reflect=ALL-UNNAMED
|
||||
--add-opens=java.base/java.text=ALL-UNNAMED
|
||||
--add-opens=java.desktop/java.awt.font=ALL-UNNAMED
|
||||
|
||||
jobs:
|
||||
publish:
|
||||
name: Publish to Maven Central
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
# Full history so the version-bump commit can rebase onto a moved master.
|
||||
fetch-depth: 0
|
||||
|
||||
# An explicit input wins; otherwise fall back to the current SeaweedFS
|
||||
# version (MAJOR.MINOR) from constants.go, matching its %d.%02d formatting.
|
||||
- name: Resolve version
|
||||
id: resolve
|
||||
env:
|
||||
INPUT_VERSION: ${{ inputs.version }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
VERSION="$INPUT_VERSION"
|
||||
if [ -z "$VERSION" ]; then
|
||||
CONST=weed/util/version/constants.go
|
||||
MAJOR=$(grep -oP 'MAJOR_VERSION\s*=\s*int32\(\K[0-9]+' "$CONST")
|
||||
MINOR=$(grep -oP 'MINOR_VERSION\s*=\s*int32\(\K[0-9]+' "$CONST")
|
||||
VERSION=$(printf '%d.%02d' "$MAJOR" "$MINOR")
|
||||
echo "No version given; using current SeaweedFS version ${VERSION}."
|
||||
fi
|
||||
if ! [[ "$VERSION" =~ ^[0-9]+\.[0-9]+$ ]]; then
|
||||
echo "::error::version must be MAJOR.MINOR, e.g. 4.39 (got '$VERSION')"
|
||||
exit 1
|
||||
fi
|
||||
echo "version=${VERSION}" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Set up JDK 17
|
||||
uses: actions/setup-java@v6
|
||||
with:
|
||||
java-version: '17'
|
||||
distribution: 'temurin'
|
||||
cache: 'maven'
|
||||
server-id: central
|
||||
server-username: MAVEN_CENTRAL_USERNAME
|
||||
server-password: MAVEN_CENTRAL_PASSWORD
|
||||
gpg-private-key: ${{ secrets.MAVEN_GPG_PRIVATE_KEY }}
|
||||
gpg-passphrase: MAVEN_GPG_PASSPHRASE
|
||||
|
||||
# client carries the version literally; hdfs3 derives its own version and
|
||||
# its seaweedfs-client dependency from the seaweedfs.client.version property.
|
||||
- name: Set versions in poms
|
||||
env:
|
||||
VERSION: ${{ steps.resolve.outputs.version }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
V=org.codehaus.mojo:versions-maven-plugin:2.16.2
|
||||
mvn -B -ntp -f other/java/client/pom.xml "${V}:set" \
|
||||
-DnewVersion="$VERSION" -DgenerateBackupPoms=false
|
||||
mvn -B -ntp -f other/java/hdfs3/pom.xml "${V}:set-property" \
|
||||
-Dproperty=seaweedfs.client.version -DnewVersion="$VERSION" -DgenerateBackupPoms=false
|
||||
|
||||
- name: Commit version bump
|
||||
if: ${{ !inputs.dry_run }}
|
||||
env:
|
||||
VERSION: ${{ steps.resolve.outputs.version }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
if git diff --quiet; then
|
||||
echo "Poms already at ${VERSION}; nothing to commit."
|
||||
exit 0
|
||||
fi
|
||||
git config user.name "github-actions[bot]"
|
||||
git config user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
git add other/java/client/pom.xml other/java/hdfs3/pom.xml
|
||||
git commit -m "java ${VERSION}"
|
||||
# Rebase and retry so a concurrent push to master doesn't lose the bump.
|
||||
for attempt in 1 2 3 4 5; do
|
||||
if git push origin HEAD:master; then
|
||||
exit 0
|
||||
fi
|
||||
echo "push rejected (attempt ${attempt}); rebasing onto latest master"
|
||||
git pull --rebase origin master
|
||||
done
|
||||
echo "::error::could not push version bump after retries"
|
||||
exit 1
|
||||
|
||||
# Tests are skipped here: the integration tests need a live filer, and the
|
||||
# offline unit tests already run on every push in java_unit_tests.yml.
|
||||
# dry_run stops at `install` (build + GPG sign, no upload). A real run deploys.
|
||||
# client goes first either way so its install populates the local repo for hdfs3.
|
||||
- name: Publish seaweedfs-client
|
||||
working-directory: other/java/client
|
||||
env:
|
||||
MAVEN_CENTRAL_USERNAME: ${{ secrets.MAVEN_CENTRAL_USERNAME }}
|
||||
MAVEN_CENTRAL_PASSWORD: ${{ secrets.MAVEN_CENTRAL_PASSWORD }}
|
||||
MAVEN_GPG_PASSPHRASE: ${{ secrets.MAVEN_GPG_PASSPHRASE }}
|
||||
DRY_RUN: ${{ inputs.dry_run }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
[ "$DRY_RUN" = "true" ] && GOAL="clean install" || GOAL="clean deploy"
|
||||
mvn -B -ntp $GOAL -DskipTests
|
||||
|
||||
- name: Publish seaweedfs-hadoop3-client
|
||||
working-directory: other/java/hdfs3
|
||||
env:
|
||||
MAVEN_CENTRAL_USERNAME: ${{ secrets.MAVEN_CENTRAL_USERNAME }}
|
||||
MAVEN_CENTRAL_PASSWORD: ${{ secrets.MAVEN_CENTRAL_PASSWORD }}
|
||||
MAVEN_GPG_PASSPHRASE: ${{ secrets.MAVEN_GPG_PASSPHRASE }}
|
||||
DRY_RUN: ${{ inputs.dry_run }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
[ "$DRY_RUN" = "true" ] && GOAL="clean install" || GOAL="clean deploy"
|
||||
mvn -B -ntp $GOAL -DskipTests
|
||||
|
||||
# Bump every version the wiki quotes for the Java clients. Runs only after
|
||||
# a successful real publish. Uses GITHUB_TOKEN; set a WIKI_TOKEN secret if
|
||||
# the token can't push to the wiki.
|
||||
- name: Update wiki client versions
|
||||
if: ${{ !inputs.dry_run }}
|
||||
env:
|
||||
VERSION: ${{ steps.resolve.outputs.version }}
|
||||
GH_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
WIKI_TOKEN: ${{ secrets.WIKI_TOKEN }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
TOKEN="${WIKI_TOKEN:-$GH_TOKEN}"
|
||||
git clone -q "https://x-access-token:${TOKEN}@github.com/${{ github.repository }}.wiki.git" wiki
|
||||
cd wiki
|
||||
for f in $(grep -rlE "seaweedfs-(client|hadoop3-client)" --include="*.md" .); do
|
||||
NEWV="$VERSION" perl -0777 -i -pe '
|
||||
my $v = $ENV{NEWV};
|
||||
s{(<artifactId>seaweedfs-(?:client|hadoop3-client)</artifactId>\s*<version>)[0-9]+\.[0-9]+(</version>)}{$1$v$2}g;
|
||||
s{(seaweedfs-(?:client|hadoop3-client):)[0-9]+\.[0-9]+}{$1$v}g;
|
||||
s{(seaweedfs-(?:client|hadoop3-client)-)[0-9]+\.[0-9]+(\.jar)}{$1$v$2}g;
|
||||
s{(seaweedfs-(?:client|hadoop3-client)/)[0-9]+\.[0-9]+(/)}{$1$v$2}g;
|
||||
' "$f"
|
||||
done
|
||||
if git diff --quiet; then
|
||||
echo "Wiki already references ${VERSION}."
|
||||
exit 0
|
||||
fi
|
||||
git config user.name "github-actions[bot]"
|
||||
git config user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
git commit -am "java clients ${VERSION}"
|
||||
git push
|
||||
@@ -23,10 +23,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Java
|
||||
uses: actions/setup-java@v6
|
||||
uses: actions/setup-java@v5
|
||||
with:
|
||||
java-version: ${{ matrix.java }}
|
||||
distribution: 'temurin'
|
||||
|
||||
@@ -3,24 +3,8 @@ name: "Kafka Quick Test (Load Test with Schema Registry)"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/mq/**'
|
||||
- 'weed/pb/mq_pb/**'
|
||||
- 'weed/pb/schema_pb/**'
|
||||
- 'test/kafka/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/kafka-quicktest.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/mq/**'
|
||||
- 'weed/pb/mq_pb/**'
|
||||
- 'weed/pb/schema_pb/**'
|
||||
- 'test/kafka/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/kafka-quicktest.yml'
|
||||
workflow_dispatch: # Allow manual trigger
|
||||
|
||||
concurrency:
|
||||
@@ -37,22 +21,17 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
cache-dependency-path: |
|
||||
**/go.sum
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
|
||||
@@ -3,24 +3,8 @@ name: "Kafka Gateway Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/mq/**'
|
||||
- 'weed/pb/mq_pb/**'
|
||||
- 'weed/pb/schema_pb/**'
|
||||
- 'test/kafka/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/kafka-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/mq/**'
|
||||
- 'weed/pb/mq_pb/**'
|
||||
- 'weed/pb/schema_pb/**'
|
||||
- 'test/kafka/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/kafka-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/kafka-tests
|
||||
@@ -43,7 +27,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [unit-tests-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 1.0 --memory 1g --hostname kafka-unit-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 1
|
||||
@@ -51,13 +35,13 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Setup Container Environment
|
||||
run: |
|
||||
@@ -87,7 +71,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [integration-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 2.0 --memory 2g --ulimit nofile=1024:1024 --hostname kafka-integration-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 2
|
||||
@@ -96,13 +80,13 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Setup Integration Container Environment
|
||||
run: |
|
||||
@@ -134,7 +118,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [e2e-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 2.0 --memory 2g --hostname kafka-e2e-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 2
|
||||
@@ -143,12 +127,12 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
cache-dependency-path: |
|
||||
**/go.sum
|
||||
@@ -313,7 +297,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [consumer-group-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 1.0 --memory 2g --ulimit nofile=512:512 --hostname kafka-consumer-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 1
|
||||
@@ -322,12 +306,12 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
cache-dependency-path: |
|
||||
**/go.sum
|
||||
@@ -475,7 +459,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [client-compat-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 1.0 --memory 1.5g --shm-size 256m --hostname kafka-client-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 1
|
||||
@@ -484,12 +468,12 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
cache-dependency-path: |
|
||||
**/go.sum
|
||||
@@ -633,7 +617,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [smq-integration-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 1.0 --memory 2g --hostname kafka-smq-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 1
|
||||
@@ -642,12 +626,12 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
cache-dependency-path: |
|
||||
**/go.sum
|
||||
@@ -794,7 +778,7 @@ jobs:
|
||||
matrix:
|
||||
container-id: [protocol-1]
|
||||
container:
|
||||
image: golang:1.26-alpine
|
||||
image: golang:1.24-alpine
|
||||
options: --cpus 1.0 --memory 1g --tmpfs /tmp:exec --hostname kafka-protocol-${{ matrix.container-id }}
|
||||
env:
|
||||
GOMAXPROCS: 1
|
||||
@@ -803,13 +787,13 @@ jobs:
|
||||
CONTAINER_ID: ${{ matrix.container-id }}
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Setup Protocol Container Environment
|
||||
run: |
|
||||
|
||||
@@ -37,10 +37,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -82,10 +82,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -1,79 +0,0 @@
|
||||
name: "Master Cold Start Tests"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/server/master_*.go'
|
||||
- 'weed/topology/**'
|
||||
- 'weed/operation/**'
|
||||
- 'test/master_cold_start/**'
|
||||
- 'test/testutil/**'
|
||||
- '.github/workflows/master-cold-start-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/server/master_*.go'
|
||||
- 'weed/topology/**'
|
||||
- 'weed/operation/**'
|
||||
- 'test/master_cold_start/**'
|
||||
- 'test/testutil/**'
|
||||
- '.github/workflows/master-cold-start-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/master-cold-start-tests
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
master-cold-start-tests:
|
||||
name: Master Cold Start Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Build weed binary
|
||||
run: |
|
||||
cd weed && go install -buildvcs=false
|
||||
|
||||
- name: Run master cold start tests
|
||||
# test/master_cold_start boots a fresh master plus empty volume
|
||||
# servers and requires the very first assign (HTTP and gRPC, no
|
||||
# client retries) to complete a write: the assign that triggers
|
||||
# volume growth must wait for it instead of failing with
|
||||
# "volume growth in progress".
|
||||
run: |
|
||||
export WEED_BINARY=$(go env GOPATH)/bin/weed
|
||||
go test -v -timeout=8m ./test/master_cold_start/...
|
||||
|
||||
- name: Collect server logs on failure
|
||||
if: failure()
|
||||
run: |
|
||||
# test/master_cold_start/cluster.go keeps failing-test dirs created
|
||||
# via os.MkdirTemp("", "seaweedfs_master_cold_start_it_") with each
|
||||
# process log under <baseDir>/logs/.
|
||||
mkdir -p /tmp/master-cold-start-logs
|
||||
find /tmp -maxdepth 1 -type d -name "seaweedfs_master_cold_start_it_*" 2>/dev/null | while read dir; do
|
||||
echo "Found test directory: $dir"
|
||||
cp -r "$dir" /tmp/master-cold-start-logs/ 2>/dev/null || true
|
||||
done
|
||||
find /tmp/master-cold-start-logs -type f -name "*.log" -print -exec tail -n 100 {} \; 2>/dev/null || echo "No logs found"
|
||||
|
||||
- name: Archive logs
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: master-cold-start-test-logs
|
||||
path: /tmp/master-cold-start-logs/
|
||||
retention-days: 7
|
||||
@@ -8,7 +8,6 @@ on:
|
||||
- 'weed/pb/filer_pb/**'
|
||||
- 'weed/util/log_buffer/**'
|
||||
- 'weed/server/filer_grpc_server_sub_meta.go'
|
||||
- 'weed/server/master_grpc_server.go'
|
||||
- 'weed/command/filer_backup.go'
|
||||
- 'test/metadata_subscribe/**'
|
||||
- '.github/workflows/metadata-subscribe-tests.yml'
|
||||
@@ -19,7 +18,6 @@ on:
|
||||
- 'weed/pb/filer_pb/**'
|
||||
- 'weed/util/log_buffer/**'
|
||||
- 'weed/server/filer_grpc_server_sub_meta.go'
|
||||
- 'weed/server/master_grpc_server.go'
|
||||
- 'weed/command/filer_backup.go'
|
||||
- 'test/metadata_subscribe/**'
|
||||
- '.github/workflows/metadata-subscribe-tests.yml'
|
||||
@@ -42,10 +40,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -1,203 +0,0 @@
|
||||
name: "mount: benchmark"
|
||||
|
||||
# Manual benchmark: native WinFsp mount vs rclone+WebDAV on the same Windows
|
||||
# runner, with a Linux FUSE mount of the same build as a reference. Numbers
|
||||
# from shared runners are noisy; this is for finding factor-of-N gaps, not
|
||||
# regressions of a few percent.
|
||||
on:
|
||||
workflow_dispatch:
|
||||
push:
|
||||
branches: [ 'winfsp-bench**' ]
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
bench-windows:
|
||||
name: Windows native vs rclone
|
||||
runs-on: windows-latest
|
||||
timeout-minutes: 60
|
||||
env:
|
||||
CGO_ENABLED: 0
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Install WinFsp and rclone
|
||||
run: choco install winfsp rclone -y --no-progress
|
||||
|
||||
- name: Build weed.exe
|
||||
run: go build -o weed.exe ./weed
|
||||
|
||||
- name: Benchmark both mounts
|
||||
shell: pwsh
|
||||
run: |
|
||||
$ErrorActionPreference = 'Stop'
|
||||
|
||||
function Test-Port($port) {
|
||||
$client = New-Object System.Net.Sockets.TcpClient
|
||||
try { $client.Connect('127.0.0.1', $port); return $client.Connected }
|
||||
catch { return $false }
|
||||
finally { $client.Dispose() }
|
||||
}
|
||||
|
||||
function Wait-Drive($drive, $what) {
|
||||
$deadline = (Get-Date).AddMinutes(2)
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
if (Test-Path "${drive}\") { Write-Host "$what is mounted on $drive"; return }
|
||||
Start-Sleep -Seconds 2
|
||||
}
|
||||
throw "$what never appeared on $drive"
|
||||
}
|
||||
|
||||
function Invoke-Bench($dir, $label, $out) {
|
||||
Write-Host "::group::bench $label"
|
||||
& go run ./test/mount_bench -dir $dir -label $label -filer 127.0.0.1:8888 -out $out
|
||||
$code = $LASTEXITCODE
|
||||
Write-Host "::endgroup::"
|
||||
if ($code -ne 0) { throw "bench $label failed with exit $code" }
|
||||
}
|
||||
|
||||
New-Item -ItemType Directory -Force -Path C:\seaweed-data | Out-Null
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mini','-dir=C:\seaweed-data','-ip=127.0.0.1' `
|
||||
-RedirectStandardOutput C:\seaweed-mini.log -RedirectStandardError C:\seaweed-mini.err.log
|
||||
|
||||
$deadline = (Get-Date).AddMinutes(3)
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
if ((Test-Port 8888) -and (Test-Port 18888) -and (Test-Port 7333)) { break }
|
||||
Start-Sleep -Seconds 3
|
||||
}
|
||||
if (-not ((Test-Port 8888) -and (Test-Port 18888) -and (Test-Port 7333))) {
|
||||
Get-Content C:\seaweed-mini.log, C:\seaweed-mini.err.log -ErrorAction SilentlyContinue
|
||||
throw "mini cluster never came up"
|
||||
}
|
||||
Write-Host "filer on 8888/18888, webdav on 7333"
|
||||
|
||||
# --- native WinFsp mount ---
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mount','-filer=127.0.0.1:8888','-dir=S:' `
|
||||
-RedirectStandardOutput C:\seaweed-mount.log -RedirectStandardError C:\seaweed-mount.err.log
|
||||
Wait-Drive 'S:' 'weed mount'
|
||||
|
||||
Invoke-Bench 'S:\bench-native' 'winfsp-native' 'C:\results-native.json'
|
||||
|
||||
Get-CimInstance Win32_Process -Filter "Name = 'weed.exe'" |
|
||||
Where-Object { $_.CommandLine -like '*mount*' } |
|
||||
ForEach-Object { Stop-Process -Id $_.ProcessId -Force }
|
||||
$deadline = (Get-Date).AddMinutes(1)
|
||||
while ((Get-Date) -lt $deadline -and (Test-Path S:\)) { Start-Sleep -Seconds 2 }
|
||||
|
||||
# --- rclone + WebDAV on the same WinFsp ---
|
||||
# rclone serves listings from a directory cache it fills lazily, so the
|
||||
# big-listing files have to exist before it mounts or it never sees them.
|
||||
& go run ./test/mount_bench -filer 127.0.0.1:8888 -seed bench-rclone/biglist
|
||||
if ($LASTEXITCODE -ne 0) { throw "seeding failed" }
|
||||
|
||||
$env:RCLONE_CONFIG_SEAWEED_TYPE = 'webdav'
|
||||
$env:RCLONE_CONFIG_SEAWEED_URL = 'http://127.0.0.1:7333'
|
||||
$env:RCLONE_CONFIG_SEAWEED_VENDOR = 'other'
|
||||
Start-Process -FilePath rclone `
|
||||
-ArgumentList 'mount','seaweed:','T:','--vfs-cache-mode=writes','-v','--log-file=C:\rclone.log'
|
||||
Wait-Drive 'T:' 'rclone mount'
|
||||
|
||||
Invoke-Bench 'T:\bench-rclone' 'rclone-webdav' 'C:\results-rclone.json'
|
||||
|
||||
Stop-Process -Name rclone -Force -ErrorAction SilentlyContinue
|
||||
|
||||
# --- comparison ---
|
||||
$table = & go run ./test/mount_bench -compare C:\results-native.json,C:\results-rclone.json
|
||||
$table | Write-Host
|
||||
"## Windows: native WinFsp vs rclone+WebDAV" | Out-File -Append $env:GITHUB_STEP_SUMMARY
|
||||
$table | Out-File -Append $env:GITHUB_STEP_SUMMARY
|
||||
|
||||
- name: Logs
|
||||
if: always()
|
||||
shell: pwsh
|
||||
run: |
|
||||
foreach ($f in 'C:\seaweed-mount.log','C:\seaweed-mount.err.log','C:\rclone.log','C:\seaweed-mini.log','C:\seaweed-mini.err.log') {
|
||||
if (Test-Path $f) { Write-Host "===== $f"; Get-Content $f -Tail 100 }
|
||||
}
|
||||
|
||||
- name: Results
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: results-windows
|
||||
path: C:\results-*.json
|
||||
if-no-files-found: ignore
|
||||
|
||||
bench-linux:
|
||||
name: Linux FUSE reference
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 60
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Repair the fusermount3 setuid bit
|
||||
uses: ./.github/actions/fix-fusermount-setuid
|
||||
|
||||
- name: Allow non-root FUSE mounts with allow_other
|
||||
run: |
|
||||
echo 'user_allow_other' | sudo tee -a /etc/fuse.conf
|
||||
sudo chmod 644 /etc/fuse.conf
|
||||
|
||||
- name: Build weed
|
||||
run: go build -o /tmp/weed ./weed
|
||||
|
||||
- name: Benchmark FUSE mount
|
||||
run: |
|
||||
set -e
|
||||
mkdir -p /tmp/seaweed-data
|
||||
/tmp/weed -logtostderr mini -dir=/tmp/seaweed-data -ip=127.0.0.1 > /tmp/mini.log 2>&1 &
|
||||
|
||||
for i in $(seq 1 60); do
|
||||
if nc -z 127.0.0.1 8888 && nc -z 127.0.0.1 18888; then break; fi
|
||||
sleep 3
|
||||
done
|
||||
nc -z 127.0.0.1 8888 || { cat /tmp/mini.log; echo "filer never came up"; exit 1; }
|
||||
|
||||
mkdir -p "$HOME/mnt"
|
||||
/tmp/weed -logtostderr mount -filer=127.0.0.1:8888 -dir="$HOME/mnt" > /tmp/mount.log 2>&1 &
|
||||
for i in $(seq 1 60); do
|
||||
if mountpoint -q "$HOME/mnt"; then break; fi
|
||||
sleep 2
|
||||
done
|
||||
mountpoint -q "$HOME/mnt" || { cat /tmp/mount.log; echo "mount never appeared"; exit 1; }
|
||||
|
||||
go run ./test/mount_bench -dir "$HOME/mnt/bench-linux" -label linux-fuse -filer 127.0.0.1:8888 -out /tmp/results-linux.json
|
||||
|
||||
{
|
||||
echo "## Linux FUSE reference"
|
||||
go run ./test/mount_bench -compare /tmp/results-linux.json
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: Logs
|
||||
if: always()
|
||||
run: |
|
||||
tail -n 100 /tmp/mount.log /tmp/mini.log 2>/dev/null || true
|
||||
|
||||
- name: Results
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: results-linux
|
||||
path: /tmp/results-linux.json
|
||||
if-no-files-found: ignore
|
||||
@@ -1,124 +0,0 @@
|
||||
name: "mount: windows conformance"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/command/mount*.go'
|
||||
- 'weed/storage/volume_vacuum*.go'
|
||||
- 'weed/storage/volume_loading.go'
|
||||
- 'weed/storage/disk_location.go'
|
||||
- 'test/winfsp-conformance/**'
|
||||
- '.github/workflows/mount-windows-conformance.yml'
|
||||
# No base branch filter: this is the only thing that runs the Windows mount,
|
||||
# so it should cover a pull request stacked on another one too.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/command/mount*.go'
|
||||
- 'weed/storage/volume_vacuum*.go'
|
||||
- 'weed/storage/volume_loading.go'
|
||||
- 'weed/storage/disk_location.go'
|
||||
- 'test/winfsp-conformance/**'
|
||||
- '.github/workflows/mount-windows-conformance.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
conformance:
|
||||
name: WinFsp conformance
|
||||
runs-on: windows-latest
|
||||
timeout-minutes: 60
|
||||
env:
|
||||
# The runner ships MinGW, so cgo is on by default and cgofuse picks its
|
||||
# cgo variant, which wants WinFsp's headers. The nocgo variant loads
|
||||
# winfsp-x64.dll at run time instead, which is how weed.exe is released.
|
||||
CGO_ENABLED: 0
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
# cgofuse loads winfsp-x64.dll at run time, so WinFsp is needed here but
|
||||
# not to build.
|
||||
- name: Install WinFsp
|
||||
run: choco install winfsp -y --no-progress
|
||||
|
||||
- name: Build weed.exe
|
||||
run: go build -o weed.exe ./weed
|
||||
|
||||
# The runner tears down a step's process tree when its shell exits, so a
|
||||
# cluster started in one step is gone by the next. Everything that needs
|
||||
# the cluster and the mount alive has to share a step.
|
||||
- name: Mount and run winfsp-tests
|
||||
shell: pwsh
|
||||
run: |
|
||||
$ErrorActionPreference = 'Stop'
|
||||
|
||||
function Test-Port($port) {
|
||||
# A plain connect, because Test-NetConnection has reported success
|
||||
# here for a port nothing was listening on.
|
||||
$client = New-Object System.Net.Sockets.TcpClient
|
||||
try { $client.Connect('127.0.0.1', $port); return $client.Connected }
|
||||
catch { return $false }
|
||||
finally { $client.Dispose() }
|
||||
}
|
||||
|
||||
function Start-Mount($log) {
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mount','-filer=127.0.0.1:8888','-dir=S:' `
|
||||
-RedirectStandardOutput "C:\$log.log" -RedirectStandardError "C:\$log.err.log"
|
||||
$deadline = (Get-Date).AddMinutes(2)
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
if (Test-Path S:\) { Write-Host "S: is mounted"; return }
|
||||
Start-Sleep -Seconds 2
|
||||
}
|
||||
Get-Content "C:\$log.log", "C:\$log.err.log" -ErrorAction SilentlyContinue
|
||||
throw "S: never appeared"
|
||||
}
|
||||
|
||||
New-Item -ItemType Directory -Force -Path C:\seaweed-data | Out-Null
|
||||
# -ip pins the cluster to loopback; it otherwise advertises and binds
|
||||
# the runner's LAN address, which 127.0.0.1 cannot reach.
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mini','-dir=C:\seaweed-data','-ip=127.0.0.1' `
|
||||
-RedirectStandardOutput C:\seaweed-mini.log -RedirectStandardError C:\seaweed-mini.err.log
|
||||
|
||||
$deadline = (Get-Date).AddMinutes(3)
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
# The mount dials grpc, not http, so both ports have to answer.
|
||||
if ((Test-Port 8888) -and (Test-Port 18888)) { break }
|
||||
Start-Sleep -Seconds 3
|
||||
}
|
||||
if (-not ((Test-Port 8888) -and (Test-Port 18888))) {
|
||||
Get-Content C:\seaweed-mini.log, C:\seaweed-mini.err.log -ErrorAction SilentlyContinue
|
||||
throw "filer never came up"
|
||||
}
|
||||
Write-Host "filer is up on http 8888 and grpc 18888"
|
||||
|
||||
Start-Mount 'seaweed-mount'
|
||||
|
||||
Write-Host "::group::winfsp-tests"
|
||||
& pwsh -File test/winfsp-conformance/run.ps1 -MountPoint S:\
|
||||
$code = $LASTEXITCODE
|
||||
Write-Host "::endgroup::"
|
||||
if ($code -ne 0) { throw "winfsp-tests failed with exit $code" }
|
||||
|
||||
- name: Logs
|
||||
if: always()
|
||||
shell: pwsh
|
||||
run: |
|
||||
foreach ($f in 'C:\seaweed-mount.log','C:\seaweed-mount.err.log','C:\seaweed-mini.log','C:\seaweed-mini.err.log') {
|
||||
if (Test-Path $f) { Write-Host "===== $f"; Get-Content $f -Tail 200 }
|
||||
}
|
||||
@@ -1,205 +0,0 @@
|
||||
name: "mount: windows"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/command/mount*.go'
|
||||
- 'weed/storage/volume_vacuum*.go'
|
||||
- 'weed/storage/volume_loading.go'
|
||||
- 'weed/storage/disk_location.go'
|
||||
- 'test/winfsp/**'
|
||||
- '.github/workflows/mount-windows.yml'
|
||||
# No base branch filter: this is the only thing that runs the Windows mount,
|
||||
# so it should cover a pull request stacked on another one too.
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/command/mount*.go'
|
||||
- 'weed/storage/volume_vacuum*.go'
|
||||
- 'weed/storage/volume_loading.go'
|
||||
- 'weed/storage/disk_location.go'
|
||||
- 'test/winfsp/**'
|
||||
- '.github/workflows/mount-windows.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.head_ref || github.run_id }}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
mount-windows:
|
||||
name: Mount on Windows
|
||||
runs-on: windows-latest
|
||||
timeout-minutes: 40
|
||||
env:
|
||||
# The runner ships MinGW, so cgo is on by default and cgofuse picks its
|
||||
# cgo variant, which wants WinFsp's headers. The nocgo variant loads
|
||||
# winfsp-x64.dll at run time instead, which is how weed.exe is released.
|
||||
CGO_ENABLED: 0
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
# cgofuse loads winfsp-x64.dll at run time, so WinFsp is needed here but
|
||||
# not to build.
|
||||
- name: Install WinFsp
|
||||
run: choco install winfsp -y --no-progress
|
||||
|
||||
- name: Build weed.exe
|
||||
run: go build -o weed.exe ./weed
|
||||
|
||||
# The runner tears down a step's process tree when its shell exits, so a
|
||||
# cluster started in one step is gone by the next. Everything that needs
|
||||
# the cluster and the mount alive has to share a step.
|
||||
- name: Mount and exercise
|
||||
shell: pwsh
|
||||
run: |
|
||||
$ErrorActionPreference = 'Stop'
|
||||
|
||||
function Test-Port($port) {
|
||||
# A plain connect, because Test-NetConnection has reported success
|
||||
# here for a port nothing was listening on.
|
||||
$client = New-Object System.Net.Sockets.TcpClient
|
||||
try { $client.Connect('127.0.0.1', $port); return $client.Connected }
|
||||
catch { return $false }
|
||||
finally { $client.Dispose() }
|
||||
}
|
||||
|
||||
function Start-Mount($log) {
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mount','-filer=127.0.0.1:8888','-dir=S:' `
|
||||
-RedirectStandardOutput "C:\$log.log" -RedirectStandardError "C:\$log.err.log"
|
||||
$deadline = (Get-Date).AddMinutes(2)
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
if (Test-Path S:\) { Write-Host "S: is mounted"; return }
|
||||
Start-Sleep -Seconds 2
|
||||
}
|
||||
Get-Content "C:\$log.log", "C:\$log.err.log" -ErrorAction SilentlyContinue
|
||||
throw "S: never appeared"
|
||||
}
|
||||
|
||||
function Stop-Mount {
|
||||
Get-CimInstance Win32_Process -Filter "Name = 'weed.exe'" |
|
||||
Where-Object { $_.CommandLine -like '*mount*' } |
|
||||
ForEach-Object { Stop-Process -Id $_.ProcessId -Force }
|
||||
$deadline = (Get-Date).AddMinutes(1)
|
||||
while ((Get-Date) -lt $deadline -and (Test-Path S:\)) { Start-Sleep -Seconds 2 }
|
||||
if (Test-Path S:\) { throw "S: still present after stopping the mount" }
|
||||
Write-Host "unmounted"
|
||||
}
|
||||
|
||||
function Invoke-Tests($label, [string[]]$goArgs) {
|
||||
Write-Host "::group::$label"
|
||||
& go @goArgs
|
||||
$code = $LASTEXITCODE
|
||||
Write-Host "::endgroup::"
|
||||
if ($code -ne 0) { throw "$label failed with exit $code" }
|
||||
}
|
||||
|
||||
New-Item -ItemType Directory -Force -Path C:\seaweed-data | Out-Null
|
||||
# -ip pins the cluster to loopback; it otherwise advertises and binds
|
||||
# the runner's LAN address, which 127.0.0.1 cannot reach.
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mini','-dir=C:\seaweed-data','-ip=127.0.0.1' `
|
||||
-RedirectStandardOutput C:\seaweed-mini.log -RedirectStandardError C:\seaweed-mini.err.log
|
||||
|
||||
$deadline = (Get-Date).AddMinutes(3)
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
# The mount dials grpc, not http, so both ports have to answer.
|
||||
if ((Test-Port 8888) -and (Test-Port 18888)) { break }
|
||||
Start-Sleep -Seconds 3
|
||||
}
|
||||
if (-not ((Test-Port 8888) -and (Test-Port 18888))) {
|
||||
Get-Content C:\seaweed-mini.log, C:\seaweed-mini.err.log -ErrorAction SilentlyContinue
|
||||
throw "filer never came up"
|
||||
}
|
||||
Write-Host "filer is up on http 8888 and grpc 18888"
|
||||
|
||||
Start-Mount 'seaweed-mount'
|
||||
|
||||
Invoke-Tests 'exercise' @('test','-v','-timeout','20m','./test/winfsp','-mountpoint=S:\')
|
||||
Invoke-Tests 'persist-write' @('test','-v','-timeout','15m','./test/winfsp','-run','TestPersistence','-mountpoint=S:\','-phase=write','-filer=127.0.0.1:8888')
|
||||
|
||||
Stop-Mount
|
||||
Start-Mount 'seaweed-remount'
|
||||
|
||||
Invoke-Tests 'persist-verify' @('test','-v','-timeout','15m','./test/winfsp','-run','TestPersistence','-mountpoint=S:\','-phase=verify')
|
||||
|
||||
# WinFsp creates the mount directory itself, so the path must not
|
||||
# exist; only its parent has to.
|
||||
Write-Host "::group::mount over a directory"
|
||||
Stop-Mount
|
||||
Remove-Item C:\seaweed-mnt -Recurse -Force -ErrorAction SilentlyContinue
|
||||
Start-Process -FilePath .\weed.exe `
|
||||
-ArgumentList '-logtostderr','mount','-filer=127.0.0.1:8888','-dir=C:\seaweed-mnt' `
|
||||
-RedirectStandardOutput C:\seaweed-dirmount.log -RedirectStandardError C:\seaweed-dirmount.err.log
|
||||
$deadline = (Get-Date).AddMinutes(2)
|
||||
$ok = $false
|
||||
while ((Get-Date) -lt $deadline) {
|
||||
# Listing succeeds on the plain empty directory too, so wait for the
|
||||
# reparse point WinFsp turns it into. Otherwise this step passes
|
||||
# without a mount and writes to local disk.
|
||||
$item = Get-Item C:\seaweed-mnt -Force -ErrorAction SilentlyContinue
|
||||
if ($null -ne $item -and $item.Attributes.ToString() -like '*ReparsePoint*') { $ok = $true; break }
|
||||
Start-Sleep -Seconds 2
|
||||
}
|
||||
if (-not $ok) {
|
||||
Get-Content C:\seaweed-dirmount.log, C:\seaweed-dirmount.err.log -ErrorAction SilentlyContinue
|
||||
throw "mounting over a directory failed"
|
||||
}
|
||||
Set-Content -Path C:\seaweed-mnt\dirmount.txt -Value 'via directory mount'
|
||||
if ((Get-Content C:\seaweed-mnt\dirmount.txt) -ne 'via directory mount') { throw "readback through the directory mount differs" }
|
||||
Remove-Item C:\seaweed-mnt\dirmount.txt -Force
|
||||
Get-CimInstance Win32_Process -Filter "Name = 'weed.exe'" |
|
||||
Where-Object { $_.CommandLine -like '*mount*' } |
|
||||
ForEach-Object { Stop-Process -Id $_.ProcessId -Force }
|
||||
Start-Sleep -Seconds 5
|
||||
Write-Host "::endgroup::"
|
||||
|
||||
Start-Mount 'seaweed-remount2'
|
||||
|
||||
Write-Host "::group::explorer-style walk"
|
||||
New-Item -ItemType Directory -Force -Path S:\walk | Out-Null
|
||||
1..200 | ForEach-Object { Set-Content -Path "S:\walk\f$_.txt" -Value "line $_" }
|
||||
$names = @(Get-ChildItem S:\walk | ForEach-Object { $_.Name })
|
||||
if ($names.Count -ne 200) {
|
||||
# Name the strays: a dot entry surfacing here is a different problem
|
||||
# from a missing or duplicated file.
|
||||
$unexpected = $names | Where-Object { $_ -notmatch '^f\d+\.txt$' }
|
||||
throw "listed $($names.Count) entries, expected 200; unexpected: $($unexpected -join ', ')"
|
||||
}
|
||||
$body = Get-Content S:\walk\f42.txt
|
||||
if ($body -ne 'line 42') { throw "unexpected content: $body" }
|
||||
Copy-Item S:\walk\f42.txt S:\walk\copy.txt
|
||||
Remove-Item S:\walk -Recurse -Force
|
||||
if (Test-Path S:\walk) { throw "directory survived recursive delete" }
|
||||
Write-Host "::endgroup::"
|
||||
|
||||
# Tear down everything we started so the runner's later steps (Logs,
|
||||
# post-checkout) launch into a clean environment. A WinFsp mount left
|
||||
# active and a weed.exe holding winfsp-x64.dll have been seen to make
|
||||
# the next step's pwsh.exe fail with STATUS_DLL_INIT_FAILED
|
||||
# (0xC0000142), which fails a job whose actual test step passed.
|
||||
try { Stop-Mount } catch { Write-Host "no mount to stop at teardown: $_" }
|
||||
Get-CimInstance Win32_Process -Filter "Name = 'weed.exe'" |
|
||||
ForEach-Object { Stop-Process -Id $_.ProcessId -Force -ErrorAction SilentlyContinue }
|
||||
Start-Sleep -Seconds 3
|
||||
|
||||
- name: Logs
|
||||
if: always()
|
||||
continue-on-error: true
|
||||
shell: pwsh
|
||||
run: |
|
||||
foreach ($f in 'C:\seaweed-mount.log','C:\seaweed-mount.err.log','C:\seaweed-remount.log','C:\seaweed-remount.err.log','C:\seaweed-remount2.log','C:\seaweed-remount2.err.log','C:\seaweed-dirmount.log','C:\seaweed-dirmount.err.log','C:\seaweed-mini.log','C:\seaweed-mini.err.log') {
|
||||
if (Test-Path $f) { Write-Host "===== $f"; Get-Content $f -Tail 200 }
|
||||
}
|
||||
@@ -34,10 +34,10 @@ jobs:
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -0,0 +1,137 @@
|
||||
name: "NFS Integration Tests"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'weed/server/nfs/**'
|
||||
- 'weed/command/nfs.go'
|
||||
- 'weed/filer/filer_inode.go'
|
||||
- 'weed/filer/filer_inode_index.go'
|
||||
- 'weed/filer/filerstore_wrapper.go'
|
||||
- 'weed/server/filer_grpc_server_rename.go'
|
||||
- 'test/nfs/**'
|
||||
- '.github/workflows/nfs-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'weed/server/nfs/**'
|
||||
- 'weed/command/nfs.go'
|
||||
- 'weed/filer/filer_inode.go'
|
||||
- 'weed/filer/filer_inode_index.go'
|
||||
- 'weed/filer/filerstore_wrapper.go'
|
||||
- 'weed/server/filer_grpc_server_rename.go'
|
||||
- 'test/nfs/**'
|
||||
- '.github/workflows/nfs-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/nfs-tests
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
env:
|
||||
TEST_TIMEOUT: '15m'
|
||||
|
||||
jobs:
|
||||
nfs-integration:
|
||||
name: NFS Integration Testing
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 20
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
cd weed
|
||||
go build -o weed .
|
||||
chmod +x weed
|
||||
./weed version
|
||||
|
||||
- name: Run NFS Integration Tests
|
||||
run: |
|
||||
cd test/nfs
|
||||
|
||||
echo "Running NFS integration tests..."
|
||||
echo "============================================"
|
||||
|
||||
# Install test dependencies
|
||||
go mod download
|
||||
|
||||
# Run the protocol-layer tests. The kernel-mount tests require root
|
||||
# for mount(2) and are exercised in their own privileged step below;
|
||||
# skip them here so a "skipped because not root" line doesn't show
|
||||
# up as noise on every CI run.
|
||||
go test -v -timeout=${{ env.TEST_TIMEOUT }} -skip '^TestKernelMount' ./...
|
||||
|
||||
echo "============================================"
|
||||
echo "NFS integration tests completed"
|
||||
|
||||
- name: Install kernel NFS client
|
||||
run: |
|
||||
# nfs-common provides mount.nfs; netbase provides /etc/protocols
|
||||
# which mount.nfs's protocol-name lookups (`tcp`, `udp`) need.
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y nfs-common netbase
|
||||
|
||||
- name: Run kernel-mount E2E tests
|
||||
run: |
|
||||
cd test/nfs
|
||||
|
||||
echo "Running kernel-mount end-to-end tests..."
|
||||
echo "These mount the running 'weed nfs' subprocess via the actual"
|
||||
echo "Linux NFS client to catch protocol regressions invisible to"
|
||||
echo "the go-nfs-client-based tests above."
|
||||
echo "============================================"
|
||||
|
||||
# mount(2) is privileged. Preserve PATH so 'go' (and the weed
|
||||
# binary that test/nfs/framework.go locates via $PATH) resolve
|
||||
# correctly under sudo, and pass through the Go module/cache dirs
|
||||
# so we don't redownload modules under root.
|
||||
sudo env "PATH=$PATH" \
|
||||
GOMODCACHE="$(go env GOMODCACHE)" \
|
||||
GOCACHE="$(go env GOCACHE)" \
|
||||
go test -v -timeout=${{ env.TEST_TIMEOUT }} -run '^TestKernelMount' ./...
|
||||
|
||||
echo "============================================"
|
||||
echo "Kernel-mount E2E tests completed"
|
||||
|
||||
- name: Test Summary
|
||||
if: always()
|
||||
run: |
|
||||
echo "## NFS Integration Test Summary" >> $GITHUB_STEP_SUMMARY
|
||||
echo "" >> $GITHUB_STEP_SUMMARY
|
||||
echo "### Test Coverage" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Read/Write Round Trip**: Basic file create + read" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Directory Operations**: Mkdir, ReadDirPlus, RmDir" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Nested Directories**: Deep tree creation and leaf I/O" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Rename**: Content preserved across rename" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Overwrite + Truncate**: Setattr(size=0) + shorter write" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Large Files**: 3 MiB binary round trip" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Edge Payloads**: All 256 byte values + empty files" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Symlinks**: Symlink + Lookup" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Missing Path**: Remove on missing entry errors cleanly" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **FSINFO**: Non-zero rtpref/wtpref advertised" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **Sequential Append**: Two-part concatenation" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **ReadDir After Remove**: Meta cache does not serve stale entries" >> $GITHUB_STEP_SUMMARY
|
||||
echo "" >> $GITHUB_STEP_SUMMARY
|
||||
echo "### Kernel-Mount E2E Coverage" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **V3 over TCP**: baseline NFSv3 mount + readdir" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **V3 with mountproto=udp**: regression test for UDP MOUNT v3 responder" >> $GITHUB_STEP_SUMMARY
|
||||
echo "- **V4 rejects cleanly**: regression test for the v4 PROG_MISMATCH path (#9262)" >> $GITHUB_STEP_SUMMARY
|
||||
echo "" >> $GITHUB_STEP_SUMMARY
|
||||
echo "### Harness" >> $GITHUB_STEP_SUMMARY
|
||||
echo "Most tests boot their own master + volume + filer + nfs subprocess" >> $GITHUB_STEP_SUMMARY
|
||||
echo "stack on loopback and drive it via the NFSv3 RPC protocol using" >> $GITHUB_STEP_SUMMARY
|
||||
echo "go-nfs-client. The kernel-mount E2E tests reuse the same harness" >> $GITHUB_STEP_SUMMARY
|
||||
echo "but mount the export through the in-tree Linux NFS client to" >> $GITHUB_STEP_SUMMARY
|
||||
echo "catch protocol regressions a Go-only client can't see; they run" >> $GITHUB_STEP_SUMMARY
|
||||
echo "in a separate privileged step (mount(2) requires root)." >> $GITHUB_STEP_SUMMARY
|
||||
@@ -1,470 +0,0 @@
|
||||
name: "Performance"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- '**/*.go'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- 'seaweed-volume/**'
|
||||
- 'seaweed-common/**'
|
||||
- 'test/perf/**'
|
||||
- '.github/workflows/performance.yml'
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
profile_duration:
|
||||
description: "CPU profiling duration in seconds"
|
||||
required: false
|
||||
default: "30"
|
||||
type: string
|
||||
benchmark_files:
|
||||
description: "Number of files for the throughput benchmark"
|
||||
required: false
|
||||
default: "100000"
|
||||
type: string
|
||||
benchmark_concurrency:
|
||||
description: "Concurrent read/write workers"
|
||||
required: false
|
||||
default: "16"
|
||||
type: string
|
||||
benchmark_size:
|
||||
description: "Simulated file size in bytes"
|
||||
required: false
|
||||
default: "1024"
|
||||
type: string
|
||||
s3_objects:
|
||||
description: "Number of objects for the S3 benchmark"
|
||||
required: false
|
||||
default: "20000"
|
||||
type: string
|
||||
s3_size:
|
||||
description: "S3 object size in bytes"
|
||||
required: false
|
||||
default: "4096"
|
||||
type: string
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/performance
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
env:
|
||||
VOL_SIZE_LIMIT: "1024"
|
||||
|
||||
jobs:
|
||||
performance-profile:
|
||||
name: CPU and Heap Profile
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 30
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Build weed
|
||||
run: go build -o weed_bin ./weed
|
||||
|
||||
- name: Start server with profiling enabled
|
||||
run: |
|
||||
mkdir -p ./perfdata
|
||||
./weed_bin -v=1 server -debug -debug.port=6060 -dir=./perfdata \
|
||||
-s3 -filer -volume.max=0 -master.volumeSizeLimitMB=100 \
|
||||
-s3.port=8000 -s3.config=./docker/compose/s3.json \
|
||||
> weed.log 2>&1 &
|
||||
echo "WEED_PID=$!" >> "$GITHUB_ENV"
|
||||
for i in $(seq 1 60); do
|
||||
if curl -sf http://localhost:9333/dir/status >/dev/null 2>&1; then
|
||||
echo "master is ready"
|
||||
break
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
# give the volume server a moment to register with the master
|
||||
sleep 3
|
||||
|
||||
- name: Start memory sampler
|
||||
run: |
|
||||
bash test/perf/mem_sample.sh mem-profile.csv "server=${WEED_PID}" &
|
||||
echo "SAMPLER_PID=$!" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Capture profiles under load
|
||||
run: |
|
||||
DURATION="${{ github.event.inputs.profile_duration || '30' }}"
|
||||
# drive write load so the sampled profile reflects real work
|
||||
./weed_bin benchmark -master=localhost:9333 -writeOnly \
|
||||
-c=16 -n=5000000 -size=1024 > benchmark-load.log 2>&1 &
|
||||
echo "Sampling CPU profile for ${DURATION}s..."
|
||||
curl -s "http://localhost:6060/debug/pprof/profile?seconds=${DURATION}" -o cpu.pprof
|
||||
curl -s "http://localhost:6060/debug/pprof/heap" -o heap.pprof
|
||||
curl -s "http://localhost:6060/debug/pprof/goroutine?debug=1" -o goroutine.txt
|
||||
go tool pprof -top -nodecount=50 cpu.pprof > cpu-top.txt 2>/dev/null || true
|
||||
go tool pprof -top -nodecount=50 -sample_index=inuse_space heap.pprof > heap-top.txt 2>/dev/null || true
|
||||
|
||||
- name: Record memory usage
|
||||
if: always()
|
||||
run: |
|
||||
kill -TERM "${SAMPLER_PID}" 2>/dev/null || true
|
||||
sleep 2
|
||||
{
|
||||
echo "## Memory usage (peak RSS)"
|
||||
echo '```'
|
||||
if [ -f mem-profile.csv.peak ]; then
|
||||
awk -F'\t' '{printf "%-10s %8d KB (%.1f MB)\n", $1, $2, $2/1024}' mem-profile.csv.peak
|
||||
else
|
||||
echo "no memory samples captured"
|
||||
fi
|
||||
echo '```'
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: Profile summary
|
||||
if: always()
|
||||
run: |
|
||||
{
|
||||
echo "## CPU profile (top functions)"
|
||||
echo '```'
|
||||
head -45 cpu-top.txt 2>/dev/null || echo "no cpu profile captured"
|
||||
echo '```'
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: Stop server
|
||||
if: always()
|
||||
run: kill "${WEED_PID}" 2>/dev/null || true
|
||||
|
||||
- name: Show server log on failure
|
||||
if: failure()
|
||||
run: tail -200 weed.log || true
|
||||
|
||||
- name: Upload profiles
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: performance-profile-${{ github.run_number }}
|
||||
path: |
|
||||
cpu.pprof
|
||||
heap.pprof
|
||||
cpu-top.txt
|
||||
heap-top.txt
|
||||
goroutine.txt
|
||||
mem-profile.csv
|
||||
mem-profile.csv.peak
|
||||
weed.log
|
||||
retention-days: 30
|
||||
|
||||
benchmark:
|
||||
name: Throughput Benchmark (${{ matrix.impl }} volume)
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 60
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
impl: [go, rust]
|
||||
env:
|
||||
IMPL: ${{ matrix.impl }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Install Rust toolchain
|
||||
if: matrix.impl == 'rust'
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
if: matrix.impl == 'rust'
|
||||
uses: actions/cache@v6
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
key: rust-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-
|
||||
|
||||
- name: Build weed
|
||||
run: go build -o weed_bin ./weed
|
||||
|
||||
- name: Build Rust volume server
|
||||
if: matrix.impl == 'rust'
|
||||
run: cd seaweed-volume && cargo build --release
|
||||
|
||||
- name: Start master and volume server
|
||||
run: |
|
||||
mkdir -p ./perfdata/master ./perfdata/vol
|
||||
./weed_bin -v=1 master -ip=127.0.0.1 -port=9333 \
|
||||
-mdir=./perfdata/master -peers=none \
|
||||
-volumeSizeLimitMB="${VOL_SIZE_LIMIT}" -defaultReplication=000 \
|
||||
> master.log 2>&1 &
|
||||
echo "MASTER_PID=$!" >> "$GITHUB_ENV"
|
||||
for i in $(seq 1 60); do
|
||||
if curl -sf http://localhost:9333/dir/status >/dev/null 2>&1; then
|
||||
echo "master is ready"
|
||||
break
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
if [ "${IMPL}" = "rust" ]; then
|
||||
./seaweed-volume/target/release/weed-volume \
|
||||
--master 127.0.0.1:9333 --ip 127.0.0.1 --ip.bind 127.0.0.1 \
|
||||
--port 8080 --dir ./perfdata/vol --max 100 --preStopSeconds 0 \
|
||||
> volume.log 2>&1 &
|
||||
else
|
||||
./weed_bin -v=1 volume -master=127.0.0.1:9333 -ip=127.0.0.1 \
|
||||
-port=8080 -dir=./perfdata/vol -max=100 \
|
||||
> volume.log 2>&1 &
|
||||
fi
|
||||
echo "VOLUME_PID=$!" >> "$GITHUB_ENV"
|
||||
for i in $(seq 1 60); do
|
||||
if curl -sf http://localhost:8080/status >/dev/null 2>&1; then
|
||||
echo "volume server is ready"
|
||||
break
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
# let the volume server register with the master via heartbeat
|
||||
sleep 3
|
||||
|
||||
- name: Start memory sampler
|
||||
run: |
|
||||
bash test/perf/mem_sample.sh mem-benchmark.csv \
|
||||
"master=${MASTER_PID}" "volume=${VOLUME_PID}" &
|
||||
echo "SAMPLER_PID=$!" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Run throughput benchmark
|
||||
run: |
|
||||
N="${{ github.event.inputs.benchmark_files || '100000' }}"
|
||||
C="${{ github.event.inputs.benchmark_concurrency || '16' }}"
|
||||
SIZE="${{ github.event.inputs.benchmark_size || '1024' }}"
|
||||
./weed_bin benchmark -master=localhost:9333 \
|
||||
-c="${C}" -n="${N}" -size="${SIZE}" 2>&1 | tee benchmark-results.txt
|
||||
|
||||
- name: Run Go micro-benchmarks
|
||||
if: matrix.impl == 'go'
|
||||
continue-on-error: true
|
||||
run: |
|
||||
go test -run='^$' -bench=. -benchmem -benchtime=10x \
|
||||
./weed/topology/... ./weed/util/log_buffer/... ./weed/util/buffered_queue/... \
|
||||
2>&1 | tee go-benchmarks.txt
|
||||
|
||||
- name: Record memory usage
|
||||
if: always()
|
||||
run: |
|
||||
kill -TERM "${SAMPLER_PID}" 2>/dev/null || true
|
||||
sleep 2
|
||||
{
|
||||
echo "## Memory usage (peak RSS, ${IMPL} volume)"
|
||||
echo '```'
|
||||
if [ -f mem-benchmark.csv.peak ]; then
|
||||
awk -F'\t' '{printf "%-10s %8d KB (%.1f MB)\n", $1, $2, $2/1024}' mem-benchmark.csv.peak
|
||||
else
|
||||
echo "no memory samples captured"
|
||||
fi
|
||||
echo '```'
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: Benchmark summary
|
||||
if: always()
|
||||
run: |
|
||||
{
|
||||
echo "## Throughput benchmark (${IMPL} volume)"
|
||||
echo '```'
|
||||
grep -E "Concurrency Level|Time taken|Completed requests|Failed requests|Requests per second|Transfer rate" \
|
||||
benchmark-results.txt 2>/dev/null || echo "no benchmark results captured"
|
||||
echo '```'
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: Stop processes
|
||||
if: always()
|
||||
run: |
|
||||
kill "${VOLUME_PID}" "${MASTER_PID}" 2>/dev/null || true
|
||||
|
||||
- name: Show logs on failure
|
||||
if: failure()
|
||||
run: |
|
||||
echo "=== master.log ==="; tail -100 master.log 2>/dev/null || true
|
||||
echo "=== volume.log ==="; tail -200 volume.log 2>/dev/null || true
|
||||
|
||||
- name: Upload benchmark results
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: benchmark-results-${{ matrix.impl }}-${{ github.run_number }}
|
||||
path: |
|
||||
benchmark-results.txt
|
||||
go-benchmarks.txt
|
||||
mem-benchmark.csv
|
||||
mem-benchmark.csv.peak
|
||||
master.log
|
||||
volume.log
|
||||
retention-days: 7
|
||||
|
||||
s3-benchmark:
|
||||
name: S3 Read/Write Benchmark (${{ matrix.impl }} volume)
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 60
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
impl: [go, rust]
|
||||
env:
|
||||
IMPL: ${{ matrix.impl }}
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Install Rust toolchain
|
||||
if: matrix.impl == 'rust'
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
if: matrix.impl == 'rust'
|
||||
uses: actions/cache@v6
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
key: rust-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-
|
||||
|
||||
- name: Build weed and S3 load tool
|
||||
run: |
|
||||
go build -o weed_bin ./weed
|
||||
go build -o s3bench ./test/s3/benchmark
|
||||
|
||||
- name: Build Rust volume server
|
||||
if: matrix.impl == 'rust'
|
||||
run: cd seaweed-volume && cargo build --release
|
||||
|
||||
- name: Start cluster with S3 gateway
|
||||
run: |
|
||||
mkdir -p ./perfdata/master ./perfdata/vol ./perfdata/filer
|
||||
./weed_bin -v=1 master -ip=127.0.0.1 -port=9333 \
|
||||
-mdir=./perfdata/master -peers=none \
|
||||
-volumeSizeLimitMB="${VOL_SIZE_LIMIT}" -defaultReplication=000 \
|
||||
> master.log 2>&1 &
|
||||
echo "MASTER_PID=$!" >> "$GITHUB_ENV"
|
||||
for i in $(seq 1 60); do
|
||||
if curl -sf http://localhost:9333/dir/status >/dev/null 2>&1; then
|
||||
echo "master is ready"
|
||||
break
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
if [ "${IMPL}" = "rust" ]; then
|
||||
./seaweed-volume/target/release/weed-volume \
|
||||
--master 127.0.0.1:9333 --ip 127.0.0.1 --ip.bind 127.0.0.1 \
|
||||
--port 8080 --dir ./perfdata/vol --max 100 --preStopSeconds 0 \
|
||||
> volume.log 2>&1 &
|
||||
else
|
||||
./weed_bin -v=1 volume -master=127.0.0.1:9333 -ip=127.0.0.1 \
|
||||
-port=8080 -dir=./perfdata/vol -max=100 \
|
||||
> volume.log 2>&1 &
|
||||
fi
|
||||
echo "VOLUME_PID=$!" >> "$GITHUB_ENV"
|
||||
for i in $(seq 1 60); do
|
||||
if curl -sf http://localhost:8080/status >/dev/null 2>&1; then
|
||||
echo "volume server is ready"
|
||||
break
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
sleep 3
|
||||
./weed_bin -v=1 filer -master=127.0.0.1:9333 -ip=127.0.0.1 -port=8888 \
|
||||
-s3 -s3.port=8000 -s3.config=./docker/compose/s3.json \
|
||||
> filer.log 2>&1 &
|
||||
echo "FILER_PID=$!" >> "$GITHUB_ENV"
|
||||
for i in $(seq 1 30); do
|
||||
if nc -z localhost 8000 2>/dev/null; then
|
||||
echo "s3 gateway is ready"
|
||||
break
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
sleep 2
|
||||
|
||||
- name: Start memory sampler
|
||||
run: |
|
||||
bash test/perf/mem_sample.sh mem-s3.csv \
|
||||
"master=${MASTER_PID}" "volume=${VOLUME_PID}" "filer=${FILER_PID}" &
|
||||
echo "SAMPLER_PID=$!" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Run S3 read/write benchmark
|
||||
run: |
|
||||
OBJECTS="${{ github.event.inputs.s3_objects || '20000' }}"
|
||||
C="${{ github.event.inputs.benchmark_concurrency || '16' }}"
|
||||
SIZE="${{ github.event.inputs.s3_size || '4096' }}"
|
||||
./s3bench -endpoint=http://localhost:8000 \
|
||||
-access-key=some_access_key1 -secret-key=some_secret_key1 \
|
||||
-objects="${OBJECTS}" -size="${SIZE}" -concurrency="${C}" -mode=both \
|
||||
2>&1 | tee s3-benchmark-results.txt
|
||||
|
||||
- name: Record memory usage
|
||||
if: always()
|
||||
run: |
|
||||
kill -TERM "${SAMPLER_PID}" 2>/dev/null || true
|
||||
sleep 2
|
||||
{
|
||||
echo "## Memory usage (peak RSS, ${IMPL} volume)"
|
||||
echo '```'
|
||||
if [ -f mem-s3.csv.peak ]; then
|
||||
awk -F'\t' '{printf "%-10s %8d KB (%.1f MB)\n", $1, $2, $2/1024}' mem-s3.csv.peak
|
||||
else
|
||||
echo "no memory samples captured"
|
||||
fi
|
||||
echo '```'
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: S3 benchmark summary
|
||||
if: always()
|
||||
run: |
|
||||
{
|
||||
echo "## S3 read/write benchmark (${IMPL} volume)"
|
||||
echo '```'
|
||||
grep -E "results:|Concurrency Level|Time taken|Completed requests|Failed requests|Requests per second|Transfer rate|Latency" \
|
||||
s3-benchmark-results.txt 2>/dev/null || echo "no S3 benchmark results captured"
|
||||
echo '```'
|
||||
} >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
- name: Stop processes
|
||||
if: always()
|
||||
run: |
|
||||
kill "${FILER_PID}" "${VOLUME_PID}" "${MASTER_PID}" 2>/dev/null || true
|
||||
|
||||
- name: Show logs on failure
|
||||
if: failure()
|
||||
run: |
|
||||
echo "=== master.log ==="; tail -100 master.log 2>/dev/null || true
|
||||
echo "=== volume.log ==="; tail -200 volume.log 2>/dev/null || true
|
||||
echo "=== filer.log ==="; tail -200 filer.log 2>/dev/null || true
|
||||
|
||||
- name: Upload S3 benchmark results
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: s3-benchmark-results-${{ matrix.impl }}-${{ github.run_number }}
|
||||
path: |
|
||||
s3-benchmark-results.txt
|
||||
mem-s3.csv
|
||||
mem-s3.csv.peak
|
||||
master.log
|
||||
volume.log
|
||||
filer.log
|
||||
retention-days: 7
|
||||
@@ -32,10 +32,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -3,20 +3,8 @@ name: "Plugin Worker Integration Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/plugin_workers/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/plugin-workers.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/plugin_workers/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/plugin-workers.yml'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
@@ -39,13 +27,13 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
id: go
|
||||
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Run plugin worker tests
|
||||
run: go test -v ./${{ matrix.path }}
|
||||
|
||||
@@ -3,24 +3,8 @@ name: "PostgreSQL Gateway Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/server/postgres/**'
|
||||
- 'weed/query/**'
|
||||
- 'weed/mq/**'
|
||||
- 'test/postgres/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/postgres-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/server/postgres/**'
|
||||
- 'weed/query/**'
|
||||
- 'weed/mq/**'
|
||||
- 'test/postgres/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/postgres-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/postgres-tests
|
||||
@@ -39,24 +23,19 @@ jobs:
|
||||
working-directory: test/postgres
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Cache Docker layers
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: /tmp/.buildx-cache
|
||||
key: ${{ runner.os }}-buildx-postgres-${{ github.sha }}
|
||||
|
||||
@@ -1,278 +0,0 @@
|
||||
name: "release: bump version and cut the release"
|
||||
|
||||
# One entry point for a SeaweedFS release:
|
||||
# 1. bump MAJOR/MINOR in constants.go and the Helm Chart.yaml, commit to master
|
||||
# 2. push the <appVersion> tag, which fans out to the workflows that trigger on
|
||||
# `push: tags` (binaries_release*, container_release_unified, helm_manual_release)
|
||||
# 3. create the GitHub release, with GitHub's generated notes
|
||||
# 4. dispatch "Prepare release" in seaweedfs-csi-driver and seaweedfs-operator,
|
||||
# which pick up the new master through `go get -u`, and wait for both
|
||||
#
|
||||
# Events raised by the default GITHUB_TOKEN do not start other workflows, and it
|
||||
# cannot reach the other two repositories at all. Add a repo secret RELEASE_PAT
|
||||
# with `contents: write` here and `actions: write` on the csi-driver and operator
|
||||
# repos. Without it the tag is still pushed, but nothing downstream of it runs.
|
||||
|
||||
on:
|
||||
workflow_dispatch:
|
||||
inputs:
|
||||
bump:
|
||||
description: "Which part to increment (ignored when 'version' is set)"
|
||||
type: choice
|
||||
options:
|
||||
- minor
|
||||
- major
|
||||
default: minor
|
||||
version:
|
||||
description: "Explicit MAJOR.MINOR to set, e.g. 4.36 (overrides 'bump')"
|
||||
type: string
|
||||
required: false
|
||||
downstream:
|
||||
description: "Also release the CSI driver and the operator"
|
||||
type: boolean
|
||||
default: true
|
||||
dry_run:
|
||||
description: "Show the version bump, but change nothing"
|
||||
type: boolean
|
||||
default: false
|
||||
|
||||
jobs:
|
||||
release:
|
||||
runs-on: ubuntu-latest
|
||||
permissions:
|
||||
contents: write
|
||||
outputs:
|
||||
app_version: ${{ steps.compute.outputs.app_version }}
|
||||
sha: ${{ steps.tag.outputs.sha }}
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
ref: master
|
||||
fetch-depth: 0
|
||||
token: ${{ secrets.RELEASE_PAT || secrets.GITHUB_TOKEN }}
|
||||
|
||||
- name: Check the release token
|
||||
env:
|
||||
HAS_PAT: ${{ secrets.RELEASE_PAT != '' }}
|
||||
run: |
|
||||
if [ "$HAS_PAT" != "true" ]; then
|
||||
echo "::warning::RELEASE_PAT is not set. The tag will be pushed with GITHUB_TOKEN, so the binary, container and helm workflows will not start on their own."
|
||||
fi
|
||||
|
||||
- name: Compute new version
|
||||
id: compute
|
||||
env:
|
||||
BUMP: ${{ inputs.bump }}
|
||||
INPUT_VERSION: ${{ inputs.version }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
CONST=weed/util/version/constants.go
|
||||
|
||||
MAJOR=$(grep -oP 'MAJOR_VERSION\s*=\s*int32\(\K[0-9]+' "$CONST")
|
||||
MINOR=$(grep -oP 'MINOR_VERSION\s*=\s*int32\(\K[0-9]+' "$CONST")
|
||||
echo "current: ${MAJOR}.${MINOR}"
|
||||
|
||||
if [ -n "$INPUT_VERSION" ]; then
|
||||
if ! [[ "$INPUT_VERSION" =~ ^[0-9]+\.[0-9]+$ ]]; then
|
||||
echo "::error::version must be MAJOR.MINOR, e.g. 5.01 (got '$INPUT_VERSION')"
|
||||
exit 1
|
||||
fi
|
||||
# 10# forces base 10 so 08/09 are not parsed as octal.
|
||||
MAJOR=$((10#${INPUT_VERSION%%.*}))
|
||||
MINOR=$((10#${INPUT_VERSION##*.}))
|
||||
if [ "$MINOR" -gt 99 ]; then
|
||||
echo "::error::minor must be 0-99 (got $MINOR); it rolls into the next major at 99"
|
||||
exit 1
|
||||
fi
|
||||
else
|
||||
case "$BUMP" in
|
||||
# Minor is a 2-digit field: 4.99 -> 5.00 -> 5.01.
|
||||
major) MAJOR=$((MAJOR + 1)); MINOR=0 ;;
|
||||
minor)
|
||||
if [ "$MINOR" -ge 99 ]; then
|
||||
MAJOR=$((MAJOR + 1)); MINOR=0
|
||||
else
|
||||
MINOR=$((MINOR + 1))
|
||||
fi
|
||||
;;
|
||||
*) echo "::error::unknown bump '$BUMP'"; exit 1 ;;
|
||||
esac
|
||||
fi
|
||||
|
||||
# appVersion mirrors the Go VERSION_NUMBER (zero-padded minor);
|
||||
# chart version is plain SemVer (no leading zeros).
|
||||
APP_VERSION=$(printf '%d.%02d' "$MAJOR" "$MINOR")
|
||||
CHART_VERSION="${MAJOR}.${MINOR}.0"
|
||||
echo "new: app=${APP_VERSION} chart=${CHART_VERSION}"
|
||||
|
||||
{
|
||||
echo "major=${MAJOR}"
|
||||
echo "minor=${MINOR}"
|
||||
echo "app_version=${APP_VERSION}"
|
||||
echo "chart_version=${CHART_VERSION}"
|
||||
} >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Apply version to constants.go
|
||||
env:
|
||||
MAJOR: ${{ steps.compute.outputs.major }}
|
||||
MINOR: ${{ steps.compute.outputs.minor }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
CONST=weed/util/version/constants.go
|
||||
sed -i -E "s/(MAJOR_VERSION[[:space:]]*=[[:space:]]*int32\()[0-9]+(\))/\1${MAJOR}\2/" "$CONST"
|
||||
sed -i -E "s/(MINOR_VERSION[[:space:]]*=[[:space:]]*int32\()[0-9]+(\))/\1${MINOR}\2/" "$CONST"
|
||||
grep -E 'MAJOR_VERSION|MINOR_VERSION' "$CONST"
|
||||
|
||||
- name: Apply version to Chart.yaml
|
||||
env:
|
||||
APP_VERSION: ${{ steps.compute.outputs.app_version }}
|
||||
CHART_VERSION: ${{ steps.compute.outputs.chart_version }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
CHART=k8s/charts/seaweedfs/Chart.yaml
|
||||
sed -i -E "s/^appVersion:.*/appVersion: \"${APP_VERSION}\"/" "$CHART"
|
||||
sed -i -E "s/^version:.*/version: ${CHART_VERSION}/" "$CHART"
|
||||
cat "$CHART"
|
||||
|
||||
- name: Commit, and push the tag
|
||||
id: tag
|
||||
env:
|
||||
TAG: ${{ steps.compute.outputs.app_version }}
|
||||
DRY_RUN: ${{ inputs.dry_run }}
|
||||
run: |
|
||||
set -euo pipefail
|
||||
if git ls-remote --exit-code --tags origin "refs/tags/${TAG}" >/dev/null 2>&1; then
|
||||
echo "::error::Tag ${TAG} already exists."
|
||||
exit 1
|
||||
fi
|
||||
if [ "$DRY_RUN" = "true" ]; then
|
||||
git --no-pager diff --stat
|
||||
echo "sha=$(git rev-parse HEAD)" >> "$GITHUB_OUTPUT"
|
||||
exit 0
|
||||
fi
|
||||
|
||||
git config user.name "github-actions[bot]"
|
||||
git config user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
if git diff --quiet; then
|
||||
echo "::warning::Version files are already at ${TAG}; tagging the current HEAD."
|
||||
else
|
||||
git add weed/util/version/constants.go k8s/charts/seaweedfs/Chart.yaml
|
||||
git commit -m "${TAG}"
|
||||
git push
|
||||
fi
|
||||
|
||||
# Push the tag with git so the `push: tags` triggers fire. Creating the
|
||||
# tag through the release API alone would only emit a `create` event.
|
||||
git tag "$TAG"
|
||||
git push origin "$TAG"
|
||||
echo "sha=$(git rev-parse HEAD)" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Create the release
|
||||
if: ${{ !inputs.dry_run }}
|
||||
env:
|
||||
GH_TOKEN: ${{ secrets.RELEASE_PAT || secrets.GITHUB_TOKEN }}
|
||||
TAG: ${{ steps.compute.outputs.app_version }}
|
||||
run: gh release create "$TAG" --title "$TAG" --generate-notes --verify-tag
|
||||
|
||||
downstream:
|
||||
needs: release
|
||||
if: ${{ inputs.downstream && !inputs.dry_run }}
|
||||
runs-on: ubuntu-latest
|
||||
# The wait below puts no bound of its own on runner-queue time; this does.
|
||||
timeout-minutes: 120
|
||||
permissions: {}
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
- repo: seaweedfs/seaweedfs-csi-driver
|
||||
workflow: prepare_release.yaml
|
||||
- repo: seaweedfs/seaweedfs-operator
|
||||
workflow: prepare_release.yml
|
||||
steps:
|
||||
- name: Release ${{ matrix.repo }}
|
||||
env:
|
||||
GH_TOKEN: ${{ secrets.RELEASE_PAT }}
|
||||
REPO: ${{ matrix.repo }}
|
||||
WORKFLOW: ${{ matrix.workflow }}
|
||||
SHA: ${{ needs.release.outputs.sha }}
|
||||
MODULE: github.com/seaweedfs/seaweedfs
|
||||
run: |
|
||||
set -euo pipefail
|
||||
if [ -z "${GH_TOKEN}" ]; then
|
||||
echo "::error::RELEASE_PAT with actions:write on ${REPO} is required to release it"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# The dispatched workflow pins seaweedfs with `go get -u ...@latest`, so
|
||||
# wait until the proxy serves the release commit as the tip. Asking for
|
||||
# the commit by name is what makes the proxy fetch it. The proxy can
|
||||
# take longer than five minutes to refresh @latest after a new tag.
|
||||
for _ in $(seq 120); do
|
||||
curl -sf "https://proxy.golang.org/${MODULE}/@v/${SHA}.info" >/dev/null || true
|
||||
TIP=$(curl -sf "https://proxy.golang.org/${MODULE}/@latest" | jq -r '.Origin.Hash // ""' || true)
|
||||
[ "$TIP" = "$SHA" ] && break
|
||||
sleep 10
|
||||
done
|
||||
if [ "$TIP" != "$SHA" ]; then
|
||||
echo "::error::the module proxy still serves ${TIP} as the tip, so ${REPO} would pin a pre-release commit. Run ${WORKFLOW} there once it catches up."
|
||||
exit 1
|
||||
fi
|
||||
|
||||
# The dispatched workflow publishes the release as its last step, so
|
||||
# its conclusion decides success. Wait on the run, not on a wall
|
||||
# clock: time it spends queued for a runner must not count against
|
||||
# the budget. A dispatch does not return its run id, so take the
|
||||
# newest workflow_dispatch run created since ours; a concurrent
|
||||
# dispatch would be performing this same release, and waiting on it
|
||||
# is just as good.
|
||||
released() { gh api "repos/${REPO}/releases?per_page=30" --jq '[.[].tag_name]'; }
|
||||
|
||||
BEFORE=$(released)
|
||||
# A minute early, so runner clock skew cannot hide the run.
|
||||
DISPATCHED_AT=$(date -u -d '1 minute ago' '+%Y-%m-%dT%H:%M:%SZ')
|
||||
gh workflow run -R "$REPO" "$WORKFLOW" --ref master -f bump=patch -f update_seaweedfs=true
|
||||
|
||||
RUN_ID=""
|
||||
for _ in $(seq 12); do
|
||||
sleep 10
|
||||
RUN_ID=$(gh api -X GET "repos/${REPO}/actions/workflows/${WORKFLOW}/runs" \
|
||||
-f event=workflow_dispatch -f "created=>=${DISPATCHED_AT}" \
|
||||
--jq '(.workflow_runs | sort_by(.created_at) | last | .id) // empty' || true)
|
||||
[ -n "$RUN_ID" ] && break
|
||||
done
|
||||
if [ -z "$RUN_ID" ]; then
|
||||
echo "::error::the dispatch created no ${WORKFLOW} run in ${REPO}; see https://github.com/${REPO}/actions/workflows/${WORKFLOW}"
|
||||
exit 1
|
||||
fi
|
||||
RUN_URL="https://github.com/${REPO}/actions/runs/${RUN_ID}"
|
||||
echo "waiting on ${RUN_URL}"
|
||||
|
||||
# 20 minutes of execution; polls that find the run still queued do
|
||||
# not consume it.
|
||||
RUNNING=0
|
||||
STATE=""
|
||||
while :; do
|
||||
sleep 15
|
||||
STATE=$(gh api "repos/${REPO}/actions/runs/${RUN_ID}" \
|
||||
--jq '.status + "/" + (.conclusion // "")' || true)
|
||||
case "$STATE" in
|
||||
completed/*) break ;;
|
||||
in_progress/*) RUNNING=$((RUNNING + 1)) ;;
|
||||
esac
|
||||
if [ "$RUNNING" -gt 80 ]; then
|
||||
echo "::error::${RUN_URL} has been executing for over 20 minutes; giving up on it"
|
||||
exit 1
|
||||
fi
|
||||
done
|
||||
if [ "$STATE" != "completed/success" ]; then
|
||||
echo "::error::${RUN_URL} concluded '${STATE#completed/}'"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
NEW=$(released | jq -c --argjson before "$BEFORE" '. - $before')
|
||||
if [ "$(jq length <<<"$NEW")" -eq 0 ]; then
|
||||
echo "::error::${RUN_URL} succeeded but ${REPO} shows no new release"
|
||||
exit 1
|
||||
fi
|
||||
echo "${REPO} released $(jq -r 'join(", ")' <<<"$NEW")"
|
||||
@@ -5,7 +5,6 @@ on:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'seaweed-volume/**'
|
||||
- 'seaweed-common/**'
|
||||
- 'test/volume_server/**'
|
||||
- 'weed/pb/volume_server.proto'
|
||||
- 'weed/pb/volume_server_pb/**'
|
||||
@@ -14,7 +13,6 @@ on:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'seaweed-volume/**'
|
||||
- 'seaweed-common/**'
|
||||
- 'test/volume_server/**'
|
||||
- 'weed/pb/volume_server.proto'
|
||||
- 'weed/pb/volume_server_pb/**'
|
||||
@@ -29,29 +27,6 @@ permissions:
|
||||
|
||||
|
||||
jobs:
|
||||
changes:
|
||||
name: Detect changed paths
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 5
|
||||
permissions:
|
||||
contents: read
|
||||
outputs:
|
||||
rust: ${{ steps.filter.outputs.rust }}
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
fetch-depth: 0
|
||||
|
||||
- name: Filter changed paths
|
||||
id: filter
|
||||
uses: dorny/paths-filter@v4
|
||||
with:
|
||||
filters: |
|
||||
rust:
|
||||
- 'seaweed-volume/**'
|
||||
- '.github/workflows/rust-volume-server-tests.yml'
|
||||
|
||||
rust-unit-tests:
|
||||
name: Rust Unit Tests
|
||||
runs-on: ubuntu-22.04
|
||||
@@ -59,97 +34,31 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
# cargo tracks its own inputs but not the runner's C toolchain, so a cached
|
||||
# target/ can carry C objects built against a different glibc than we link against.
|
||||
- name: Fingerprint build toolchain
|
||||
id: toolchain
|
||||
run: echo "fingerprint=$(getconf GNU_LIBC_VERSION | tr ' ' '-')-rustc-$(rustc -V | awk '{print $2}')" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
key: rust-${{ steps.toolchain.outputs.fingerprint }}-${{ hashFiles('seaweed-volume/Cargo.lock', 'seaweed-common/Cargo.lock') }}
|
||||
key: rust-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-${{ steps.toolchain.outputs.fingerprint }}-
|
||||
rust-
|
||||
|
||||
- name: Build Rust volume server
|
||||
run: cd seaweed-volume && cargo build --release
|
||||
|
||||
# The crate is warning-free under clippy as of the sweep that added
|
||||
# this step. Uncomment to make that a gate; `[lints.clippy]` in
|
||||
# seaweed-volume/Cargo.toml is where crate-wide exceptions live.
|
||||
# - name: Clippy
|
||||
# run: cd seaweed-volume && cargo clippy --all-targets -- -D warnings
|
||||
|
||||
# The crate is rustfmt-clean as of the PR that added this step.
|
||||
# Uncomment to keep it that way.
|
||||
# - name: Check formatting
|
||||
# run: cd seaweed-volume && cargo fmt --check
|
||||
|
||||
# seaweed-common is a path dependency of this crate, not a member of its
|
||||
# workspace, so the run below does not reach its own tests. It builds into
|
||||
# this job's cached target directory, and the cache key above covers the
|
||||
# shared crate's lock, so the aws-lc-sys that rustls pulls in is restored
|
||||
# with the cache instead of compiled from scratch on every run.
|
||||
- name: Run shared-crate unit tests
|
||||
env:
|
||||
CARGO_TARGET_DIR: ${{ github.workspace }}/seaweed-volume/target
|
||||
run: cd seaweed-common && cargo test
|
||||
|
||||
- name: Run Rust unit tests
|
||||
run: cd seaweed-volume && cargo test
|
||||
|
||||
- name: Run Rust unit tests (redb experimental cursor)
|
||||
run: cd seaweed-volume && cargo test --features redb-experimental-cursor --lib storage::needle_map
|
||||
|
||||
rust-unit-tests-windows:
|
||||
name: Rust Unit Tests (Windows)
|
||||
runs-on: windows-latest
|
||||
timeout-minutes: 30
|
||||
needs: [changes]
|
||||
if: needs.changes.outputs.rust == 'true'
|
||||
defaults:
|
||||
run:
|
||||
shell: bash
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
# No glibc on Windows: key the cache on the toolchain and OS only.
|
||||
- name: Fingerprint build toolchain
|
||||
id: toolchain
|
||||
run: echo "fingerprint=windows-rustc-$(rustc -V | awk '{print $2}')" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
key: rust-windows-${{ steps.toolchain.outputs.fingerprint }}-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-windows-${{ steps.toolchain.outputs.fingerprint }}-
|
||||
|
||||
- name: Run Rust unit tests
|
||||
run: cd seaweed-volume && cargo test
|
||||
|
||||
- name: Run Rust unit tests (redb experimental cursor)
|
||||
run: cd seaweed-volume && cargo test --features redb-experimental-cursor --lib storage::needle_map
|
||||
|
||||
rust-integration-tests:
|
||||
name: Rust Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
@@ -157,32 +66,29 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
# cargo tracks its own inputs but not the runner's C toolchain, so a cached
|
||||
# target/ can carry C objects built against a different glibc than we link against.
|
||||
- name: Fingerprint build toolchain
|
||||
id: toolchain
|
||||
run: echo "fingerprint=$(getconf GNU_LIBC_VERSION | tr ' ' '-')-rustc-$(rustc -V | awk '{print $2}')" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
key: rust-${{ steps.toolchain.outputs.fingerprint }}-${{ hashFiles('seaweed-volume/Cargo.lock', 'seaweed-common/Cargo.lock') }}
|
||||
key: rust-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-${{ steps.toolchain.outputs.fingerprint }}-
|
||||
rust-
|
||||
|
||||
- name: Build Go weed binary
|
||||
run: |
|
||||
@@ -228,9 +134,6 @@ jobs:
|
||||
name: Go Tests with Rust Volume (${{ matrix.test-type }} - Shard ${{ matrix.shard }})
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 45
|
||||
env:
|
||||
# Keep in step with the length of matrix.shard below.
|
||||
SHARD_COUNT: 3
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
@@ -239,32 +142,29 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
# cargo tracks its own inputs but not the runner's C toolchain, so a cached
|
||||
# target/ can carry C objects built against a different glibc than we link against.
|
||||
- name: Fingerprint build toolchain
|
||||
id: toolchain
|
||||
run: echo "fingerprint=$(getconf GNU_LIBC_VERSION | tr ' ' '-')-rustc-$(rustc -V | awk '{print $2}')" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-volume/target
|
||||
key: rust-${{ steps.toolchain.outputs.fingerprint }}-${{ hashFiles('seaweed-volume/Cargo.lock', 'seaweed-common/Cargo.lock') }}
|
||||
key: rust-${{ hashFiles('seaweed-volume/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-${{ steps.toolchain.outputs.fingerprint }}-
|
||||
rust-
|
||||
|
||||
- name: Build Go weed binary
|
||||
run: |
|
||||
@@ -276,28 +176,30 @@ jobs:
|
||||
- name: Build Rust volume binary
|
||||
run: cd seaweed-volume && cargo build --release
|
||||
|
||||
# Dealing the listed tests out one by one keeps the shards even. Bucketing
|
||||
# them by first letter did not: names cluster, so ^Test[I-S] drew 50 of
|
||||
# the 114 grpc tests and ran nearly twice as long as the other two shards.
|
||||
- name: Select this shard's tests
|
||||
env:
|
||||
TEST_TYPE: ${{ matrix.test-type }}
|
||||
SHARD: ${{ matrix.shard }}
|
||||
run: |
|
||||
tests=$(go test -tags 5BytesOffset ./test/volume_server/"$TEST_TYPE"/... -list '.*' | grep '^Test' | sort -u)
|
||||
# An empty list would make -run match nothing and the shard pass vacuously.
|
||||
[ -n "$tests" ] || { echo "listed no tests in test/volume_server/$TEST_TYPE"; exit 1; }
|
||||
selected=$(echo "$tests" | awk -v n="$SHARD_COUNT" -v i="$SHARD" 'NR % n == i - 1')
|
||||
echo "shard $SHARD of $SHARD_COUNT runs $(echo "$selected" | wc -l) of $(echo "$tests" | wc -l) tests"
|
||||
echo "TEST_PATTERN=^($(echo "$selected" | paste -sd'|' -))\$" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Run volume server integration tests with Rust volume
|
||||
env:
|
||||
WEED_BINARY: ${{ github.workspace }}/weed/weed
|
||||
RUST_VOLUME_BINARY: ${{ github.workspace }}/seaweed-volume/target/release/weed-volume
|
||||
VOLUME_SERVER_IMPL: rust
|
||||
run: |
|
||||
echo "Running Go volume server tests with Rust volume for ${{ matrix.test-type }} (Shard ${{ matrix.shard }} of ${SHARD_COUNT})..."
|
||||
if [ "${{ matrix.test-type }}" == "grpc" ]; then
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-H]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[I-S]"
|
||||
else
|
||||
TEST_PATTERN="^Test[T-Z]"
|
||||
fi
|
||||
else
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-G]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[H-R]"
|
||||
else
|
||||
TEST_PATTERN="^Test[S-Z]"
|
||||
fi
|
||||
fi
|
||||
echo "Running Go volume server tests with Rust volume for ${{ matrix.test-type }} (Shard ${{ matrix.shard }}, pattern: ${TEST_PATTERN})..."
|
||||
go test -v -count=1 -tags 5BytesOffset -timeout=30m ./test/volume_server/${{ matrix.test-type }}/... -run "${TEST_PATTERN}"
|
||||
|
||||
- name: Collect logs on failure
|
||||
@@ -318,6 +220,23 @@ jobs:
|
||||
- name: Test summary
|
||||
if: always()
|
||||
run: |
|
||||
if [ "${{ matrix.test-type }}" == "grpc" ]; then
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-H]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[I-S]"
|
||||
else
|
||||
TEST_PATTERN="^Test[T-Z]"
|
||||
fi
|
||||
else
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-G]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[H-R]"
|
||||
else
|
||||
TEST_PATTERN="^Test[S-Z]"
|
||||
fi
|
||||
fi
|
||||
echo "## Rust Volume - Go Test Summary (${{ matrix.test-type }} - Shard ${{ matrix.shard }})" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Suite: test/volume_server/${{ matrix.test-type }} (shard ${{ matrix.shard }} of ${SHARD_COUNT}, see 'Select this shard's tests' for the split)" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Suite: test/volume_server/${{ matrix.test-type }} (Pattern: ${TEST_PATTERN})" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Volume server: Rust (VOLUME_SERVER_IMPL=rust)" >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
@@ -1,106 +0,0 @@
|
||||
name: "Rust Plugin Worker Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'seaweed-worker/**'
|
||||
- 'seaweed-common/**'
|
||||
- 'weed/pb/plugin.proto'
|
||||
- '.github/workflows/rust-worker-tests.yml'
|
||||
push:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'seaweed-worker/**'
|
||||
- 'seaweed-common/**'
|
||||
- 'weed/pb/plugin.proto'
|
||||
- '.github/workflows/rust-worker-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.workflow }}-${{ github.head_ref || github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
rust-worker-build:
|
||||
name: Rust Plugin Worker Build and Unit Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 45
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
# cargo tracks its own inputs but not the runner's C toolchain, so a cached
|
||||
# target/ can carry C objects built against a different glibc than we link against.
|
||||
- name: Fingerprint build toolchain
|
||||
id: toolchain
|
||||
run: echo "fingerprint=$(getconf GNU_LIBC_VERSION | tr ' ' '-')-rustc-$(rustc -V | awk '{print $2}')" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-worker/target/release
|
||||
key: rust-worker-${{ steps.toolchain.outputs.fingerprint }}-${{ hashFiles('seaweed-worker/Cargo.lock', 'seaweed-common/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-worker-${{ steps.toolchain.outputs.fingerprint }}-
|
||||
|
||||
# lance's build scripts compile their own protos and look for a protoc.
|
||||
# Point them at the one protoc-bin-vendored ships, which seaweed-worker's
|
||||
# own build already uses, so no job depends on a system package and every
|
||||
# build sees the same version.
|
||||
- name: Use the vendored protoc
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo fetch
|
||||
# The version from the lock, not whatever else a restored cache holds.
|
||||
version=$(awk '/^name = "protoc-bin-vendored-linux-x86_64"$/{found=1; next} found && /^version = /{gsub(/"/,"",$3); print $3; exit}' Cargo.lock)
|
||||
test -n "$version" || { echo "protoc-bin-vendored-linux-x86_64 is not in Cargo.lock" >&2; exit 1; }
|
||||
protoc=$(find ~/.cargo/registry/src -path "*protoc-bin-vendored-linux-x86_64-$version/bin/protoc" | head -1)
|
||||
test -x "$protoc" || { echo "no vendored protoc $version in the registry" >&2; exit 1; }
|
||||
echo "PROTOC=$protoc" >> "$GITHUB_ENV"
|
||||
|
||||
# The release profile is what ships, and it is where the release and the
|
||||
# container builds would otherwise discover a break for the first time.
|
||||
- name: Build the plugin workers
|
||||
run: cd seaweed-worker && cargo build --release
|
||||
|
||||
# The workspace is warning-free under clippy as of the sweep that added
|
||||
# this step. Uncomment to make that a gate; `[workspace.lints.clippy]`
|
||||
# in seaweed-worker/Cargo.toml is where crate-wide exceptions live.
|
||||
# - name: Clippy
|
||||
# run: cd seaweed-worker && cargo clippy --workspace --all-targets -- -D warnings
|
||||
|
||||
# The workspace is rustfmt-clean as of the PR that added this step.
|
||||
# Uncomment to keep it that way.
|
||||
# - name: Check formatting
|
||||
# run: cd seaweed-worker && cargo fmt --all --check
|
||||
|
||||
# seaweed-common is a path dependency of core and lance, not a member of
|
||||
# this workspace, so `--workspace` below does not reach its own tests.
|
||||
# Release and this job's cached target directory, and the cache key above
|
||||
# covers the shared crate's lock. That lock pins the same rustls and
|
||||
# aws-lc-sys this workspace resolves, so the release build above has
|
||||
# already paid for them.
|
||||
- name: Run shared-crate unit tests
|
||||
env:
|
||||
CARGO_TARGET_DIR: ${{ github.workspace }}/seaweed-worker/target
|
||||
run: cd seaweed-common && cargo test --release
|
||||
|
||||
# The tests that need a live gateway skip themselves without one, the way
|
||||
# the Go integration tests skip without Docker; the lifecycle suite in
|
||||
# test/s3tables/lifecycle is what runs them against a real cluster.
|
||||
# Release, so this reuses the build above rather than compiling lance,
|
||||
# arrow and datafusion a second time in another profile.
|
||||
- name: Run unit tests
|
||||
run: cd seaweed-worker && cargo test --release --workspace
|
||||
@@ -5,7 +5,6 @@ on:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'seaweed-volume/**'
|
||||
- 'seaweed-common/**'
|
||||
- '.github/workflows/rust_binaries_dev.yml'
|
||||
|
||||
permissions:
|
||||
@@ -40,13 +39,16 @@ jobs:
|
||||
asset_suffix: linux-amd64
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
@@ -106,7 +108,10 @@ jobs:
|
||||
asset_suffix: darwin-amd64
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: brew install protobuf
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
@@ -114,7 +119,7 @@ jobs:
|
||||
targets: ${{ matrix.target }}
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
name: "rust: build versioned binaries"
|
||||
name: "rust: build versioned volume server binaries"
|
||||
|
||||
on:
|
||||
push:
|
||||
@@ -26,7 +26,10 @@ jobs:
|
||||
cross: true
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: sudo apt-get update && sudo apt-get install -y protobuf-compiler
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
@@ -48,7 +51,7 @@ jobs:
|
||||
echo "OPENSSL_LIB_DIR=/usr/lib/aarch64-linux-gnu" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
@@ -63,42 +66,34 @@ jobs:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
run: |
|
||||
cd seaweed-volume
|
||||
cargo build --release --target ${{ matrix.target }} --target-dir target/large-disk
|
||||
cargo build --release --target ${{ matrix.target }}
|
||||
|
||||
- name: Build Rust volume server (normal)
|
||||
env:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
run: |
|
||||
cd seaweed-volume
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features --target-dir target/normal
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features
|
||||
|
||||
- name: Package binaries
|
||||
run: |
|
||||
# Large disk (default, 5bytes feature)
|
||||
cp seaweed-volume/target/large-disk/${{ matrix.target }}/release/weed-volume weed-volume-large-disk
|
||||
cp seaweed-volume/target/${{ matrix.target }}/release/weed-volume weed-volume-large-disk
|
||||
tar czf weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz weed-volume-large-disk
|
||||
rm weed-volume-large-disk
|
||||
|
||||
# Normal volume size
|
||||
cp seaweed-volume/target/normal/${{ matrix.target }}/release/weed-volume weed-volume-normal
|
||||
cp seaweed-volume/target/${{ matrix.target }}/release/weed-volume weed-volume-normal
|
||||
tar czf weed-volume_${{ matrix.asset_suffix }}.tar.gz weed-volume-normal
|
||||
rm weed-volume-normal
|
||||
|
||||
- name: Generate md5 checksums
|
||||
run: |
|
||||
for f in weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz weed-volume_${{ matrix.asset_suffix }}.tar.gz; do
|
||||
md5sum "$f" > "$f.md5"
|
||||
done
|
||||
|
||||
- name: Upload release assets
|
||||
if: startsWith(github.ref, 'refs/tags/')
|
||||
uses: softprops/action-gh-release@v3
|
||||
with:
|
||||
files: |
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
@@ -109,105 +104,7 @@ jobs:
|
||||
name: rust-volume-${{ matrix.asset_suffix }}
|
||||
path: |
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
|
||||
# The Rust maintenance worker: Linux only, because it runs beside the cluster
|
||||
# it maintains rather than on a laptop, and its dependency tree (lance, arrow,
|
||||
# datafusion) makes every extra target an expensive build.
|
||||
build-rust-worker-linux:
|
||||
permissions:
|
||||
contents: write
|
||||
runs-on: ubuntu-22.04
|
||||
strategy:
|
||||
matrix:
|
||||
include:
|
||||
- target: x86_64-unknown-linux-gnu
|
||||
asset_suffix: linux_amd64
|
||||
- target: aarch64-unknown-linux-gnu
|
||||
asset_suffix: linux_arm64
|
||||
cross: true
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
with:
|
||||
# The upload step is handed a token explicitly; a cargo build script
|
||||
# should not find another one sitting in the checkout's git config.
|
||||
persist-credentials: false
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
with:
|
||||
targets: ${{ matrix.target }}
|
||||
|
||||
- name: Install cross-compilation tools
|
||||
if: matrix.cross
|
||||
run: |
|
||||
sudo dpkg --add-architecture arm64
|
||||
sudo sed -i 's/^deb /deb [arch=amd64] /' /etc/apt/sources.list
|
||||
echo "deb [arch=arm64] http://ports.ubuntu.com/ jammy main restricted universe multiverse" | sudo tee /etc/apt/sources.list.d/arm64.list
|
||||
echo "deb [arch=arm64] http://ports.ubuntu.com/ jammy-updates main restricted universe multiverse" | sudo tee -a /etc/apt/sources.list.d/arm64.list
|
||||
sudo apt-get update
|
||||
sudo apt-get install -y gcc-aarch64-linux-gnu
|
||||
echo "CARGO_TARGET_AARCH64_UNKNOWN_LINUX_GNU_LINKER=aarch64-linux-gnu-gcc" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
~/.cargo/git
|
||||
seaweed-worker/target/${{ matrix.target }}/release
|
||||
key: rust-worker-release-${{ matrix.target }}-${{ hashFiles('seaweed-worker/Cargo.lock') }}
|
||||
restore-keys: |
|
||||
rust-worker-release-${{ matrix.target }}-
|
||||
|
||||
# lance's build scripts compile their own protos and look for a protoc.
|
||||
# Point them at the one protoc-bin-vendored ships, which seaweed-worker's
|
||||
# own build already uses, so no job depends on a system package and every
|
||||
# build sees the same version.
|
||||
- name: Use the vendored protoc
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo fetch
|
||||
# The version from the lock, not whatever else a restored cache holds.
|
||||
version=$(awk '/^name = "protoc-bin-vendored-linux-x86_64"$/{found=1; next} found && /^version = /{gsub(/"/,"",$3); print $3; exit}' Cargo.lock)
|
||||
test -n "$version" || { echo "protoc-bin-vendored-linux-x86_64 is not in Cargo.lock" >&2; exit 1; }
|
||||
protoc=$(find ~/.cargo/registry/src -path "*protoc-bin-vendored-linux-x86_64-$version/bin/protoc" | head -1)
|
||||
test -x "$protoc" || { echo "no vendored protoc $version in the registry" >&2; exit 1; }
|
||||
echo "PROTOC=$protoc" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Build the Rust maintenance worker
|
||||
run: |
|
||||
cd seaweed-worker
|
||||
cargo build --release -p weed-lance-worker --target ${{ matrix.target }}
|
||||
|
||||
- name: Package binary
|
||||
run: |
|
||||
cp seaweed-worker/target/${{ matrix.target }}/release/weed-worker weed-worker
|
||||
tar czf weed-worker_${{ matrix.asset_suffix }}.tar.gz weed-worker
|
||||
rm weed-worker
|
||||
md5sum weed-worker_${{ matrix.asset_suffix }}.tar.gz > weed-worker_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
|
||||
- name: Upload release assets
|
||||
if: startsWith(github.ref, 'refs/tags/')
|
||||
uses: softprops/action-gh-release@v3
|
||||
with:
|
||||
files: |
|
||||
weed-worker_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-worker_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
- name: Upload artifacts
|
||||
if: ${{ !startsWith(github.ref, 'refs/tags/') }}
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: rust-worker-${{ matrix.asset_suffix }}
|
||||
path: |
|
||||
weed-worker_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-worker_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
|
||||
build-rust-volume-darwin:
|
||||
permissions:
|
||||
@@ -222,7 +119,10 @@ jobs:
|
||||
asset_suffix: darwin_arm64
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: brew install protobuf
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
@@ -230,7 +130,7 @@ jobs:
|
||||
targets: ${{ matrix.target }}
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
@@ -245,40 +145,32 @@ jobs:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
run: |
|
||||
cd seaweed-volume
|
||||
cargo build --release --target ${{ matrix.target }} --target-dir target/large-disk
|
||||
cargo build --release --target ${{ matrix.target }}
|
||||
|
||||
- name: Build Rust volume server (normal)
|
||||
env:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
run: |
|
||||
cd seaweed-volume
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features --target-dir target/normal
|
||||
cargo build --release --target ${{ matrix.target }} --no-default-features
|
||||
|
||||
- name: Package binaries
|
||||
run: |
|
||||
cp seaweed-volume/target/large-disk/${{ matrix.target }}/release/weed-volume weed-volume-large-disk
|
||||
cp seaweed-volume/target/${{ matrix.target }}/release/weed-volume weed-volume-large-disk
|
||||
tar czf weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz weed-volume-large-disk
|
||||
rm weed-volume-large-disk
|
||||
|
||||
cp seaweed-volume/target/normal/${{ matrix.target }}/release/weed-volume weed-volume-normal
|
||||
cp seaweed-volume/target/${{ matrix.target }}/release/weed-volume weed-volume-normal
|
||||
tar czf weed-volume_${{ matrix.asset_suffix }}.tar.gz weed-volume-normal
|
||||
rm weed-volume-normal
|
||||
|
||||
- name: Generate md5 checksums
|
||||
run: |
|
||||
for f in weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz weed-volume_${{ matrix.asset_suffix }}.tar.gz; do
|
||||
md5 -r "$f" > "$f.md5"
|
||||
done
|
||||
|
||||
- name: Upload release assets
|
||||
if: startsWith(github.ref, 'refs/tags/')
|
||||
uses: softprops/action-gh-release@v3
|
||||
with:
|
||||
files: |
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
@@ -289,9 +181,7 @@ jobs:
|
||||
name: rust-volume-${{ matrix.asset_suffix }}
|
||||
path: |
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_large_disk_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz
|
||||
weed-volume_${{ matrix.asset_suffix }}.tar.gz.md5
|
||||
|
||||
build-rust-volume-windows:
|
||||
permissions:
|
||||
@@ -299,13 +189,16 @@ jobs:
|
||||
runs-on: windows-latest
|
||||
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- name: Install protobuf compiler
|
||||
run: choco install protoc -y
|
||||
|
||||
- name: Install Rust toolchain
|
||||
uses: dtolnay/rust-toolchain@stable
|
||||
|
||||
- name: Cache cargo registry and target
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: |
|
||||
~/.cargo/registry
|
||||
@@ -320,42 +213,33 @@ jobs:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
run: |
|
||||
cd seaweed-volume
|
||||
cargo build --release --target-dir target/large-disk
|
||||
cargo build --release
|
||||
|
||||
- name: Build Rust volume server (normal)
|
||||
env:
|
||||
SEAWEEDFS_COMMIT: ${{ github.sha }}
|
||||
run: |
|
||||
cd seaweed-volume
|
||||
cargo build --release --no-default-features --target-dir target/normal
|
||||
cargo build --release --no-default-features
|
||||
|
||||
- name: Package binaries
|
||||
shell: bash
|
||||
run: |
|
||||
cp seaweed-volume/target/large-disk/release/weed-volume.exe weed-volume-large-disk.exe
|
||||
cp seaweed-volume/target/release/weed-volume.exe weed-volume-large-disk.exe
|
||||
7z a weed-volume_large_disk_windows_amd64.zip weed-volume-large-disk.exe
|
||||
rm weed-volume-large-disk.exe
|
||||
|
||||
cp seaweed-volume/target/normal/release/weed-volume.exe weed-volume-normal.exe
|
||||
cp seaweed-volume/target/release/weed-volume.exe weed-volume-normal.exe
|
||||
7z a weed-volume_windows_amd64.zip weed-volume-normal.exe
|
||||
rm weed-volume-normal.exe
|
||||
|
||||
- name: Generate md5 checksums
|
||||
shell: bash
|
||||
run: |
|
||||
for f in weed-volume_large_disk_windows_amd64.zip weed-volume_windows_amd64.zip; do
|
||||
md5sum "$f" > "$f.md5"
|
||||
done
|
||||
|
||||
- name: Upload release assets
|
||||
if: startsWith(github.ref, 'refs/tags/')
|
||||
uses: softprops/action-gh-release@v3
|
||||
with:
|
||||
files: |
|
||||
weed-volume_large_disk_windows_amd64.zip
|
||||
weed-volume_large_disk_windows_amd64.zip.md5
|
||||
weed-volume_windows_amd64.zip
|
||||
weed-volume_windows_amd64.zip.md5
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
|
||||
@@ -366,6 +250,4 @@ jobs:
|
||||
name: rust-volume-windows_amd64
|
||||
path: |
|
||||
weed-volume_large_disk_windows_amd64.zip
|
||||
weed-volume_large_disk_windows_amd64.zip.md5
|
||||
weed-volume_windows_amd64.zip
|
||||
weed-volume_windows_amd64.zip.md5
|
||||
|
||||
@@ -34,10 +34,10 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -2,16 +2,7 @@ name: "S3 Authenticated Integration Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/iam/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'test/s3/normal/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-example-integration-tests.yml'
|
||||
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/s3-integration-tests
|
||||
cancel-in-progress: true
|
||||
@@ -27,10 +18,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -64,14 +55,6 @@ jobs:
|
||||
echo "=== Running S3 Empty Directory Marker Tests ==="
|
||||
go test -v -timeout=180s -run TestS3ListObjectsEmptyDirectoryMarkers ./...
|
||||
|
||||
- name: Run S3 Prefix Object Tests
|
||||
timeout-minutes: 15
|
||||
working-directory: test/s3/normal
|
||||
run: |
|
||||
set -x
|
||||
echo "=== Running S3 Prefix Object Tests ==="
|
||||
go test -v -timeout=180s -run TestS3PrefixObjectKeys ./...
|
||||
|
||||
- name: Run IAM Integration Tests
|
||||
timeout-minutes: 15
|
||||
working-directory: test/s3/normal
|
||||
|
||||
@@ -2,15 +2,7 @@ name: "S3 Filer Group Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'test/s3/filer_group/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-filer-group-tests.yml'
|
||||
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/s3-filer-group-tests
|
||||
cancel-in-progress: true
|
||||
@@ -30,10 +22,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -2,15 +2,7 @@ name: "S3 Go Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'test/s3/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-go-tests.yml'
|
||||
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/s3-go-tests
|
||||
cancel-in-progress: true
|
||||
@@ -33,10 +25,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -97,10 +89,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -145,10 +137,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -196,10 +188,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -253,77 +245,6 @@ jobs:
|
||||
path: test/s3/retention/weed-test*.log
|
||||
retention-days: 3
|
||||
|
||||
s3-lifecycle-tests:
|
||||
name: S3 Lifecycle Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 10
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
# One job per test so each gets a fresh `weed mini` server, avoiding
|
||||
# the cross-test volume-pool exhaustion that surfaced when several
|
||||
# TTL-pinned bucket collections piled up in a single run.
|
||||
test:
|
||||
- TestLifecycleAbortIncompleteMultipartUpload
|
||||
- TestLifecycleAdminDispatchSucceedsWithCustomFilerGrpcPort
|
||||
- TestLifecycleBootstrapWalkOnExistingObjects
|
||||
- TestLifecycleConfigUpdateBetweenSweeps
|
||||
- TestLifecycleDeleteBucketLifecycleStopsDispatching
|
||||
- TestLifecycleDisabledRuleSkipsObject
|
||||
- TestLifecycleEmptyBucketSweepIsNoOp
|
||||
- TestLifecycleExpirationDateInThePast
|
||||
- TestLifecycleExpirationFiresOnBackdatedObject
|
||||
- TestLifecycleExpiredDeleteMarkerCleanup
|
||||
- TestLifecycleMultipleBucketsInOneSweep
|
||||
- TestLifecycleMultipleRulesInOneBucket
|
||||
- TestLifecycleNewerNoncurrentVersions
|
||||
- TestLifecycleNoncurrentVersionExpiration
|
||||
- TestLifecycleSizeFilterGreaterThan
|
||||
- TestLifecycleSkipsObjectLockedObjects
|
||||
- TestLifecycleSuspendedVersioningExpiration
|
||||
- TestLifecycleTagFilter
|
||||
- TestLifecycleVersionedBucketCreatesDeleteMarker
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
go install -buildvcs=false
|
||||
|
||||
- name: Run ${{ matrix.test }}
|
||||
timeout-minutes: 8
|
||||
working-directory: test/s3/lifecycle
|
||||
run: |
|
||||
set -x
|
||||
make test-with-server TEST_PATTERN='^${{ matrix.test }}$$'
|
||||
|
||||
- name: Show server logs on failure
|
||||
if: failure()
|
||||
working-directory: test/s3/lifecycle
|
||||
run: |
|
||||
if [ -f weed-test.log ]; then
|
||||
echo "=== Last 200 lines of server logs ==="
|
||||
tail -200 weed-test.log
|
||||
fi
|
||||
ps aux | grep -E "(weed|test)" || true
|
||||
netstat -tlnp 2>/dev/null | grep -E "(8333|9333|8080|8888)" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: s3-lifecycle-test-logs-${{ matrix.test }}
|
||||
path: test/s3/lifecycle/weed-test*.log
|
||||
retention-days: 3
|
||||
|
||||
s3-checksum-tests:
|
||||
name: S3 Checksum Tests
|
||||
runs-on: ubuntu-22.04
|
||||
@@ -331,10 +252,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -389,10 +310,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -453,10 +374,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -502,10 +423,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -570,10 +491,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -625,10 +546,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -39,10 +39,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -88,10 +88,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -202,10 +202,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -262,10 +262,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -35,10 +35,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -26,10 +26,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
@@ -38,22 +38,7 @@ jobs:
|
||||
working-directory: test/s3/versioning
|
||||
run: |
|
||||
set -x
|
||||
# Run every versioning test, so a regression test lands covered instead
|
||||
# of waiting for someone to remember this file. Name a test in EXCLUDE,
|
||||
# with the reason, to keep it out.
|
||||
#
|
||||
# TestVersioningPagination*: opt-in stress tests that build 1500+
|
||||
# versions. They self-skip without ENABLE_STRESS_TESTS and have their
|
||||
# own make target, so this gate should not carry them.
|
||||
EXCLUDE='TestVersioningPagination.*'
|
||||
tests=$(go test . -list '.*' | grep '^Test' | sort -u)
|
||||
# An empty list would make -run match nothing and pass this job vacuously.
|
||||
[ -n "$tests" ] || { echo "listed no versioning tests"; exit 1; }
|
||||
selected=$(echo "$tests" | grep -vE "^($EXCLUDE)$")
|
||||
[ -n "$selected" ] || { echo "EXCLUDE matched every test"; exit 1; }
|
||||
echo "running $(echo "$selected" | wc -l) of $(echo "$tests" | wc -l) versioning tests"
|
||||
# make swallows a lone trailing $, taking the anchor with it, so escape it.
|
||||
make test-with-server TEST_PATTERN="^($(echo "$selected" | paste -sd'|' -))"'$$'
|
||||
make test-with-server TEST_PATTERN="TestVersioningCompleteMultipartUploadIsIdempotent|TestVersioningSelfCopyMetadataReplaceCreatesNewVersion|TestVersioningSelfCopyMetadataReplaceSuspendedKeepsNullVersion|TestSuspendedDeleteCreatesDeleteMarker"
|
||||
|
||||
- name: Show server logs on failure
|
||||
if: failure()
|
||||
@@ -79,10 +64,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
@@ -117,10 +102,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -36,16 +36,16 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
|
||||
- name: Set up Python ${{ matrix.python-version }}
|
||||
uses: actions/setup-python@v7
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: ${{ matrix.python-version }}
|
||||
cache: 'pip'
|
||||
@@ -143,12 +143,12 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
cache: true
|
||||
|
||||
- name: Run Go unit tests
|
||||
|
||||
@@ -43,10 +43,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -86,10 +86,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -195,10 +195,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -313,10 +313,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -400,10 +400,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -3,22 +3,8 @@ name: "S3 Proxy Signature Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/server/**'
|
||||
- 'test/s3/proxy_signature/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-proxy-signature-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/server/**'
|
||||
- 'test/s3/proxy_signature/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-proxy-signature-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/s3-proxy-signature-tests
|
||||
@@ -34,19 +20,14 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
@@ -90,10 +71,8 @@ jobs:
|
||||
echo "Waiting for SeaweedFS S3 gateway to be ready via proxy..."
|
||||
S3_READY=0
|
||||
for i in $(seq 1 30); do
|
||||
# Check logs first for the readiness line. weed mini's progress
|
||||
# board prints " S3 ready (Xs)"; older builds and the
|
||||
# standalone S3 binary log "S3 (gateway|service) ... ready".
|
||||
if docker compose logs seaweedfs 2>&1 | grep -qE "S3 (gateway|service).*(started|ready)|S3[[:space:]]+ready"; then
|
||||
# Check logs first for startup message (weed mini says "S3 service is ready")
|
||||
if docker compose logs seaweedfs 2>&1 | grep -qE "S3 (gateway|service).*(started|ready)"; then
|
||||
echo "SeaweedFS S3 gateway is ready"
|
||||
S3_READY=1
|
||||
break
|
||||
|
||||
@@ -1,110 +0,0 @@
|
||||
name: "S3 SDK V2 Route Disambiguation Tests"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'test/s3/sdk_v2_routing/**'
|
||||
- '.github/workflows/s3-sdk-v2-routing-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'test/s3/sdk_v2_routing/**'
|
||||
- '.github/workflows/s3-sdk-v2-routing-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/s3-sdk-v2-routing-tests
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
s3-sdk-v2-routing-tests:
|
||||
name: S3 SDK V2 Routing Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
cd weed && go install -buildvcs=false
|
||||
|
||||
- name: Start weed mini (S3 on :8333)
|
||||
# Pins the regression for issue #9559: AWS SDK V2 / Hadoop s3a
|
||||
# listing a bucket literally named "buckets" must get an XML
|
||||
# ListObjectsV2 response, not the JSON ListTableBuckets body
|
||||
# served by the S3 Tables REST endpoint on the same path.
|
||||
run: |
|
||||
mkdir -p /tmp/seaweedfs-sdk-v2-routing
|
||||
cat > /tmp/seaweedfs-sdk-v2-routing-s3.json <<'JSON'
|
||||
{
|
||||
"identities": [
|
||||
{
|
||||
"name": "admin",
|
||||
"credentials": [
|
||||
{"accessKey": "some_access_key1", "secretKey": "some_secret_key1"}
|
||||
],
|
||||
"actions": ["Admin", "Read", "Write"]
|
||||
}
|
||||
]
|
||||
}
|
||||
JSON
|
||||
AWS_ACCESS_KEY_ID=some_access_key1 \
|
||||
AWS_SECRET_ACCESS_KEY=some_secret_key1 \
|
||||
weed mini \
|
||||
-dir=/tmp/seaweedfs-sdk-v2-routing \
|
||||
-s3.port=8333 \
|
||||
-s3.config=/tmp/seaweedfs-sdk-v2-routing-s3.json \
|
||||
-ip=127.0.0.1 \
|
||||
> /tmp/weed-mini.log 2>&1 &
|
||||
echo $! > /tmp/weed-mini.pid
|
||||
|
||||
for i in $(seq 1 30); do
|
||||
if curl -s -o /dev/null -w "%{http_code}" http://127.0.0.1:8333/ | grep -qE "^(200|403)$"; then
|
||||
echo "weed mini is ready"
|
||||
exit 0
|
||||
fi
|
||||
sleep 1
|
||||
done
|
||||
echo "weed mini failed to start within 30s"
|
||||
tail -50 /tmp/weed-mini.log
|
||||
exit 1
|
||||
|
||||
- name: Run SDK V2 routing tests
|
||||
env:
|
||||
S3_ENDPOINT: http://127.0.0.1:8333
|
||||
AWS_ACCESS_KEY_ID: some_access_key1
|
||||
AWS_SECRET_ACCESS_KEY: some_secret_key1
|
||||
AWS_REGION: us-east-1
|
||||
run: go test -v -timeout=5m ./test/s3/sdk_v2_routing/...
|
||||
|
||||
- name: Stop weed mini
|
||||
if: always()
|
||||
run: |
|
||||
if [ -f /tmp/weed-mini.pid ]; then
|
||||
kill "$(cat /tmp/weed-mini.pid)" 2>/dev/null || true
|
||||
fi
|
||||
|
||||
- name: Show server log on failure
|
||||
if: failure()
|
||||
run: |
|
||||
echo "=== weed mini log (last 200 lines) ==="
|
||||
tail -n 200 /tmp/weed-mini.log 2>/dev/null || echo "no log available"
|
||||
|
||||
- name: Archive log
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: s3-sdk-v2-routing-server-log
|
||||
path: /tmp/weed-mini.log
|
||||
retention-days: 3
|
||||
@@ -1,106 +0,0 @@
|
||||
name: "Snowflake S3Compat API tests"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'weed/iam/**'
|
||||
- 'weed/command/**'
|
||||
- 'weed/storage/**'
|
||||
- 'weed/operation/**'
|
||||
- 'weed/wdclient/**'
|
||||
- 'weed/cluster/**'
|
||||
- 'weed/pb/**'
|
||||
- 'test/s3/snowflake/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-snowflake-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'weed/iam/**'
|
||||
- 'weed/command/**'
|
||||
- 'weed/storage/**'
|
||||
- 'weed/operation/**'
|
||||
- 'weed/wdclient/**'
|
||||
- 'weed/cluster/**'
|
||||
- 'weed/pb/**'
|
||||
- 'test/s3/snowflake/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-snowflake-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.event.pull_request.number || github.ref }}/s3-snowflake-tests
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
snowflake-s3compat-tests:
|
||||
name: Snowflake S3Compat API tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 30
|
||||
env:
|
||||
WORK_DIR: /tmp/seaweedfs-snowflake-tests
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Java
|
||||
uses: actions/setup-java@v6
|
||||
with:
|
||||
java-version: '17'
|
||||
distribution: 'temurin'
|
||||
cache: 'maven'
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
cd weed
|
||||
go install -buildvcs=false
|
||||
weed version
|
||||
|
||||
- name: Run Snowflake S3Compat API tests
|
||||
timeout-minutes: 20
|
||||
run: |
|
||||
# Starts weed server, creates the buckets/objects the suite needs,
|
||||
# clones the upstream suite, and runs mvn -Dtest=S3CompatApiTest.
|
||||
bash test/s3/snowflake/run.sh
|
||||
|
||||
- name: Show logs on failure
|
||||
if: failure()
|
||||
run: |
|
||||
echo "=== SeaweedFS Server Log ==="
|
||||
tail -200 "$WORK_DIR/weed.log" || echo "No server log"
|
||||
echo ""
|
||||
echo "=== Surefire results ==="
|
||||
cat "$WORK_DIR"/snowflake-s3compat-api-test-suite/s3compatapi/target/surefire-reports/*.txt 2>/dev/null || echo "No surefire reports"
|
||||
|
||||
- name: Upload test results
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: snowflake-s3compat-surefire-reports
|
||||
path: /tmp/seaweedfs-snowflake-tests/snowflake-s3compat-api-test-suite/s3compatapi/target/surefire-reports/
|
||||
retention-days: 14
|
||||
|
||||
- name: Cleanup
|
||||
if: always()
|
||||
run: |
|
||||
pkill -9 -f "weed server" || true
|
||||
rm -rf "$WORK_DIR" || true
|
||||
@@ -25,27 +25,23 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
go install -buildvcs=false ./weed
|
||||
|
||||
- name: Pre-pull Spark image
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull apache/spark:3.5.1
|
||||
run: docker pull apache/spark:3.5.8
|
||||
|
||||
- name: Run S3 Spark integration tests
|
||||
working-directory: test/s3/spark
|
||||
|
||||
@@ -44,10 +44,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -112,10 +112,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -160,10 +160,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -209,10 +209,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -258,10 +258,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -309,10 +309,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -357,10 +357,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -2,15 +2,6 @@ name: "S3 Tables Integration Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'weed/worker/tasks/iceberg/**'
|
||||
- 'test/s3tables/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3-tables-tests.yml'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
@@ -24,10 +15,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -84,19 +75,14 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
@@ -145,23 +131,19 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Pre-pull Trino image
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull trinodb/trino:479
|
||||
run: docker pull trinodb/trino:479
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
@@ -215,24 +197,22 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull dremio/dremio-oss:25.2.0
|
||||
pull python:3.11-slim
|
||||
- name: Pre-pull Dremio image
|
||||
run: docker pull dremio/dremio-oss:25.2.0
|
||||
|
||||
- name: Pre-pull Python image for PyIceberg writer
|
||||
run: docker pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
@@ -288,24 +268,22 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull apache/doris:doris-all-in-one-2.1.0
|
||||
pull python:3.11-slim
|
||||
- name: Pre-pull Doris image
|
||||
run: docker pull apache/doris:doris-all-in-one-2.1.0
|
||||
|
||||
- name: Pre-pull Python image for PyIceberg writer
|
||||
run: docker pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
@@ -354,202 +332,6 @@ jobs:
|
||||
path: test/s3tables/catalog_doris/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
clickhouse-iceberg-catalog-tests:
|
||||
name: ClickHouse Iceberg Catalog Integration Tests (${{ matrix.tag }})
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 30
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
# Pinned baseline, and latest so new ClickHouse releases are
|
||||
# exercised without a code change.
|
||||
- clickhouse-image: clickhouse/clickhouse-server:25.8
|
||||
tag: "25.8"
|
||||
- clickhouse-image: clickhouse/clickhouse-server:latest
|
||||
tag: latest
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull ${{ matrix.clickhouse-image }}
|
||||
pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
go install -buildvcs=false ./weed
|
||||
|
||||
- name: Run ClickHouse Iceberg Catalog Integration Tests
|
||||
timeout-minutes: 25
|
||||
working-directory: test/s3tables/catalog_clickhouse
|
||||
env:
|
||||
CLICKHOUSE_IMAGE: ${{ matrix.clickhouse-image }}
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
echo "=== System Information ==="
|
||||
uname -a
|
||||
free -h
|
||||
df -h
|
||||
docker info
|
||||
echo "=== Starting ClickHouse Iceberg Catalog Tests ==="
|
||||
|
||||
go test -v -timeout 20m . 2>&1 | tee test-output.log || {
|
||||
echo "ClickHouse Iceberg catalog integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/catalog_clickhouse
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker|clickhouse)" || true
|
||||
echo "=== ClickHouse containers ==="
|
||||
docker ps -a --filter "name=seaweed-clickhouse" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: clickhouse-iceberg-catalog-test-logs-${{ matrix.tag }}
|
||||
path: test/s3tables/catalog_clickhouse/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
olake-iceberg-catalog-tests:
|
||||
name: OLake Iceberg Catalog Integration Tests (${{ matrix.tag }})
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 30
|
||||
strategy:
|
||||
fail-fast: false
|
||||
matrix:
|
||||
include:
|
||||
# Pinned baseline, and latest so new OLake releases are exercised
|
||||
# without a code change. OLake's Iceberg writer is a Java sidecar
|
||||
# whose Iceberg version moves independently of the Go release, so
|
||||
# the latest leg is the one that catches library drift.
|
||||
- olake-image: olakego/source-postgres:v0.10.1
|
||||
tag: "v0.10.1"
|
||||
- olake-image: olakego/source-postgres:latest
|
||||
tag: latest
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull ${{ matrix.olake-image }}
|
||||
pull postgres:16
|
||||
pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
go install -buildvcs=false ./weed
|
||||
|
||||
- name: Run OLake Iceberg Catalog Integration Tests
|
||||
timeout-minutes: 25
|
||||
working-directory: test/s3tables/catalog_olake
|
||||
env:
|
||||
OLAKE_IMAGE: ${{ matrix.olake-image }}
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
echo "=== System Information ==="
|
||||
uname -a
|
||||
free -h
|
||||
df -h
|
||||
docker info
|
||||
echo "=== Starting OLake Iceberg Catalog Tests ==="
|
||||
|
||||
go test -v -timeout 20m . 2>&1 | tee test-output.log || {
|
||||
echo "OLake Iceberg catalog integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
# The suite skips itself when Docker is unavailable, so a green job is not
|
||||
# by itself evidence that anything ran. Assert execution explicitly.
|
||||
- name: Assert the suite actually ran
|
||||
working-directory: test/s3tables/catalog_olake
|
||||
run: |
|
||||
log=test-output.log
|
||||
if [ ! -f "$log" ]; then
|
||||
echo "::error::no test-output.log; the suite did not run"
|
||||
exit 1
|
||||
fi
|
||||
passes=$(grep -c '^--- PASS' "$log" || true)
|
||||
skips=$(grep -c '^--- SKIP' "$log" || true)
|
||||
echo "top-level PASS=$passes SKIP=$skips"
|
||||
if [ "$skips" -gt 0 ]; then
|
||||
echo "::error::the OLake suite skipped $skips top-level test(s); the environment it needs was not provisioned, so this job proves nothing"
|
||||
grep '^--- SKIP' "$log" | head -20
|
||||
exit 1
|
||||
fi
|
||||
if [ "$passes" -lt 1 ]; then
|
||||
echo "::error::the OLake suite recorded no passing top-level test"
|
||||
exit 1
|
||||
fi
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/catalog_olake
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker|olake|postgres)" || true
|
||||
echo "=== Containers ==="
|
||||
docker ps -a | head -30 || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: olake-iceberg-catalog-test-logs-${{ matrix.tag }}
|
||||
path: test/s3tables/catalog_olake/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
polaris-integration-tests:
|
||||
name: Polaris Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
@@ -557,10 +339,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -572,15 +354,8 @@ jobs:
|
||||
run: |
|
||||
go install -buildvcs=false ./weed
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull Polaris image
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull apache/polaris:latest
|
||||
run: docker pull apache/polaris:latest
|
||||
|
||||
- name: Run Polaris Integration Tests
|
||||
timeout-minutes: 25
|
||||
@@ -625,23 +400,19 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Pre-pull Spark image
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull apache/spark:3.5.1
|
||||
run: docker pull apache/spark:3.5.1
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
@@ -695,24 +466,21 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Pre-pull RisingWave image
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull risingwavelabs/risingwave:v2.5.0
|
||||
pull postgres:16-alpine
|
||||
docker pull risingwavelabs/risingwave:v2.5.0
|
||||
docker pull postgres:16-alpine
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
@@ -766,47 +534,19 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Week stamp for image cache key
|
||||
id: week
|
||||
run: echo "week=$(date -u +%G-%V)" >> "$GITHUB_OUTPUT"
|
||||
|
||||
- name: Restore python:3 image cache
|
||||
id: python-image
|
||||
uses: actions/cache@v6
|
||||
with:
|
||||
path: /tmp/python3-image.tar
|
||||
key: python3-image-${{ steps.week.outputs.week }}
|
||||
restore-keys: |
|
||||
python3-image-
|
||||
|
||||
- name: Load or pull python:3
|
||||
run: |
|
||||
if [ "${{ steps.python-image.outputs.cache-hit }}" = "true" ]; then
|
||||
docker load -i /tmp/python3-image.tar
|
||||
exit 0
|
||||
fi
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
if pull python:3; then
|
||||
docker save -o /tmp/python3-image.tar python:3
|
||||
elif [ -f /tmp/python3-image.tar ]; then
|
||||
# Docker Hub unreachable; fall back to last week's cached image
|
||||
docker load -i /tmp/python3-image.tar
|
||||
else
|
||||
exit 1
|
||||
fi
|
||||
- name: Pre-pull Python image
|
||||
run: docker pull python:3
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
@@ -860,14 +600,23 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Docker
|
||||
uses: docker/setup-buildx-action@v4
|
||||
|
||||
- name: Pre-pull Python image
|
||||
run: docker pull python:3
|
||||
|
||||
- name: Pre-pull LocalStack image (if needed)
|
||||
run: docker pull localstack/localstack:latest || true
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
@@ -913,366 +662,6 @@ jobs:
|
||||
path: test/s3tables/lakekeeper/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
unity-catalog-integration-tests:
|
||||
name: Unity Catalog Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 30
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull unitycatalog/unitycatalog:v0.4.0
|
||||
pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Install SeaweedFS
|
||||
run: |
|
||||
go install -buildvcs=false ./weed
|
||||
|
||||
- name: Run Unity Catalog Integration Tests
|
||||
timeout-minutes: 25
|
||||
working-directory: test/s3tables/unity_catalog
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
echo "=== System Information ==="
|
||||
uname -a
|
||||
free -h
|
||||
df -h
|
||||
docker info
|
||||
echo "=== Starting Unity Catalog Tests ==="
|
||||
|
||||
go test -v -timeout 20m . 2>&1 | tee test-output.log || {
|
||||
echo "Unity Catalog integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/unity_catalog
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker|unitycatalog)" || true
|
||||
echo "=== Unity Catalog containers ==="
|
||||
docker ps -a --filter "name=seaweed-unity-catalog" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: unity-catalog-integration-test-logs
|
||||
path: test/s3tables/unity_catalog/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
lancedb-namespace-tests:
|
||||
name: LanceDB Namespace Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 30
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
cd weed && go build -buildvcs=false .
|
||||
|
||||
- name: Run LanceDB Namespace Integration Tests
|
||||
timeout-minutes: 25
|
||||
working-directory: test/s3tables/catalog_lancedb
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
echo "=== System Information ==="
|
||||
uname -a
|
||||
free -h
|
||||
df -h
|
||||
docker info
|
||||
echo "=== Starting LanceDB Namespace Tests ==="
|
||||
|
||||
go test -v -timeout 20m . 2>&1 | tee test-output.log || {
|
||||
echo "LanceDB namespace integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/catalog_lancedb
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker)" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: lancedb-namespace-test-logs
|
||||
path: test/s3tables/catalog_lancedb/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
table-lifecycle-tests:
|
||||
name: Table Lifecycle Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 40
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull python:3.11-slim
|
||||
pull duckdb/duckdb:latest
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
cd weed && go build -buildvcs=false .
|
||||
|
||||
- name: Run Table Lifecycle Integration Tests
|
||||
timeout-minutes: 35
|
||||
working-directory: test/s3tables/lifecycle
|
||||
env:
|
||||
# The Rust worker's own tests cover its handlers; a cold build of the
|
||||
# lance crate costs more here than the layer it would be checking.
|
||||
WEED_LANCE_MAINTENANCE: library
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
go test -v -timeout 30m . 2>&1 | tee test-output.log || {
|
||||
echo "Table lifecycle integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/lifecycle
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker)" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: table-lifecycle-test-logs
|
||||
path: test/s3tables/lifecycle/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
duckdb-lance-tests:
|
||||
name: DuckDB Lance Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 30
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
# The job uploads a test log on failure; nothing here needs to push,
|
||||
# so do not leave a token in the checkout for it to pick up.
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull duckdb/duckdb:latest
|
||||
pull python:3.11-slim
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
cd weed && go build -buildvcs=false .
|
||||
|
||||
- name: Run DuckDB Lance Integration Tests
|
||||
timeout-minutes: 25
|
||||
working-directory: test/s3tables/catalog_duckdb_lance
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
echo "=== System Information ==="
|
||||
uname -a
|
||||
free -h
|
||||
df -h
|
||||
docker info
|
||||
echo "=== Starting DuckDB Lance Tests ==="
|
||||
|
||||
go test -v -timeout 20m . 2>&1 | tee test-output.log || {
|
||||
echo "DuckDB Lance integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/catalog_duckdb_lance
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker|duckdb)" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: duckdb-lance-test-logs
|
||||
path: test/s3tables/catalog_duckdb_lance/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
spark-lance-namespace-tests:
|
||||
name: Spark Lance Namespace Integration Tests
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 40
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
# The job uploads a test log on failure; nothing here needs to push,
|
||||
# so do not leave a token in the checkout for it to pick up.
|
||||
persist-credentials: false
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Configure Docker Hub mirror
|
||||
run: |
|
||||
echo '{"registry-mirrors": ["https://mirror.gcr.io"]}' | sudo tee /etc/docker/daemon.json
|
||||
sudo systemctl restart docker
|
||||
|
||||
- name: Pre-pull images
|
||||
run: |
|
||||
pull() { for i in 1 2 3; do docker pull "$1" && return 0; sleep 15; done; return 1; }
|
||||
pull apache/spark:3.5.1
|
||||
|
||||
- name: Run go mod tidy
|
||||
run: go mod tidy
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
cd weed && go build -buildvcs=false .
|
||||
|
||||
- name: Run Spark Lance Namespace Integration Tests
|
||||
timeout-minutes: 35
|
||||
working-directory: test/s3tables/catalog_spark_lance
|
||||
run: |
|
||||
set -x
|
||||
set -o pipefail
|
||||
echo "=== System Information ==="
|
||||
uname -a
|
||||
free -h
|
||||
df -h
|
||||
docker info
|
||||
echo "=== Starting Spark Lance Namespace Tests ==="
|
||||
|
||||
go test -v -timeout 30m . 2>&1 | tee test-output.log || {
|
||||
echo "Spark Lance namespace integration tests failed"
|
||||
exit 1
|
||||
}
|
||||
|
||||
- name: Show test output on failure
|
||||
if: failure()
|
||||
working-directory: test/s3tables/catalog_spark_lance
|
||||
run: |
|
||||
echo "=== Test Output ==="
|
||||
if [ -f test-output.log ]; then
|
||||
tail -200 test-output.log
|
||||
fi
|
||||
|
||||
echo "=== Process information ==="
|
||||
ps aux | grep -E "(weed|test|docker|spark)" || true
|
||||
|
||||
- name: Upload test logs on failure
|
||||
if: failure()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: spark-lance-namespace-test-logs
|
||||
path: test/s3tables/catalog_spark_lance/test-output.log
|
||||
retention-days: 3
|
||||
|
||||
s3-tables-build-verification:
|
||||
name: S3 Tables Build Verification
|
||||
runs-on: ubuntu-22.04
|
||||
@@ -1280,10 +669,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -1345,10 +734,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -1396,10 +785,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
+29
-128
@@ -3,26 +3,8 @@ name: "Ceph S3 tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'weed/iam/**'
|
||||
- 'test/s3/compatibility/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/server/**'
|
||||
- 'weed/iam/**'
|
||||
- 'test/s3/compatibility/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/s3tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref }}/s3tests
|
||||
@@ -38,16 +20,16 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: '3.9'
|
||||
|
||||
@@ -63,7 +45,7 @@ jobs:
|
||||
|
||||
- name: Fix S3 tests bucket creation conflicts
|
||||
run: |
|
||||
python3 test/s3/compatibility/fix_s3_tests_bucket_conflicts.py
|
||||
python3 test/s3/fix_s3_tests_bucket_conflicts.py
|
||||
env:
|
||||
S3_TESTS_PATH: s3-tests
|
||||
|
||||
@@ -128,9 +110,6 @@ jobs:
|
||||
echo "All SeaweedFS components are ready!"
|
||||
cd ../s3-tests
|
||||
sed -i "s/assert prefixes == \['foo%2B1\/', 'foo\/', 'quux%20ab\/'\]/assert prefixes == \['foo\/', 'foo%2B1\/', 'quux%20ab\/'\]/" s3tests/functional/test_s3.py
|
||||
# The suite expects RGW's 400 InvalidPart for a partNumber past the last
|
||||
# part; AWS answers 416 InvalidPartNumber, which is what we return.
|
||||
sed -i "/# request PartNumber out of range/,+4{s/assert status == 400/assert status == 416/; s/assert error_code == 'InvalidPart'/assert error_code == 'InvalidPartNumber'/}" s3tests/functional/test_s3.py
|
||||
|
||||
# Debug: Show the config file contents
|
||||
echo "=== S3 Config File Contents ==="
|
||||
@@ -153,49 +132,7 @@ jobs:
|
||||
done
|
||||
|
||||
echo "✅ S3 server is responding, starting tests..."
|
||||
|
||||
# Spawn the lifecycle worker so test_lifecycle_expiration etc. have
|
||||
# something driving deletions. The s3tests build tag rescales one
|
||||
# day to LifeCycleInterval=10s, so a 1d rule fires within ~10s of
|
||||
# the upload's mtime; -dispatch / -checkpoint defaults are already
|
||||
# tightened under the same build tag.
|
||||
LC_LOG=/tmp/lifecycle-worker.log
|
||||
# -debug routes glog to stderr so the bootstrap walker's progress
|
||||
# shows up in $LC_LOG; without it weed shell silences glog.
|
||||
(echo "s3.lifecycle.run-shard -shards 0-15 -s3 localhost:18000 -events 0 -runtime 1800s -refresh 2s" && echo exit) \
|
||||
| weed shell -debug -master=localhost:9333 \
|
||||
> "$LC_LOG" 2>&1 &
|
||||
lc_pid=$!
|
||||
# Aliveness check: a bad shell command exits in <1s and the suite
|
||||
# would otherwise just timeout the expiration tests with no signal.
|
||||
sleep 2
|
||||
if ! kill -0 "$lc_pid" 2>/dev/null; then
|
||||
echo "lifecycle worker died on startup"
|
||||
tail -50 "$LC_LOG" 2>/dev/null || true
|
||||
exit 1
|
||||
fi
|
||||
echo "lifecycle worker pid=$lc_pid"
|
||||
|
||||
# bash -e exits the step on the first tox failure, so move teardown
|
||||
# into a trap to guarantee the worker log + data dir reach the runner.
|
||||
cleanup() {
|
||||
status=$?
|
||||
# SIGTERM first so the worker's stdout flushes; SIGKILL is the
|
||||
# bash fallback if it ignores TERM. Reading the log AFTER the
|
||||
# graceful-stop window catches the bootstrap walker's progress.
|
||||
kill -TERM "$lc_pid" 2>/dev/null || true
|
||||
kill -TERM "$pid" 2>/dev/null || true
|
||||
sleep 1
|
||||
if [ "$status" -ne 0 ]; then
|
||||
echo "=== lifecycle worker log (tail) ==="
|
||||
tail -200 "$LC_LOG" 2>/dev/null || true
|
||||
fi
|
||||
kill -9 "$lc_pid" 2>/dev/null || true
|
||||
kill -9 "$pid" 2>/dev/null || true
|
||||
rm -rf "$WEED_DATA_DIR" 2>/dev/null || true
|
||||
}
|
||||
trap cleanup EXIT
|
||||
|
||||
|
||||
tox -- \
|
||||
s3tests/functional/test_s3.py::test_bucket_list_empty \
|
||||
s3tests/functional/test_s3.py::test_bucket_list_distinct \
|
||||
@@ -289,7 +226,6 @@ jobs:
|
||||
s3tests/functional/test_s3.py::test_object_write_check_etag \
|
||||
s3tests/functional/test_s3.py::test_object_write_cache_control \
|
||||
s3tests/functional/test_s3.py::test_object_write_expires \
|
||||
s3tests/functional/test_s3.py::test_object_content_encoding_aws_chunked \
|
||||
s3tests/functional/test_s3.py::test_object_write_read_update_read_delete \
|
||||
s3tests/functional/test_s3.py::test_object_metadata_replaced_on_put \
|
||||
s3tests/functional/test_s3.py::test_object_write_file \
|
||||
@@ -312,7 +248,6 @@ jobs:
|
||||
s3tests/functional/test_s3.py::test_get_object_ifmodifiedsince_good \
|
||||
s3tests/functional/test_s3.py::test_get_object_ifmodifiedsince_failed \
|
||||
s3tests/functional/test_s3.py::test_get_object_ifunmodifiedsince_failed \
|
||||
s3tests/functional/test_s3.py::test_get_checksum_object_attributes \
|
||||
s3tests/functional/test_s3.py::test_bucket_head \
|
||||
s3tests/functional/test_s3.py::test_bucket_head_notexist \
|
||||
s3tests/functional/test_s3.py::test_object_raw_authenticated \
|
||||
@@ -377,8 +312,11 @@ jobs:
|
||||
s3tests/functional/test_s3.py::test_lifecycle_get \
|
||||
s3tests/functional/test_s3.py::test_lifecycle_set_filter \
|
||||
s3tests/functional/test_s3.py::test_lifecycle_expiration \
|
||||
s3tests/functional/test_s3.py::test_lifecyclev2_expiration
|
||||
# cleanup() trap handles worker/server kill + data dir wipe.
|
||||
s3tests/functional/test_s3.py::test_lifecyclev2_expiration \
|
||||
s3tests/functional/test_s3.py::test_lifecycle_expiration_versioning_enabled
|
||||
kill -9 $pid || true
|
||||
# Clean up data directory
|
||||
rm -rf "$WEED_DATA_DIR" || true
|
||||
|
||||
versioning-tests:
|
||||
name: S3 Versioning & Object Lock tests
|
||||
@@ -386,16 +324,16 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: '3.9'
|
||||
|
||||
@@ -411,7 +349,7 @@ jobs:
|
||||
|
||||
- name: Fix S3 tests bucket creation conflicts
|
||||
run: |
|
||||
python3 test/s3/compatibility/fix_s3_tests_bucket_conflicts.py
|
||||
python3 test/s3/fix_s3_tests_bucket_conflicts.py
|
||||
env:
|
||||
S3_TESTS_PATH: s3-tests
|
||||
|
||||
@@ -556,16 +494,16 @@ jobs:
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: '3.9'
|
||||
|
||||
@@ -681,10 +619,10 @@ jobs:
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
@@ -699,12 +637,10 @@ jobs:
|
||||
export WEED_DATA_DIR="/tmp/seaweedfs-copy-test-$(date +%s)"
|
||||
mkdir -p "$WEED_DATA_DIR"
|
||||
set -x
|
||||
# Each test bucket is its own collection and grows 7 volumes; the suite runs
|
||||
# faster than the heartbeat that returns slots from the deleted collections.
|
||||
weed -v 0 server -filer -filer.maxMB=64 -s3 -ip.bind 0.0.0.0 \
|
||||
-dir="$WEED_DATA_DIR" \
|
||||
-master.raftHashicorp -master.electionTimeout 1s -master.volumeSizeLimitMB=100 \
|
||||
-volume.max=300 -volume.preStopSeconds=1 \
|
||||
-volume.max=100 -volume.preStopSeconds=1 \
|
||||
-master.port=9336 -volume.port=8083 -filer.port=8891 -s3.port=8003 -metricsPort=9327 \
|
||||
-s3.allowDeleteBucketNotEmpty=true -s3.config="$GITHUB_WORKSPACE/docker/compose/s3.json" -master.peers=none &
|
||||
pid=$!
|
||||
@@ -772,7 +708,7 @@ jobs:
|
||||
sleep 2
|
||||
done
|
||||
|
||||
MASTER_ENDPOINT="http://127.0.0.1:9336" go test -v
|
||||
go test -v
|
||||
kill -9 $pid || true
|
||||
# Clean up data directory
|
||||
rm -rf "$WEED_DATA_DIR" || true
|
||||
@@ -783,16 +719,16 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
uses: actions/setup-python@v6
|
||||
with:
|
||||
python-version: '3.9'
|
||||
|
||||
@@ -973,9 +909,6 @@ jobs:
|
||||
echo "All SeaweedFS components are ready!"
|
||||
cd ../s3-tests
|
||||
sed -i "s/assert prefixes == \['foo%2B1\/', 'foo\/', 'quux%20ab\/'\]/assert prefixes == \['foo\/', 'foo%2B1\/', 'quux%20ab\/'\]/" s3tests/functional/test_s3.py
|
||||
# The suite expects RGW's 400 InvalidPart for a partNumber past the last
|
||||
# part; AWS answers 416 InvalidPartNumber, which is what we return.
|
||||
sed -i "/# request PartNumber out of range/,+4{s/assert status == 400/assert status == 416/; s/assert error_code == 'InvalidPart'/assert error_code == 'InvalidPartNumber'/}" s3tests/functional/test_s3.py
|
||||
# Create and update s3tests.conf to use port 8004
|
||||
cp ../docker/compose/s3tests.conf ../docker/compose/s3tests-sql.conf
|
||||
sed -i 's/port = 8000/port = 8004/g' ../docker/compose/s3tests-sql.conf
|
||||
@@ -1025,39 +958,6 @@ jobs:
|
||||
|
||||
sleep 2
|
||||
done
|
||||
|
||||
# Spawn the lifecycle worker (see basic-tests block for context).
|
||||
LC_LOG=/tmp/lifecycle-worker-sql.log
|
||||
(echo "s3.lifecycle.run-shard -shards 0-15 -s3 localhost:18004 -events 0 -runtime 1800s -refresh 2s" && echo exit) \
|
||||
| weed shell -debug -master=localhost:9337 \
|
||||
> "$LC_LOG" 2>&1 &
|
||||
lc_pid=$!
|
||||
sleep 2
|
||||
if ! kill -0 "$lc_pid" 2>/dev/null; then
|
||||
echo "lifecycle worker died on startup"
|
||||
tail -50 "$LC_LOG" 2>/dev/null || true
|
||||
exit 1
|
||||
fi
|
||||
echo "lifecycle worker pid=$lc_pid"
|
||||
|
||||
cleanup() {
|
||||
status=$?
|
||||
# SIGTERM first so the worker's stdout flushes; SIGKILL is the
|
||||
# bash fallback if it ignores TERM. Reading the log AFTER the
|
||||
# graceful-stop window catches the bootstrap walker's progress.
|
||||
kill -TERM "$lc_pid" 2>/dev/null || true
|
||||
kill -TERM "$pid" 2>/dev/null || true
|
||||
sleep 1
|
||||
if [ "$status" -ne 0 ]; then
|
||||
echo "=== lifecycle worker log (tail) ==="
|
||||
tail -200 "$LC_LOG" 2>/dev/null || true
|
||||
fi
|
||||
kill -9 "$lc_pid" 2>/dev/null || true
|
||||
kill -9 "$pid" 2>/dev/null || true
|
||||
rm -rf "$WEED_DATA_DIR" 2>/dev/null || true
|
||||
}
|
||||
trap cleanup EXIT
|
||||
|
||||
tox -- \
|
||||
s3tests/functional/test_s3.py::test_bucket_list_empty \
|
||||
s3tests/functional/test_s3.py::test_bucket_list_distinct \
|
||||
@@ -1151,7 +1051,6 @@ jobs:
|
||||
s3tests/functional/test_s3.py::test_object_write_check_etag \
|
||||
s3tests/functional/test_s3.py::test_object_write_cache_control \
|
||||
s3tests/functional/test_s3.py::test_object_write_expires \
|
||||
s3tests/functional/test_s3.py::test_object_content_encoding_aws_chunked \
|
||||
s3tests/functional/test_s3.py::test_object_write_read_update_read_delete \
|
||||
s3tests/functional/test_s3.py::test_object_metadata_replaced_on_put \
|
||||
s3tests/functional/test_s3.py::test_object_write_file \
|
||||
@@ -1174,7 +1073,6 @@ jobs:
|
||||
s3tests/functional/test_s3.py::test_get_object_ifmodifiedsince_good \
|
||||
s3tests/functional/test_s3.py::test_get_object_ifmodifiedsince_failed \
|
||||
s3tests/functional/test_s3.py::test_get_object_ifunmodifiedsince_failed \
|
||||
s3tests/functional/test_s3.py::test_get_checksum_object_attributes \
|
||||
s3tests/functional/test_s3.py::test_bucket_head \
|
||||
s3tests/functional/test_s3.py::test_bucket_head_notexist \
|
||||
s3tests/functional/test_s3.py::test_object_raw_authenticated \
|
||||
@@ -1239,7 +1137,10 @@ jobs:
|
||||
s3tests/functional/test_s3.py::test_lifecycle_get \
|
||||
s3tests/functional/test_s3.py::test_lifecycle_set_filter \
|
||||
s3tests/functional/test_s3.py::test_lifecycle_expiration \
|
||||
s3tests/functional/test_s3.py::test_lifecyclev2_expiration
|
||||
# cleanup() trap handles worker/server kill + data dir wipe.
|
||||
s3tests/functional/test_s3.py::test_lifecyclev2_expiration \
|
||||
s3tests/functional/test_s3.py::test_lifecycle_expiration_versioning_enabled
|
||||
kill -9 $pid || true
|
||||
# Clean up data directory
|
||||
rm -rf "$WEED_DATA_DIR" || true
|
||||
|
||||
|
||||
|
||||
@@ -1,120 +0,0 @@
|
||||
name: "Samba on FUSE Integration"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/cluster/**'
|
||||
- 'test/samba/**'
|
||||
- '.github/workflows/samba-integration.yml'
|
||||
pull_request:
|
||||
branches: [ master, main ]
|
||||
paths:
|
||||
- 'weed/mount/**'
|
||||
- 'weed/filer/**'
|
||||
- 'weed/cluster/**'
|
||||
- 'test/samba/**'
|
||||
- '.github/workflows/samba-integration.yml'
|
||||
workflow_dispatch:
|
||||
|
||||
concurrency:
|
||||
group: samba-integration/${{ github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
samba-integration:
|
||||
name: samba-integration
|
||||
runs-on: ubuntu-22.04
|
||||
timeout-minutes: 45
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
- name: Start local Docker registry
|
||||
run: docker run -d --restart=always -p 5000:5000 --name registry registry:2
|
||||
|
||||
- name: Set up Docker Buildx
|
||||
uses: docker/setup-buildx-action@v4
|
||||
with:
|
||||
driver-opts: network=host
|
||||
|
||||
- name: Build weed race binary
|
||||
run: |
|
||||
cd docker
|
||||
make binary_race
|
||||
|
||||
- name: Build SeaweedFS e2e image
|
||||
uses: docker/build-push-action@v7
|
||||
with:
|
||||
context: docker
|
||||
file: docker/Dockerfile.e2e
|
||||
tags: localhost:5000/chrislusf/seaweedfs:e2e
|
||||
push: true
|
||||
cache-from: type=gha,scope=samba-e2e
|
||||
cache-to: type=gha,mode=max,scope=samba-e2e
|
||||
|
||||
- name: Tag e2e image for docker compose
|
||||
run: |
|
||||
docker pull localhost:5000/chrislusf/seaweedfs:e2e
|
||||
docker tag localhost:5000/chrislusf/seaweedfs:e2e chrislusf/seaweedfs:e2e
|
||||
|
||||
- name: Build samba image
|
||||
uses: docker/build-push-action@v7
|
||||
with:
|
||||
context: test/samba
|
||||
build-contexts: |
|
||||
chrislusf/seaweedfs:e2e=docker-image://localhost:5000/chrislusf/seaweedfs:e2e
|
||||
tags: localhost:5000/chrislusf/seaweedfs:samba
|
||||
push: true
|
||||
cache-from: type=gha,scope=samba-harness
|
||||
cache-to: type=gha,mode=max,scope=samba-harness
|
||||
|
||||
- name: Tag samba image for docker compose
|
||||
run: |
|
||||
docker pull localhost:5000/chrislusf/seaweedfs:samba
|
||||
docker tag localhost:5000/chrislusf/seaweedfs:samba chrislusf/seaweedfs:samba
|
||||
|
||||
- name: Start SeaweedFS cluster and Samba
|
||||
run: |
|
||||
docker compose -f test/samba/docker-compose.yml up --wait
|
||||
|
||||
- name: Run Samba test battery
|
||||
run: |
|
||||
set -o pipefail
|
||||
docker compose -f test/samba/docker-compose.yml exec -T samba \
|
||||
/run_inside_container.sh 2>&1 | tee /tmp/samba-output.log
|
||||
|
||||
- name: Collect logs
|
||||
if: always()
|
||||
run: |
|
||||
mkdir -p /tmp/samba-docker-logs
|
||||
for svc in master volume filer samba; do
|
||||
docker compose -f test/samba/docker-compose.yml logs "$svc" \
|
||||
> "/tmp/samba-docker-logs/${svc}.log" 2>&1 || true
|
||||
done
|
||||
|
||||
- name: Tear down
|
||||
if: always()
|
||||
run: |
|
||||
docker compose -f test/samba/docker-compose.yml down -v
|
||||
|
||||
- name: Upload logs
|
||||
if: always()
|
||||
uses: actions/upload-artifact@v7
|
||||
with:
|
||||
name: samba-integration-results
|
||||
path: |
|
||||
/tmp/samba-output.log
|
||||
/tmp/samba-docker-logs/
|
||||
retention-days: 7
|
||||
@@ -34,10 +34,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -31,17 +31,17 @@ jobs:
|
||||
# SETUP & BUILD
|
||||
# ========================================
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up JDK 11
|
||||
uses: actions/setup-java@v6
|
||||
uses: actions/setup-java@v5
|
||||
with:
|
||||
java-version: '11'
|
||||
distribution: 'temurin'
|
||||
cache: maven
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
@@ -150,7 +150,7 @@ jobs:
|
||||
- name: Cache Apache Spark
|
||||
if: false && (github.event_name == 'push' || github.event_name == 'workflow_dispatch')
|
||||
id: cache-spark
|
||||
uses: actions/cache@v6
|
||||
uses: actions/cache@v5
|
||||
with:
|
||||
path: spark-3.5.0-bin-hadoop3
|
||||
key: spark-3.5.0-hadoop3
|
||||
|
||||
@@ -1,74 +0,0 @@
|
||||
---
|
||||
name: Star History
|
||||
|
||||
on:
|
||||
schedule:
|
||||
- cron: "0 0 * * *" # daily, 00:00 UTC
|
||||
workflow_dispatch:
|
||||
|
||||
permissions:
|
||||
contents: write
|
||||
|
||||
concurrency:
|
||||
# Only one chart regeneration per branch at a time; a newer run on the same
|
||||
# branch cancels an in-flight one so overlapping runs never conflict on
|
||||
# note/star_history.svg during rebase. Scoped by ref so a manual run on
|
||||
# another branch can't cancel the daily master update.
|
||||
group: star-history-${{ github.ref }}
|
||||
cancel-in-progress: true
|
||||
|
||||
jobs:
|
||||
render:
|
||||
name: Regenerate star history chart
|
||||
runs-on: ubuntu-latest
|
||||
|
||||
steps:
|
||||
- name: Checkout
|
||||
uses: actions/checkout@v7
|
||||
with:
|
||||
# Full history so the chart commit can rebase onto a moved master.
|
||||
fetch-depth: 0
|
||||
|
||||
- name: Set up Python
|
||||
uses: actions/setup-python@v7
|
||||
with:
|
||||
python-version: "3.x"
|
||||
cache: pip
|
||||
cache-dependency-path: .github/scripts/star_history.py
|
||||
|
||||
- name: Install matplotlib
|
||||
run: pip install matplotlib
|
||||
|
||||
- name: Render chart
|
||||
env:
|
||||
GITHUB_TOKEN: ${{ secrets.GITHUB_TOKEN }}
|
||||
run: python .github/scripts/star_history.py
|
||||
|
||||
- name: Commit if changed
|
||||
run: |
|
||||
git config user.name "github-actions[bot]"
|
||||
git config user.email "41898282+github-actions[bot]@users.noreply.github.com"
|
||||
if git diff --quiet -- note/star_history.svg; then
|
||||
echo "No changes to the chart."
|
||||
exit 0
|
||||
fi
|
||||
git add note/star_history.svg
|
||||
git commit -m "docs: regenerate star history chart"
|
||||
# Rebase and retry so a concurrent push to master doesn't lose the chart.
|
||||
for attempt in 1 2 3 4 5; do
|
||||
if [ "$attempt" -gt 1 ]; then
|
||||
# Guard the rebase: a transient fetch error or conflict must not
|
||||
# abort the fail-fast shell before the remaining attempts run.
|
||||
if ! git pull --rebase origin "$GITHUB_REF_NAME"; then
|
||||
echo "rebase failed (attempt ${attempt}); aborting and retrying"
|
||||
git rebase --abort || true
|
||||
continue
|
||||
fi
|
||||
fi
|
||||
if git push origin HEAD:"$GITHUB_REF_NAME"; then
|
||||
exit 0
|
||||
fi
|
||||
echo "push rejected (attempt ${attempt}); will rebase and retry"
|
||||
done
|
||||
echo "::error::could not push star history chart after retries"
|
||||
exit 1
|
||||
@@ -24,10 +24,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
|
||||
@@ -1,80 +0,0 @@
|
||||
name: "terraform: validate and test modules"
|
||||
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths: ['terraform/**', '.github/workflows/terraform_ci.yml']
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths: ['terraform/**', '.github/workflows/terraform_ci.yml']
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
|
||||
jobs:
|
||||
validate:
|
||||
name: fmt, validate, plan-level tests
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
|
||||
- name: Set up OpenTofu
|
||||
uses: opentofu/setup-opentofu@v2
|
||||
with:
|
||||
tofu_version: 1.12.1
|
||||
|
||||
- name: fmt check
|
||||
working-directory: terraform
|
||||
run: tofu fmt -recursive -check -diff
|
||||
|
||||
- name: validate core
|
||||
working-directory: terraform/modules/core
|
||||
run: |
|
||||
tofu init -backend=false -input=false
|
||||
tofu validate
|
||||
|
||||
- name: validate security
|
||||
working-directory: terraform/modules/security
|
||||
run: |
|
||||
tofu init -backend=false -input=false
|
||||
tofu validate
|
||||
|
||||
- name: plan-level tests (core)
|
||||
working-directory: terraform/modules/core
|
||||
run: tofu test
|
||||
|
||||
- name: validate examples
|
||||
run: |
|
||||
set -e
|
||||
for ex in terraform/examples/*/; do
|
||||
echo "== validate $ex =="
|
||||
tofu -chdir="$ex" init -backend=false -input=false
|
||||
tofu -chdir="$ex" validate
|
||||
done
|
||||
|
||||
smoke:
|
||||
name: local cluster smoke test (real weed)
|
||||
runs-on: ubuntu-latest
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
with:
|
||||
go-version-file: go.mod
|
||||
|
||||
- name: Build weed
|
||||
run: go build -o "$RUNNER_TEMP/weed" ./weed
|
||||
|
||||
- name: Set up OpenTofu
|
||||
uses: opentofu/setup-opentofu@v2
|
||||
with:
|
||||
tofu_version: 1.12.1
|
||||
|
||||
- name: Run local cluster harness
|
||||
working-directory: terraform/test/local
|
||||
run: WEED="$RUNNER_TEMP/weed" ./run_local_cluster.sh
|
||||
|
||||
- name: Run local mTLS cluster harness
|
||||
working-directory: terraform/test/local-secure
|
||||
run: WEED="$RUNNER_TEMP/weed" ./run_local_secure.sh
|
||||
@@ -3,20 +3,8 @@ name: "test s3 over https using aws-cli"
|
||||
on:
|
||||
push:
|
||||
branches: [master, test-https-s3-awscli]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/server/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/test-s3-over-https-using-awscli.yml'
|
||||
pull_request:
|
||||
branches: [master, test-https-s3-awscli]
|
||||
paths:
|
||||
- 'weed/s3api/**'
|
||||
- 'weed/server/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/test-s3-over-https-using-awscli.yml'
|
||||
|
||||
env:
|
||||
AWS_ACCESS_KEY_ID: some_access_key1
|
||||
@@ -32,11 +20,11 @@ jobs:
|
||||
runs-on: ubuntu-latest
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- uses: actions/checkout@v7
|
||||
- uses: actions/checkout@v6
|
||||
|
||||
- uses: actions/setup-go@v7
|
||||
- uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
|
||||
- name: Build SeaweedFS
|
||||
run: |
|
||||
|
||||
@@ -3,20 +3,8 @@ name: "TLS Rotation Integration Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/tls_rotation/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/tls-rotation-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/tls_rotation/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/tls-rotation-tests.yml'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
@@ -28,13 +16,13 @@ jobs:
|
||||
timeout-minutes: 10
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Build weed binary
|
||||
run: |
|
||||
|
||||
@@ -2,13 +2,6 @@ name: "TUS Protocol Tests"
|
||||
|
||||
on:
|
||||
pull_request:
|
||||
paths:
|
||||
- 'weed/server/**'
|
||||
- 'weed/filer/**'
|
||||
- 'test/tus/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/tus-tests.yml'
|
||||
|
||||
concurrency:
|
||||
group: ${{ github.head_ref || github.ref }}/tus-tests
|
||||
@@ -29,10 +22,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Check out code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
id: go
|
||||
|
||||
@@ -3,20 +3,8 @@ name: "Vacuum Integration Tests"
|
||||
on:
|
||||
push:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/vacuum/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/vacuum-integration-tests.yml'
|
||||
pull_request:
|
||||
branches: [ master ]
|
||||
paths:
|
||||
- 'weed/**'
|
||||
- 'test/vacuum/**'
|
||||
- 'go.mod'
|
||||
- 'go.sum'
|
||||
- '.github/workflows/vacuum-integration-tests.yml'
|
||||
|
||||
permissions:
|
||||
contents: read
|
||||
@@ -28,13 +16,13 @@ jobs:
|
||||
timeout-minutes: 15
|
||||
steps:
|
||||
- name: Set up Go 1.x
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version: ^1.26
|
||||
go-version: ^1.25
|
||||
id: go
|
||||
|
||||
- name: Check out code into the Go module directory
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Build weed binary
|
||||
run: |
|
||||
|
||||
@@ -29,8 +29,6 @@ permissions:
|
||||
|
||||
env:
|
||||
TEST_TIMEOUT: '30m'
|
||||
# Keep in step with the length of matrix.shard below.
|
||||
SHARD_COUNT: 3
|
||||
|
||||
jobs:
|
||||
volume-server-integration-tests:
|
||||
@@ -45,10 +43,10 @@ jobs:
|
||||
|
||||
steps:
|
||||
- name: Checkout code
|
||||
uses: actions/checkout@v7
|
||||
uses: actions/checkout@v6
|
||||
|
||||
- name: Set up Go
|
||||
uses: actions/setup-go@v7
|
||||
uses: actions/setup-go@v6
|
||||
with:
|
||||
go-version-file: 'go.mod'
|
||||
|
||||
@@ -59,26 +57,28 @@ jobs:
|
||||
chmod +x weed
|
||||
./weed version
|
||||
|
||||
# Dealing the listed tests out one by one keeps the shards even. Bucketing
|
||||
# them by first letter did not: names cluster, so ^Test[I-S] drew 50 of
|
||||
# the 114 grpc tests and ran nearly twice as long as the other two shards.
|
||||
- name: Select this shard's tests
|
||||
env:
|
||||
TEST_TYPE: ${{ matrix.test-type }}
|
||||
SHARD: ${{ matrix.shard }}
|
||||
run: |
|
||||
tests=$(go test ./test/volume_server/"$TEST_TYPE"/... -list '.*' | grep '^Test' | sort -u)
|
||||
# An empty list would make -run match nothing and the shard pass vacuously.
|
||||
[ -n "$tests" ] || { echo "listed no tests in test/volume_server/$TEST_TYPE"; exit 1; }
|
||||
selected=$(echo "$tests" | awk -v n="$SHARD_COUNT" -v i="$SHARD" 'NR % n == i - 1')
|
||||
echo "shard $SHARD of $SHARD_COUNT runs $(echo "$selected" | wc -l) of $(echo "$tests" | wc -l) tests"
|
||||
echo "TEST_PATTERN=^($(echo "$selected" | paste -sd'|' -))\$" >> "$GITHUB_ENV"
|
||||
|
||||
- name: Run volume server integration tests
|
||||
env:
|
||||
WEED_BINARY: ${{ github.workspace }}/weed/weed
|
||||
run: |
|
||||
echo "Running volume server integration tests for ${{ matrix.test-type }} (Shard ${{ matrix.shard }} of ${SHARD_COUNT})..."
|
||||
if [ "${{ matrix.test-type }}" == "grpc" ]; then
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-H]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[I-S]"
|
||||
else
|
||||
TEST_PATTERN="^Test[T-Z]"
|
||||
fi
|
||||
else
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-G]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[H-R]"
|
||||
else
|
||||
TEST_PATTERN="^Test[S-Z]"
|
||||
fi
|
||||
fi
|
||||
echo "Running volume server integration tests for ${{ matrix.test-type }} (Shard ${{ matrix.shard }}, pattern: ${TEST_PATTERN})..."
|
||||
go test -v -count=1 -timeout=${{ env.TEST_TIMEOUT }} ./test/volume_server/${{ matrix.test-type }}/... -run "${TEST_PATTERN}"
|
||||
|
||||
- name: Collect logs on failure
|
||||
@@ -99,6 +99,23 @@ jobs:
|
||||
- name: Test summary
|
||||
if: always()
|
||||
run: |
|
||||
if [ "${{ matrix.test-type }}" == "grpc" ]; then
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-H]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[I-S]"
|
||||
else
|
||||
TEST_PATTERN="^Test[T-Z]"
|
||||
fi
|
||||
else
|
||||
if [ "${{ matrix.shard }}" == "1" ]; then
|
||||
TEST_PATTERN="^Test[A-G]"
|
||||
elif [ "${{ matrix.shard }}" == "2" ]; then
|
||||
TEST_PATTERN="^Test[H-R]"
|
||||
else
|
||||
TEST_PATTERN="^Test[S-Z]"
|
||||
fi
|
||||
fi
|
||||
echo "## Volume Server Integration Test Summary (${{ matrix.test-type }} - Shard ${{ matrix.shard }})" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Suite: test/volume_server/${{ matrix.test-type }} (shard ${{ matrix.shard }} of ${SHARD_COUNT}, see 'Select this shard's tests' for the split)" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Command: go test -v -count=1 -timeout=${{ env.TEST_TIMEOUT }} ./test/volume_server/${{ matrix.test-type }}/... -run \"\${TEST_PATTERN}\"" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Suite: test/volume_server/${{ matrix.test-type }} (Pattern: ${TEST_PATTERN})" >> "$GITHUB_STEP_SUMMARY"
|
||||
echo "- Command: go test -v -count=1 -timeout=${{ env.TEST_TIMEOUT }} ./test/volume_server/${{ matrix.test-type }}/... -run \"${TEST_PATTERN}\"" >> "$GITHUB_STEP_SUMMARY"
|
||||
|
||||
@@ -116,6 +116,7 @@ test/s3/versioning/weed-test.log
|
||||
/docker/admin_integration/data
|
||||
docker/agent_pub_record
|
||||
docker/admin_integration/weed-local
|
||||
/seaweedfs-rdma-sidecar/bin
|
||||
/test/s3/encryption/filerldb2
|
||||
/test/s3/sse/filerldb2
|
||||
test/s3/sse/weed-test.log
|
||||
|
||||
@@ -12,258 +12,424 @@
|
||||
|
||||
|
||||
|
||||
SeaweedFS is a simple and highly scalable distributed file system. There are two objectives:
|
||||
<h2 align="center"><a href="https://www.patreon.com/seaweedfs">Sponsor SeaweedFS via Patreon</a></h2>
|
||||
|
||||
1. to store billions of files!
|
||||
2. to serve the files fast!
|
||||
SeaweedFS is an independent Apache-licensed open source project with its ongoing development made
|
||||
possible entirely thanks to the support of these awesome [backers](https://github.com/seaweedfs/seaweedfs/blob/master/backers.md).
|
||||
If you'd like to grow SeaweedFS even stronger, please consider joining our
|
||||
<a href="https://www.patreon.com/seaweedfs">sponsors on Patreon</a>.
|
||||
|
||||
One `weed` binary serves an S3 object store, a POSIX file system, and a lakehouse with S3 Tables, all over the same data. Each blob is one disk read away, capacity grows by starting another volume server, and cloud storage can be cached or tiered transparently. Both read and write operations have O(1) complexity and can run at the full speed supported by the underlying hardware.
|
||||
Your support will be really appreciated by me and other supporters!
|
||||
|
||||
<!--
|
||||
<h4 align="center">Platinum</h4>
|
||||
|
||||
<p align="center">
|
||||
<a href="" target="_blank">
|
||||
Add your name or icon here
|
||||
</a>
|
||||
</p>
|
||||
-->
|
||||
|
||||
### Gold Sponsors
|
||||
[](https://www.nodion.com)
|
||||
[](https://www.piknik.com)
|
||||
[](https://www.keepsec.ca)
|
||||
|
||||
---
|
||||
|
||||
- [Download Binaries for different platforms](https://github.com/seaweedfs/seaweedfs/releases/latest)
|
||||
- [SeaweedFS on Slack](https://join.slack.com/t/seaweedfs/shared_invite/enQtMzI4MTMwMjU2MzA3LTEyYzZmZWYzOGQ3MDJlZWMzYmI0OTE4OTJiZjJjODBmMzUxNmYwODg0YjY3MTNlMjBmZDQ1NzQ5NDJhZWI2ZmY)
|
||||
- [SeaweedFS on Twitter](https://twitter.com/SeaweedFS)
|
||||
- [SeaweedFS on Telegram](https://t.me/Seaweedfs)
|
||||
- [SeaweedFS on Reddit](https://www.reddit.com/r/SeaweedFS/)
|
||||
- [SeaweedFS Mailing List](https://groups.google.com/d/forum/seaweedfs)
|
||||
- [Wiki Documentation](https://github.com/seaweedfs/seaweedfs/wiki)
|
||||
- [HTTP REST API](REST_API.md) for the filer, master, and volume servers
|
||||
- Community: [Slack](https://join.slack.com/t/seaweedfs/shared_invite/enQtMzI4MTMwMjU2MzA3LTEyYzZmZWYzOGQ3MDJlZWMzYmI0OTE4OTJiZjJjODBmMzUxNmYwODg0YjY3MTNlMjBmZDQ1NzQ5NDJhZWI2ZmY), [Twitter](https://twitter.com/SeaweedFS), [Telegram](https://t.me/Seaweedfs), [Reddit](https://www.reddit.com/r/SeaweedFS/), [Mailing List](https://groups.google.com/d/forum/seaweedfs)
|
||||
- [SeaweedFS White Paper](https://github.com/seaweedfs/seaweedfs/wiki/SeaweedFS_Architecture.pdf) and introduction slides: [2025.5](https://docs.google.com/presentation/d/1tdkp45J01oRV68dIm4yoTXKJDof-EhainlA0LMXexQE/edit?usp=sharing), [2021.5](https://docs.google.com/presentation/d/1DcxKWlINc-HNCjhYeERkpGXXm6nTCES8mi2W5G0Z4Ts/edit?usp=sharing), [2019.3](https://www.slideshare.net/chrislusf/seaweedfs-introduction)
|
||||
- [SeaweedFS White Paper](https://github.com/seaweedfs/seaweedfs/wiki/SeaweedFS_Architecture.pdf)
|
||||
- [SeaweedFS Introduction Slides 2025.5](https://docs.google.com/presentation/d/1tdkp45J01oRV68dIm4yoTXKJDof-EhainlA0LMXexQE/edit?usp=sharing)
|
||||
- [SeaweedFS Introduction Slides 2021.5](https://docs.google.com/presentation/d/1DcxKWlINc-HNCjhYeERkpGXXm6nTCES8mi2W5G0Z4Ts/edit?usp=sharing)
|
||||
- [SeaweedFS Introduction Slides 2019.3](https://www.slideshare.net/chrislusf/seaweedfs-introduction)
|
||||
|
||||
Table of Contents
|
||||
=================
|
||||
|
||||
* [Quick Start](#quick-start)
|
||||
* [One command](#one-command)
|
||||
* [Docker](#docker)
|
||||
* [Docker Compose](#docker-compose)
|
||||
* [Kubernetes with Helm](#kubernetes-with-helm)
|
||||
* [Build from source](#build-from-source)
|
||||
* [Scale out](#scale-out)
|
||||
* [Why SeaweedFS](#why-seaweedfs)
|
||||
* [Fast](#fast)
|
||||
* [Scalable](#scalable)
|
||||
* [The most complete S3 API](#the-most-complete-s3-api)
|
||||
* [A data warehouse with S3 Tables](#a-data-warehouse-with-s3-tables)
|
||||
* [A fast cache for cloud storage](#a-fast-cache-for-cloud-storage)
|
||||
* [Active-active replication and more](#active-active-replication-and-more)
|
||||
* [Architecture](#architecture)
|
||||
* [Compared to Other Systems](#compared-to-other-systems)
|
||||
* [Quick Start with weed mini](#quick-start-with-weed-mini)
|
||||
* [Quick Start for S3 API on Docker](#quick-start-for-s3-api-on-docker)
|
||||
* [Introduction](#introduction)
|
||||
* [Features](#features)
|
||||
* [Additional Features](#additional-features)
|
||||
* [Filer Features](#filer-features)
|
||||
* [Example: Using Seaweed Object Store](#example-using-seaweed-object-store)
|
||||
* [Architecture](#object-store-architecture)
|
||||
* [Compared to Other File Systems](#compared-to-other-file-systems)
|
||||
* [Compared to HDFS](#compared-to-hdfs)
|
||||
* [Compared to GlusterFS, Ceph](#compared-to-glusterfs-ceph)
|
||||
* [Compared to MooseFS](#compared-to-moosefs)
|
||||
* [Compared to GlusterFS](#compared-to-glusterfs)
|
||||
* [Compared to Ceph](#compared-to-ceph)
|
||||
* [Compared to MinIO, RustFS](#compared-to-minio-rustfs)
|
||||
* [Compared to Minio](#compared-to-minio)
|
||||
* [Dev Plan](#dev-plan)
|
||||
* [Installation Guide](#installation-guide)
|
||||
* [Disk Related Topics](#disk-related-topics)
|
||||
* [Benchmark](#benchmark)
|
||||
* [Enterprise](#enterprise)
|
||||
* [License](#license)
|
||||
* [Sponsors](#sponsors)
|
||||
|
||||
# Quick Start #
|
||||
|
||||
## One command ##
|
||||
|
||||
Download the latest binary from the [releases](https://github.com/seaweedfs/seaweedfs/releases/latest) page and unzip the single `weed` (or `weed.exe`) file, or let the install script put it in `/usr/local/bin`:
|
||||
## Quick Start with weed mini ##
|
||||
|
||||
```bash
|
||||
curl -fsSL https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/install.sh | bash
|
||||
```
|
||||
|
||||
Then start a ready-to-use S3 object store:
|
||||
Download the latest binary from https://github.com/seaweedfs/seaweedfs/releases and unzip the single `weed` (or `weed.exe`) file, or run `go install github.com/seaweedfs/seaweedfs/weed@latest`. Then start a ready-to-use S3 object store with credentials and a pre-created bucket in one command:
|
||||
|
||||
```bash
|
||||
AWS_ACCESS_KEY_ID=admin \
|
||||
AWS_SECRET_ACCESS_KEY=secret \
|
||||
S3_BUCKET=my-bucket \
|
||||
./weed mini -dir=./data
|
||||
./weed mini -dir=/data
|
||||
```
|
||||
|
||||
That's it. The S3 endpoint is at http://localhost:8333, `my-bucket` exists, and `admin`/`secret` are valid credentials:
|
||||
That's it — the S3 endpoint is at http://localhost:8333, `my-bucket` already exists, and `admin`/`secret` are valid credentials. `S3_BUCKET` accepts a comma-separated list (e.g. `raw,processed`); use `S3_TABLE_BUCKET` for S3 Tables (Iceberg) buckets. Drop any of the env vars to skip that piece (no AWS keys → S3 runs in unauthenticated "Allow All" mode for development).
|
||||
|
||||
```bash
|
||||
AWS_ACCESS_KEY_ID=admin AWS_SECRET_ACCESS_KEY=secret \
|
||||
aws --endpoint-url http://localhost:8333 s3 cp README.md s3://my-bucket/
|
||||
```
|
||||
|
||||
The same process also runs the master, a volume server, the filer, WebDAV, the Iceberg REST catalog, and the Admin UI. Add `S3_TABLE_BUCKET=warehouse` to also create an Iceberg table bucket, or `warehouse:LANCE` for a Lance one. Drop the AWS keys to run without authentication for development.
|
||||
The same command starts everything else too:
|
||||
- **S3 Endpoint**: http://localhost:8333
|
||||
- **Master UI**: http://localhost:9333
|
||||
- **Volume Server**: http://localhost:9340
|
||||
- **Filer UI**: http://localhost:8888
|
||||
- **WebDAV**: http://localhost:7333
|
||||
- **Admin UI**: http://localhost:23646
|
||||
|
||||
> macOS: if the binary is quarantined, run `xattr -d com.apple.quarantine ./weed` first.
|
||||
|
||||
`weed mini` is auto-tuned for one node and is fine for single-node production, such as an S3 gateway that issues presigned URLs. See [Quick Start with weed mini][WeedMini].
|
||||
Perfect for development, testing, learning SeaweedFS, and single-node deployments. To scale out, add more volume servers by running `weed volume -dir="/some/data/dir2" -master="<master_host>:9333" -port=8081` locally, on another machine, or on thousands of machines.
|
||||
|
||||
## Docker ##
|
||||
## Quick Start for S3 API on Docker ##
|
||||
|
||||
```bash
|
||||
docker run -p 8333:8333 -v weed-data:/data \
|
||||
docker run -p 8333:8333 \
|
||||
-e AWS_ACCESS_KEY_ID=admin \
|
||||
-e AWS_SECRET_ACCESS_KEY=secret \
|
||||
-e S3_BUCKET=my-bucket \
|
||||
chrislusf/seaweedfs
|
||||
```
|
||||
|
||||
Same behavior as the `weed mini` command above.
|
||||
Same behavior as the `weed mini` command above — the S3 endpoint is at http://localhost:8333 with `my-bucket` pre-created. Drop the env vars to run anonymously for development.
|
||||
|
||||
## Docker Compose ##
|
||||
# Introduction #
|
||||
|
||||
To run master, volume server, filer, S3, and WebDAV as separate services:
|
||||
SeaweedFS is a simple and highly scalable distributed file system. There are two objectives:
|
||||
|
||||
```bash
|
||||
wget https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/docker/seaweedfs-compose.yml
|
||||
wget -P prometheus https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/docker/prometheus/prometheus.yml
|
||||
docker compose -f seaweedfs-compose.yml -p seaweedfs up
|
||||
```
|
||||
1. to store billions of files!
|
||||
2. to serve the files fast!
|
||||
|
||||
[Docker Compose for S3][DockerComposeS3] adds credentials, and the [docker/compose](docker/compose) folder has variants for replication, mounts, message queues, and more.
|
||||
SeaweedFS started as a blob store to handle small files efficiently.
|
||||
Instead of managing all file metadata in a central master,
|
||||
the central master only manages volumes on volume servers,
|
||||
and these volume servers manage files and their metadata.
|
||||
This relieves concurrency pressure from the central master and spreads file metadata into volume servers,
|
||||
allowing faster file access (O(1), usually just one disk read operation).
|
||||
|
||||
## Kubernetes with Helm ##
|
||||
There is only 40 bytes of disk storage overhead for each file's metadata.
|
||||
It is so simple with O(1) disk reads that you are welcome to challenge the performance with your actual use cases.
|
||||
|
||||
```bash
|
||||
helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
|
||||
helm install seaweedfs seaweedfs/seaweedfs -n seaweedfs --create-namespace -f values.yaml
|
||||
```
|
||||
SeaweedFS started by implementing [Facebook's Haystack design paper](http://www.usenix.org/event/osdi10/tech/full_papers/Beaver.pdf).
|
||||
Also, SeaweedFS implements erasure coding with ideas from
|
||||
[f4: Facebook’s Warm BLOB Storage System](https://www.usenix.org/system/files/conference/osdi14/osdi14-paper-muralidhar.pdf), and has a lot of similarities with [Facebook’s Tectonic Filesystem](https://www.usenix.org/system/files/fast21-pan.pdf) and [Google's Colossus File System](https://cloud.google.com/blog/products/storage-data-transfer/a-peek-behind-colossus-googles-file-system)
|
||||
|
||||
A production-shaped `values.yaml` for a three-node cluster: two copies of every write, three masters, and an S3 endpoint with credentials and a bucket.
|
||||
On top of the blob store, optional [Filer] can support directories and POSIX attributes.
|
||||
Filer is a separate linearly-scalable stateless server with customizable metadata stores,
|
||||
e.g., MySql, Postgres, Redis, Cassandra, HBase, Mongodb, Elastic Search, LevelDB, RocksDB, Sqlite, MemSql, TiDB, Etcd, CockroachDB, YDB, etc.
|
||||
|
||||
```yaml
|
||||
global:
|
||||
seaweedfs:
|
||||
enableReplication: true
|
||||
replicationPlacement: "001" # one extra copy on another server; "002" for two
|
||||
SeaweedFS can transparently integrate with the cloud.
|
||||
With hot data on local cluster, and warm data on the cloud with O(1) access time,
|
||||
SeaweedFS can achieve both fast local access time and elastic cloud storage capacity.
|
||||
What's more, the cloud storage access API cost is minimized.
|
||||
Faster and cheaper than direct cloud storage!
|
||||
|
||||
master:
|
||||
replicas: 3
|
||||
data:
|
||||
type: persistentVolumeClaim # the cluster's default storage class; add storageClass to pick one
|
||||
size: 1Gi
|
||||
|
||||
volume:
|
||||
replicas: 3 # at least 1 + the sum of the replication digits
|
||||
dataDirs:
|
||||
- name: data
|
||||
type: persistentVolumeClaim
|
||||
size: 500Gi
|
||||
maxVolumes: 0 # size the volume count from the disk
|
||||
|
||||
filer:
|
||||
replicas: 2
|
||||
data:
|
||||
type: persistentVolumeClaim
|
||||
size: 20Gi
|
||||
|
||||
s3:
|
||||
enabled: true
|
||||
replicas: 2
|
||||
enableAuth: true
|
||||
credentials:
|
||||
admin:
|
||||
accessKey: admin
|
||||
secretKey: change-me
|
||||
createBuckets:
|
||||
- name: app-storage
|
||||
```
|
||||
|
||||
The S3 endpoint is the `seaweedfs-s3` service on port 8333. [Helm Chart Recipes][HelmRecipes] has values for a development cluster, a lakehouse with the Iceberg catalog exposed, filer metadata on PostgreSQL, and node-local disks. The [SeaweedFS Operator][Operator] and the [CSI driver][SeaweedFsCsiDriver] are the other Kubernetes paths.
|
||||
|
||||
## Build from source ##
|
||||
|
||||
```bash
|
||||
git clone https://github.com/seaweedfs/seaweedfs.git
|
||||
cd seaweedfs/weed && make install
|
||||
```
|
||||
|
||||
`weed` lands in `$GOPATH/bin`. [Getting Started][GettingStarted] covers running master, volume, filer, and S3 as separate processes.
|
||||
|
||||
## Scale out ##
|
||||
|
||||
Capacity is a volume server. Start one on any machine with disk and point it at the master:
|
||||
|
||||
```bash
|
||||
weed volume -dir=/data -master=<master_host>:9333
|
||||
```
|
||||
|
||||
Nothing rebalances until you ask it to. Throughput is a filer or S3 gateway; they are stateless, so run as many as you need behind a load balancer. [Production Setup][ProductionSetup] walks through a multi-node cluster.
|
||||
SeaweedFS also ships a built-in **Iceberg REST Catalog**, turning the same cluster into a self-contained lakehouse.
|
||||
Spark, Trino, Dremio, DuckDB, and RisingWave can query Iceberg tables directly — no Hive Metastore, Glue, or
|
||||
external catalog service required. Storage and table metadata live in one system, simplifying on-prem and
|
||||
small-team analytics stacks.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# Why SeaweedFS #
|
||||
|
||||
## Fast ##
|
||||
|
||||
* One disk read per blob. A small file is one blob; a large file is split into chunks of a few MB, each its own blob. A volume server keeps a 16-byte index entry per blob in memory and reads it in a single seek, also for erasure-coded data.
|
||||
* The master is not in the read path. Clients cache the volume-to-server mapping and talk to volume servers directly.
|
||||
* 40 bytes of metadata per file on disk. Small files are packed into append-only volume files, so there is no per-file inode, no per-file metadata file, no fragmentation, and writes are SSD friendly.
|
||||
* Hot data is replicated; [erasure coding][ErasureCoding] is applied to warm data in the background, so writes never pay the encoding cost.
|
||||
* The [Rust volume server][RustVolume] is a drop-in for higher throughput and lower tail latency on the same on-disk format.
|
||||
|
||||
On one laptop, [`weed benchmark`][Benchmarks] writes 1KB files at 15,700 per second and reads them back at 47,000 per second, and a mixed S3 [warp][S3Benchmark] run totals 3.2 GiB/s. Numbers are in the [Benchmark](#benchmark) section; throughput grows with volume servers and gateways.
|
||||
|
||||
## Scalable ##
|
||||
|
||||
* The master tracks volumes, not files. A cluster with billions of files has a few thousand volumes, so the master stays small. One master is enough for most clusters; run three for [Raft failover][FailoverMaster].
|
||||
* Adding a server adds capacity with no data reshuffle. Balancing, vacuum, erasure coding, and repair run on demand from [`weed shell`][WeedShell] or the [maintenance worker][Worker].
|
||||
* Filer and S3 gateways are stateless and scale linearly. Directory metadata lives in a [store you already run][FilerStores]: LevelDB, RocksDB, SQLite, MySQL, PostgreSQL, Cassandra, HBase, MongoDB, Redis, Elasticsearch, etcd, TiKV, FoundationDB, YDB, ArangoDB, Tarantool, and MySQL or PostgreSQL compatible databases such as TiDB, CockroachDB, and MemSQL.
|
||||
* Rack and data center aware [replication][Replication], [tiered storage][TieredStorage] across disk types, and [transparent cloud tiering][CloudTier] for unlimited capacity.
|
||||
* Files from a byte to [tens of TB][SuperLargeFiles]. Volumes up to 8TB with the large-disk build.
|
||||
|
||||
## The most complete S3 API ##
|
||||
|
||||
The S3 gateway implements the object, bucket, S3 Tables, IAM, and STS APIs on one endpoint, so the AWS SDKs and CLI, rclone, restic, Spark, and Trino work unchanged.
|
||||
|
||||
| API | Operations |
|
||||
| --- | --- |
|
||||
| S3 bucket and object | 73 |
|
||||
| S3 Tables | 36 |
|
||||
| IAM | 39 |
|
||||
| STS | 5 |
|
||||
|
||||
* [Versioning][Versioning], [Object Lock][ObjectLock] with retention and legal hold, [lifecycle][Lifecycle] rules, tagging, [CORS][CORS], [conditional reads and writes][ConditionalOps], checksums, presigned URLs, browser POST uploads, multipart uploads, and an atomic [RenameObject][RenameObject].
|
||||
* [Bucket policies][BucketPolicies] with [conditions][PolicyConditions] and [variables][PolicyVariables]; IAM users, groups, and policies; STS with [OIDC][OIDC], LDAP, and [Kubernetes service accounts][K8sSA].
|
||||
* [SSE-S3, SSE-KMS, and SSE-C][SSE] server-side encryption, with OpenBao and Vault, AWS KMS, Azure Key Vault, and GCP KMS as key providers.
|
||||
* [Audit log][AuditLog], [bucket quota][BucketQuota], and [rate limiting][RateLimiting].
|
||||
* Each bucket is its own collection, so deleting a bucket is instant.
|
||||
|
||||
The full operation list is in [Amazon S3 API][AmazonS3API], and [Supported APIs vs MinIO][S3vsMinio] compares. The S3 compatibility suite and the SDK, IAM, SSE, policy, and Spark integration tests run in CI on every change.
|
||||
|
||||
## A data warehouse with S3 Tables ##
|
||||
|
||||
SeaweedFS is a lakehouse in one system. [S3 Table Buckets][S3TableBucket] hold Apache Iceberg tables by default, or [Lance][LanceCatalog] tables for vectors and multimodal data, and the built-in [Iceberg REST Catalog][IcebergCatalog] and Lance namespace serve them directly. There is no Hive Metastore, Glue, or separate catalog service to deploy, secure, and back up.
|
||||
|
||||
* Query engines operate on the same tables at the same time: [Spark][SparkIceberg], [Trino][TrinoIceberg], [Dremio][DremioIceberg], [DuckDB][DuckDBIceberg], [Apache Doris][DorisIceberg], [RisingWave][RisingWaveIceberg], ClickHouse, and [LanceDB][LanceDB]. Catalog commits are atomic compare-and-swap, so concurrent writers are safe. [Lakekeeper][Lakekeeper] can front the same storage with STS-vended credentials.
|
||||
* [Automated table maintenance][IcebergMaintenance]: compaction, snapshot expiration, orphan file removal, and manifest rewriting, configured per bucket or table through the S3 Tables maintenance APIs, and the same for [Lance][LanceMaintenance].
|
||||
* IAM at the bucket, namespace, and table level with standard bucket policies, see [S3 Tables Security][S3TablesSecurity].
|
||||
* A [Hadoop compatible file system][Hadoop] for Spark, Flink, and HBase.
|
||||
|
||||
`S3_TABLE_BUCKET=warehouse ./weed mini -dir=./data` brings the whole stack up on a laptop.
|
||||
|
||||
## A fast cache for cloud storage ##
|
||||
|
||||
[Cloud Drive][CloudDrive] mounts a bucket from S3, Google Cloud Storage, Azure, Backblaze B2, Wasabi, Storj, or any S3-compatible store into SeaweedFS and serves it at local speed:
|
||||
|
||||
* Metadata is pulled once, so listing, stat, and directory walks cost no cloud API calls.
|
||||
* File content is downloaded once, on first read or [warmed][CacheRemote] by folder, name pattern, size, or age, and cached with the capacity of the whole cluster: cache everything, no churn.
|
||||
* Local writes complete at local latency and are written back to the cloud asynchronously in the cloud's native layout, so other tools keep reading the bucket directly.
|
||||
* Uncache by the same rules to free local disk while keeping the metadata.
|
||||
|
||||
[Cloud Tier][CloudTier] goes the other direction, moving whole warm volumes to cloud storage while keeping one-read access, and the [Gateway to Remote Object Storage][GatewayToRemoteObjectStore] mirrors every bucket to a remote store. Faster and cheaper than reading the cloud directly.
|
||||
|
||||
## Active-active replication and more ##
|
||||
|
||||
* [Active-active or active-passive replication][ActiveActiveAsyncReplication] between clusters, continuous and resumable, for the whole tree or chosen folders, across data centers.
|
||||
* [Filer store replication][FilerStoreReplication] for metadata HA, [async backup][AsyncBackup] to cloud storage, [metadata backup][MetaBackup], and [change data capture][CDC] with [webhooks][Webhook] on every metadata event.
|
||||
* The same data as a [FUSE mount][Mount] on Linux, macOS, and [Windows][MountWindows], over [WebDAV][WebDAV], [SFTP][SFTP], HDFS, HTTP, and [TUS resumable uploads][TUS]; on Kubernetes through the [CSI driver][SeaweedFsCsiDriver] and [Operator][Operator].
|
||||
* [AES256-GCM encryption at rest][FilerDataEncryption], TLS and mTLS between components, JWT-signed volume access, and [FIPS][FIPS] builds.
|
||||
* [Admin UI][AdminUI], Prometheus [metrics][Metrics], [TTL][VolumeServerTTL] per file or volume, automatic compression and compaction, and [seaweed-up][SeaweedUp] for bare-metal clusters.
|
||||
# Features #
|
||||
## Additional Blob Store Features ##
|
||||
* Support different replication levels, with rack and data center aware.
|
||||
* Automatic master servers failover - no single point of failure (SPOF).
|
||||
* Automatic compression depending on file MIME type.
|
||||
* Automatic compaction to reclaim disk space after deletion or update.
|
||||
* [Automatic entry TTL expiration][VolumeServerTTL].
|
||||
* Flexible Capacity Expansion: Any server with some disk space can add to the total storage space.
|
||||
* Adding/Removing servers does **not** cause any data re-balancing unless triggered by admin commands.
|
||||
* Optional picture resizing.
|
||||
* Support ETag, Accept-Range, Last-Modified, etc.
|
||||
* Support in-memory/leveldb/readonly mode tuning for memory/performance balance.
|
||||
* Support rebalancing the writable and readonly volumes.
|
||||
* [Customizable Multiple Storage Tiers][TieredStorage]: Customizable storage disk types to balance performance and cost.
|
||||
* [Transparent cloud integration][CloudTier]: unlimited capacity via tiered cloud storage for warm data.
|
||||
* [Erasure Coding for warm storage][ErasureCoding] Rack-Aware 10.4 erasure coding reduces storage cost and increases availability. Enterprise version can customize EC ratio.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# Architecture #
|
||||
## Filer Features ##
|
||||
* [Filer server][Filer] provides "normal" directories and files via HTTP.
|
||||
* [File TTL][FilerTTL] automatically expires file metadata and actual file data.
|
||||
* [Mount filer][Mount] reads and writes files directly as a local directory via FUSE.
|
||||
* [Filer Store Replication][FilerStoreReplication] enables HA for filer meta data stores.
|
||||
* [Active-Active Replication][ActiveActiveAsyncReplication] enables asynchronous one-way or two-way cross cluster continuous replication.
|
||||
* [Amazon S3 compatible API][AmazonS3API] accesses files with S3 tooling.
|
||||
* [Hadoop Compatible File System][Hadoop] accesses files from Hadoop/Spark/Flink/etc or even runs HBase.
|
||||
* [Async Replication To Cloud][BackupToCloud] has extremely fast local access and backups to Amazon S3, Google Cloud Storage, Azure, BackBlaze.
|
||||
* [WebDAV] accesses as a mapped drive on Mac and Windows, or from mobile devices.
|
||||
* [AES256-GCM Encrypted Storage][FilerDataEncryption] safely stores the encrypted data.
|
||||
* [Super Large Files][SuperLargeFiles] stores large or super large files in tens of TB.
|
||||
* [Cloud Drive][CloudDrive] mounts cloud storage to local cluster, cached for fast read and write with asynchronous write back.
|
||||
* [Gateway to Remote Object Store][GatewayToRemoteObjectStore] mirrors bucket operations to remote object storage, in addition to [Cloud Drive][CloudDrive]
|
||||
|
||||
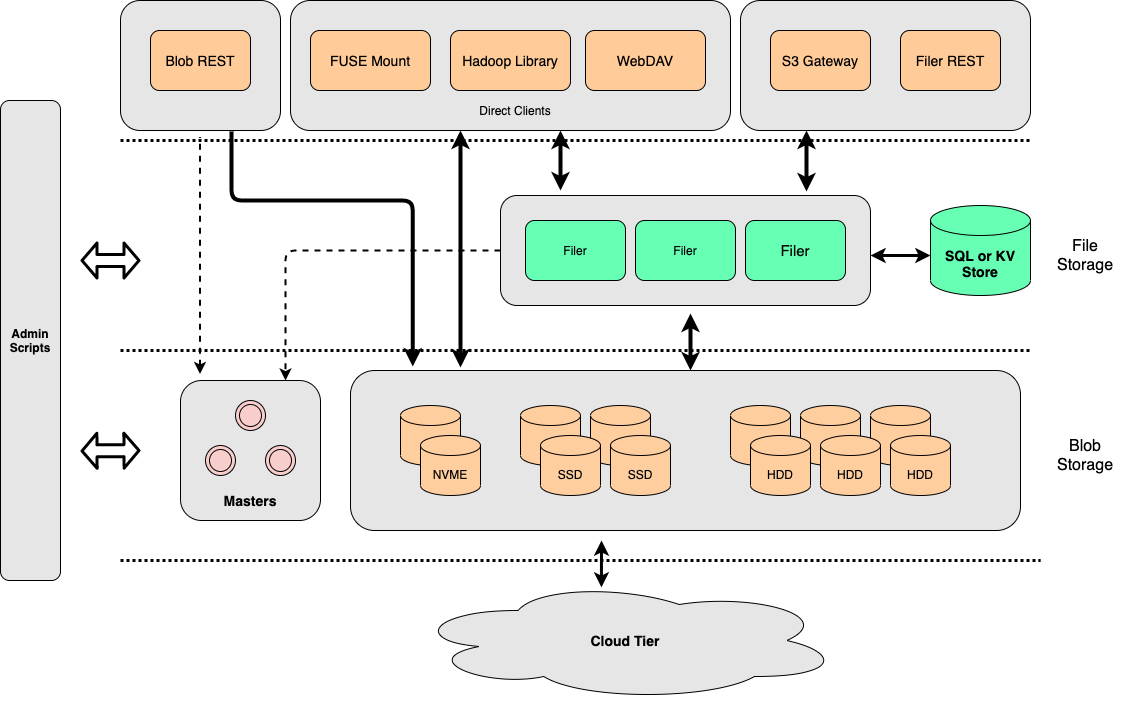
|
||||
## Data Lakehouse Features ##
|
||||
* [S3 Table Buckets][S3TableBucket] expose a dedicated namespace for Iceberg tables with strict layout validation.
|
||||
* Built-in [Iceberg REST Catalog][IcebergCatalog] runs alongside the S3 endpoint — no external metastore needed.
|
||||
* Native integrations with [Apache Spark][SparkIceberg], [Trino][TrinoIceberg], [Dremio][DremioIceberg], [DuckDB][DuckDBIceberg], and [RisingWave][RisingWaveIceberg].
|
||||
* [Automated table maintenance][IcebergMaintenance]: compaction, snapshot expiration, orphan removal, manifest rewriting.
|
||||
* Granular IAM at the bucket, namespace, and table level via standard S3 bucket policies.
|
||||
|
||||
* **Master** servers, one or a Raft group of three, track which volume lives on which volume server and hand out file ids. They are not in the read path.
|
||||
* **Volume** servers store blobs in append-only volume files, keep a 16-byte in-memory index per blob, and replicate or erasure-code at the volume level.
|
||||
* **Filer** servers add directories and files on top, with metadata in a store of your choice, and expose HTTP, S3, WebDAV, SFTP, FUSE, and the table catalogs.
|
||||
## Kubernetes ##
|
||||
* [Kubernetes CSI Driver][SeaweedFsCsiDriver] A Container Storage Interface (CSI) Driver. [](https://hub.docker.com/r/chrislusf/seaweedfs-csi-driver/)
|
||||
* [SeaweedFS Operator](https://github.com/seaweedfs/seaweedfs-operator)
|
||||
|
||||
[Filer]: https://github.com/seaweedfs/seaweedfs/wiki/Directories-and-Files
|
||||
[SuperLargeFiles]: https://github.com/seaweedfs/seaweedfs/wiki/Data-Structure-for-Large-Files
|
||||
[Mount]: https://github.com/seaweedfs/seaweedfs/wiki/FUSE-Mount
|
||||
[AmazonS3API]: https://github.com/seaweedfs/seaweedfs/wiki/Amazon-S3-API
|
||||
[BackupToCloud]: https://github.com/seaweedfs/seaweedfs/wiki/Async-Replication-to-Cloud
|
||||
[Hadoop]: https://github.com/seaweedfs/seaweedfs/wiki/Hadoop-Compatible-File-System
|
||||
[WebDAV]: https://github.com/seaweedfs/seaweedfs/wiki/WebDAV
|
||||
[ErasureCoding]: https://github.com/seaweedfs/seaweedfs/wiki/Erasure-coding-for-warm-storage
|
||||
[TieredStorage]: https://github.com/seaweedfs/seaweedfs/wiki/Tiered-Storage
|
||||
[CloudTier]: https://github.com/seaweedfs/seaweedfs/wiki/Cloud-Tier
|
||||
[FilerDataEncryption]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Data-Encryption
|
||||
[FilerTTL]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Stores
|
||||
[VolumeServerTTL]: https://github.com/seaweedfs/seaweedfs/wiki/Store-file-with-a-Time-To-Live
|
||||
[SeaweedFsCsiDriver]: https://github.com/seaweedfs/seaweedfs-csi-driver
|
||||
[ActiveActiveAsyncReplication]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Active-Active-cross-cluster-continuous-synchronization
|
||||
[FilerStoreReplication]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Store-Replication
|
||||
[KeyLargeValueStore]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-as-a-Key-Large-Value-Store
|
||||
[CloudDrive]: https://github.com/seaweedfs/seaweedfs/wiki/Cloud-Drive-Architecture
|
||||
[GatewayToRemoteObjectStore]: https://github.com/seaweedfs/seaweedfs/wiki/Gateway-to-Remote-Object-Storage
|
||||
[S3TableBucket]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Table-Bucket
|
||||
[IcebergCatalog]: https://github.com/seaweedfs/seaweedfs/wiki/SeaweedFS-Iceberg-Catalog
|
||||
[IcebergMaintenance]: https://github.com/seaweedfs/seaweedfs/wiki/Iceberg-Table-Maintenance
|
||||
[SparkIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Spark-Iceberg-Integration
|
||||
[TrinoIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Trino-Iceberg-Integration
|
||||
[DremioIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Dremio-Iceberg-Integration
|
||||
[DuckDBIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/DuckDB-Iceberg-Integration
|
||||
[RisingWaveIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/RisingWave-Iceberg-Integration
|
||||
|
||||
The blob store started from [Facebook's Haystack](http://www.usenix.org/event/osdi10/tech/full_papers/Beaver.pdf), erasure coding takes ideas from [f4](https://www.usenix.org/system/files/conference/osdi14/osdi14-paper-muralidhar.pdf), and the whole has a lot in common with [Tectonic](https://www.usenix.org/system/files/fast21-pan.pdf) and [Colossus](https://cloud.google.com/blog/products/storage-data-transfer/a-peek-behind-colossus-googles-file-system). How file ids are assigned, written, and looked up, and why a master that tracks volumes scales, is in [Blob Store Architecture][BlobStoreArchitecture]; the services are in [Components][Components] and the [white paper][WhitePaper].
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# Compared to Other Systems #
|
||||
## Example: Using Seaweed Blob Store ##
|
||||
|
||||
By default, the master node runs on port 9333, and the volume nodes run on port 8080.
|
||||
Let's start one master node, and two volume nodes on port 8080 and 8081. Ideally, they should be started from different machines. We'll use localhost as an example.
|
||||
|
||||
SeaweedFS uses HTTP REST operations to read, write, and delete. The responses are in JSON or JSONP format.
|
||||
|
||||
### Start Master Server ###
|
||||
|
||||
```
|
||||
> ./weed master
|
||||
```
|
||||
|
||||
### Start Volume Servers ###
|
||||
|
||||
```
|
||||
> weed volume -dir="/tmp/data1" -max=5 -master="localhost:9333" -port=8080 &
|
||||
> weed volume -dir="/tmp/data2" -max=10 -master="localhost:9333" -port=8081 &
|
||||
```
|
||||
|
||||
### Write A Blob ###
|
||||
|
||||
A blob, also referred as a needle, a chunk, or mistakenly as a file, is just a byte array. It can have attributes, such as name, mime type, create or update time, etc. But basically it is just a byte array of a relatively small size, such as 2 MB ~ 64 MB. The size is not fixed.
|
||||
|
||||
To upload a blob: first, send a HTTP POST, PUT, or GET request to `/dir/assign` to get an `fid` and a volume server URL:
|
||||
|
||||
```
|
||||
> curl http://localhost:9333/dir/assign
|
||||
{"count":1,"fid":"3,01637037d6","url":"127.0.0.1:8080","publicUrl":"localhost:8080"}
|
||||
```
|
||||
|
||||
Second, to store the blob content, send a HTTP multi-part POST request to `url + '/' + fid` from the response:
|
||||
|
||||
```
|
||||
> curl -F file=@/home/chris/myphoto.jpg http://127.0.0.1:8080/3,01637037d6
|
||||
{"name":"myphoto.jpg","size":43234,"eTag":"1cc0118e"}
|
||||
```
|
||||
|
||||
To update, send another POST request with updated blob content.
|
||||
|
||||
For deletion, send an HTTP DELETE request to the same `url + '/' + fid` URL:
|
||||
|
||||
```
|
||||
> curl -X DELETE http://127.0.0.1:8080/3,01637037d6
|
||||
```
|
||||
|
||||
### Save Blob Id ###
|
||||
|
||||
Now, you can save the `fid`, 3,01637037d6 in this case, to a database field.
|
||||
|
||||
The number 3 at the start represents a volume id. After the comma, it's one file key, 01, and a file cookie, 637037d6.
|
||||
|
||||
The volume id is an unsigned 32-bit integer. The file key is an unsigned 64-bit integer. The file cookie is an unsigned 32-bit integer, used to prevent URL guessing.
|
||||
|
||||
The file key and file cookie are both coded in hex. You can store the <volume id, file key, file cookie> tuple in your own format, or simply store the `fid` as a string.
|
||||
|
||||
If stored as a string, in theory, you would need 8+1+16+8=33 bytes. A char(33) would be enough, if not more than enough, since most uses will not need 2^32 volumes.
|
||||
|
||||
If space is really a concern, you can store the file id in the binary format. You would need one 4-byte integer for volume id, 8-byte long number for file key, and a 4-byte integer for the file cookie. So 16 bytes are more than enough.
|
||||
|
||||
### Read a Blob ###
|
||||
|
||||
Here is an example of how to render the URL.
|
||||
|
||||
First look up the volume server's URLs by the file's volumeId:
|
||||
|
||||
```
|
||||
> curl http://localhost:9333/dir/lookup?volumeId=3
|
||||
{"volumeId":"3","locations":[{"publicUrl":"localhost:8080","url":"localhost:8080"}]}
|
||||
```
|
||||
|
||||
Since (usually) there are not too many volume servers, and volumes don't move often, you can cache the results most of the time. Depending on the replication type, one volume can have multiple replica locations. Just randomly pick one location to read.
|
||||
|
||||
Now you can take the public URL, render the URL or directly read from the volume server via URL:
|
||||
|
||||
```
|
||||
http://localhost:8080/3,01637037d6.jpg
|
||||
```
|
||||
|
||||
Notice we add a file extension ".jpg" here. It's optional and just one way for the client to specify the file content type.
|
||||
|
||||
If you want a nicer URL, you can use one of these alternative URL formats:
|
||||
|
||||
```
|
||||
http://localhost:8080/3/01637037d6/my_preferred_name.jpg
|
||||
http://localhost:8080/3/01637037d6.jpg
|
||||
http://localhost:8080/3,01637037d6.jpg
|
||||
http://localhost:8080/3/01637037d6
|
||||
http://localhost:8080/3,01637037d6
|
||||
```
|
||||
|
||||
If you want to get a scaled version of an image, you can add some params:
|
||||
|
||||
```
|
||||
http://localhost:8080/3/01637037d6.jpg?height=200&width=200
|
||||
http://localhost:8080/3/01637037d6.jpg?height=200&width=200&mode=fit
|
||||
http://localhost:8080/3/01637037d6.jpg?height=200&width=200&mode=fill
|
||||
```
|
||||
|
||||
### Rack-Aware and Data Center-Aware Replication ###
|
||||
|
||||
SeaweedFS applies the replication strategy at a volume level. So, when you are getting a blob id, you can specify the replication strategy. For example:
|
||||
|
||||
```
|
||||
curl http://localhost:9333/dir/assign?replication=001
|
||||
```
|
||||
|
||||
The replication parameter options are:
|
||||
|
||||
```
|
||||
000: no replication
|
||||
001: replicate once on the same rack
|
||||
010: replicate once on a different rack, but same data center
|
||||
100: replicate once on a different data center
|
||||
200: replicate twice on two different data center
|
||||
110: replicate once on a different rack, and once on a different data center
|
||||
```
|
||||
|
||||
More details about replication can be found [on the wiki][Replication].
|
||||
|
||||
[Replication]: https://github.com/seaweedfs/seaweedfs/wiki/Replication
|
||||
|
||||
You can also set the default replication strategy when starting the master server.
|
||||
|
||||
### Allocate Blob Key on Specific Data Center ###
|
||||
|
||||
Volume servers can be started with a specific data center name:
|
||||
|
||||
```
|
||||
weed volume -dir=/tmp/1 -port=8080 -dataCenter=dc1
|
||||
weed volume -dir=/tmp/2 -port=8081 -dataCenter=dc2
|
||||
```
|
||||
|
||||
When requesting a blob key, an optional "dataCenter" parameter can limit the assigned volume to the specific data center. For example, this specifies that the assigned volume should be limited to 'dc1':
|
||||
|
||||
```
|
||||
http://localhost:9333/dir/assign?dataCenter=dc1
|
||||
```
|
||||
|
||||
### Other Features ###
|
||||
* [No Single Point of Failure][feat-1]
|
||||
* [Insert with your own keys][feat-2]
|
||||
* [Chunking large files][feat-3]
|
||||
* [Collection as a Simple Name Space][feat-4]
|
||||
|
||||
[feat-1]: https://github.com/seaweedfs/seaweedfs/wiki/Failover-Master-Server
|
||||
[feat-2]: https://github.com/seaweedfs/seaweedfs/wiki/Optimization#insert-with-your-own-keys
|
||||
[feat-3]: https://github.com/seaweedfs/seaweedfs/wiki/Optimization#upload-large-files
|
||||
[feat-4]: https://github.com/seaweedfs/seaweedfs/wiki/Optimization#collection-as-a-simple-name-space
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## Blob Store Architecture ##
|
||||
|
||||
Usually distributed file systems split each file into chunks. A central server keeps a mapping of filenames to chunks, and also which chunks each chunk server has.
|
||||
|
||||
The main drawback is that the central server can't handle many small files efficiently, and since all read requests need to go through the central master, so it might not scale well for many concurrent users.
|
||||
|
||||
Instead of managing chunks, SeaweedFS manages data volumes in the master server. Each data volume is 32GB in size, and can hold a lot of blobs. And each storage node can have many data volumes. So the master node only needs to store the metadata about the volumes, which is a fairly small amount of data and is generally stable.
|
||||
|
||||
The actual blob metadata, which are the blob volume, offset, and size, is stored in each volume on volume servers. Since each volume server only manages metadata of blobs on its own disk, with only 16 bytes for each blob, all access can read the metadata just from memory and only needs one disk operation to actually read file data.
|
||||
|
||||
For comparison, consider that an xfs inode structure in Linux is 536 bytes.
|
||||
|
||||
### Master Server and Volume Server ###
|
||||
|
||||
The architecture is fairly simple. The actual data is stored in volumes on storage nodes. One volume server can have multiple volumes, and can both support read and write access with basic authentication.
|
||||
|
||||
All volumes are managed by a master server. The master server contains the volume id to volume server mapping. This is fairly static information, and can be easily cached.
|
||||
|
||||
On each write request, the master server also generates a file key, which is a growing 64-bit unsigned integer. Since write requests are not generally as frequent as read requests, one master server should be able to handle the concurrency well.
|
||||
|
||||
### Write and Read files ###
|
||||
|
||||
When a client sends a write request, the master server returns (volume id, file key, file cookie, volume node URL) for the blob. The client then contacts the volume node and POSTs the blob content.
|
||||
|
||||
When a client needs to read a blob based on (volume id, file key, file cookie), it asks the master server by the volume id for the (volume node URL, volume node public URL), or retrieves this from a cache. Then the client can GET the content, or just render the URL on web pages and let browsers fetch the content.
|
||||
|
||||
### Saving memory ###
|
||||
|
||||
All blob metadata stored on a volume server is readable from memory without disk access. Each file takes just a 16-byte map entry of <64bit key, 32bit offset, 32bit size>. Of course, each map entry has its own space cost for the map. But usually the disk space runs out before the memory does.
|
||||
|
||||
### Tiered Storage to the cloud ###
|
||||
|
||||
The local volume servers are much faster, while cloud storages have elastic capacity and are actually more cost-efficient if not accessed often (usually free to upload, but relatively costly to access). With the append-only structure and O(1) access time, SeaweedFS can take advantage of both local and cloud storage by offloading the warm data to the cloud.
|
||||
|
||||
Usually hot data are fresh and warm data are old. SeaweedFS puts the newly created volumes on local servers, and optionally upload the older volumes on the cloud. If the older data are accessed less often, this literally gives you unlimited capacity with limited local servers, and still fast for new data.
|
||||
|
||||
With the O(1) access time, the network latency cost is kept at minimum.
|
||||
|
||||
If the hot/warm data is split as 20/80, with 20 servers, you can achieve storage capacity of 100 servers. That's a cost saving of 80%! Or you can repurpose the 80 servers to store new data also, and get 5X storage throughput.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## SeaweedFS Filer ##
|
||||
|
||||
Built on top of the blob store, SeaweedFS Filer adds directory structure to create a file system. The directory sturcture is an interface that is implemented in many key-value stores or databases.
|
||||
|
||||
The content of a file is mapped to one or many blobs, distributed to multiple volumes on multiple volume servers.
|
||||
|
||||
## Compared to Other File Systems ##
|
||||
|
||||
Most other distributed file systems seem more complicated than necessary.
|
||||
|
||||
@@ -271,7 +437,9 @@ SeaweedFS is meant to be fast and simple, in both setup and operation. If you do
|
||||
|
||||
SeaweedFS is constantly moving forward. Same with other systems. These comparisons can be outdated quickly. Please help to keep them updated.
|
||||
|
||||
## Compared to HDFS ##
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
### Compared to HDFS ###
|
||||
|
||||
HDFS uses the chunk approach for each file, and is ideal for storing large files.
|
||||
|
||||
@@ -279,7 +447,9 @@ SeaweedFS is ideal for serving relatively smaller files quickly and concurrently
|
||||
|
||||
SeaweedFS can also store extra large files by splitting them into manageable data chunks, and store the file ids of the data chunks into a meta chunk. This is managed by "weed upload/download" tool, and the weed master or volume servers are agnostic about it.
|
||||
|
||||
## Compared to GlusterFS, Ceph ##
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
### Compared to GlusterFS, Ceph ###
|
||||
|
||||
The architectures are mostly the same. SeaweedFS aims to store and read files fast, with a simple and flat architecture. The main differences are
|
||||
|
||||
@@ -295,18 +465,27 @@ The architectures are mostly the same. SeaweedFS aims to store and read files fa
|
||||
| GlusterFS | hashing | | FUSE, NFS | | |
|
||||
| Ceph | hashing + rules | | FUSE | Yes | |
|
||||
| MooseFS | in memory | | FUSE | | No |
|
||||
| MinIO | separate meta file per drive for each file | | | Yes | No |
|
||||
| RustFS | separate meta file per drive for each file | | | Yes | No |
|
||||
| MinIO | separate meta file for each file | | | Yes | No |
|
||||
|
||||
GlusterFS stores files, both directories and content, in configurable volumes called "bricks". It hashes the path and filename into ids, and assigned to virtual volumes, and then mapped to "bricks".
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## Compared to MooseFS ##
|
||||
### Compared to GlusterFS ###
|
||||
|
||||
GlusterFS stores files, both directories and content, in configurable volumes called "bricks".
|
||||
|
||||
GlusterFS hashes the path and filename into ids, and assigned to virtual volumes, and then mapped to "bricks".
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
### Compared to MooseFS ###
|
||||
|
||||
MooseFS chooses to neglect small file issue. From moosefs 3.0 manual, "even a small file will occupy 64KiB plus additionally 4KiB of checksums and 1KiB for the header", because it "was initially designed for keeping large amounts (like several thousands) of very big files"
|
||||
|
||||
MooseFS Master Server keeps all meta data in memory. Same issue as HDFS namenode.
|
||||
MooseFS Master Server keeps all meta data in memory. Same issue as HDFS namenode.
|
||||
|
||||
## Compared to Ceph ##
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
### Compared to Ceph ###
|
||||
|
||||
Ceph can be setup similar to SeaweedFS as a key->blob store. It is much more complicated, with the need to support layers on top of it. [Here is a more detailed comparison](https://github.com/seaweedfs/seaweedfs/issues/120)
|
||||
|
||||
@@ -326,39 +505,132 @@ SeaweedFS Filer uses off-the-shelf stores, such as MySql, Postgres, Sqlite, Mong
|
||||
| Volume | OSD | optimized for small files |
|
||||
| Filer | Ceph FS | linearly scalable, Customizable, O(1) or O(logN) |
|
||||
|
||||
## Compared to MinIO, RustFS ##
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
Please note, as Apr 25, 2026 MinIO ceased development. It's strongly discouraged to use that unmaintained software with multiple security bugs. RustFS is a MinIO reimplementation in Rust, Apache 2.0 licensed and still developed, keeping MinIO's storage model down to a byte-compatible on-disk format. So the points below apply to both.
|
||||
### Compared to MinIO ###
|
||||
|
||||
MinIO followed AWS S3 closely and was ideal for testing for S3 API. It had good UI, policies, versionings, etc. SeaweedFS is trying to catch up here.
|
||||
MinIO follows AWS S3 closely and is ideal for testing for S3 API. It has good UI, policies, versionings, etc. SeaweedFS is trying to catch up here. It is also possible to put MinIO as a gateway in front of SeaweedFS later.
|
||||
|
||||
The metadata are in simple files. Each file write incurs extra writes to the corresponding meta file, on every drive of the erasure set. Changing only tags or retention rewrites that meta file on all of them, so the write amplification does not shrink with object size.
|
||||
MinIO metadata are in simple files. Each file write will incur extra writes to corresponding meta file.
|
||||
|
||||
There is no optimization for lots of small files. The files are simply stored as is to local disks.
|
||||
MinIO does not have optimization for lots of small files. The files are simply stored as is to local disks.
|
||||
Plus the extra meta file and shards for erasure coding, it only amplifies the LOSF problem.
|
||||
|
||||
Multiple disk IO are needed to read one file. SeaweedFS has O(1) disk reads, even for erasure coded files.
|
||||
MinIO has multiple disk IO to read one file. SeaweedFS has O(1) disk reads, even for erasure coded files.
|
||||
|
||||
Erasure coding is full-time. SeaweedFS uses replication on hot data for faster speed and optionally applies erasure coding on warm data.
|
||||
MinIO has full-time erasure coding. SeaweedFS uses replication on hot data for faster speed and optionally applies erasure coding on warm data.
|
||||
|
||||
No POSIX-like API support.
|
||||
MinIO does not have POSIX-like API support.
|
||||
|
||||
There are specific requirements on storage layout, which makes it hard to scale out and to maintain. An erasure set must be 2 to 16 drives and must divide the drive list symmetrically, and capacity grows or shrinks a whole pool at a time. In SeaweedFS, just start one volume server pointing to the master. That's all.
|
||||
MinIO has specific requirements on storage layout. It is not flexible to adjust capacity. In SeaweedFS, just start one volume server pointing to the master. That's all.
|
||||
|
||||
## Dev Plan ##
|
||||
|
||||
* More tools and documentation, on how to manage and scale the system.
|
||||
* Read and write stream data.
|
||||
* Support structured data.
|
||||
|
||||
This is a super exciting project! And we need helpers and [support](https://www.patreon.com/seaweedfs)!
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# Benchmark #
|
||||
## Installation Guide ##
|
||||
|
||||
Unscientific single-machine numbers from a MacBook with an SSD. [`weed benchmark`][Benchmarks], 1 million 1KB files, concurrency 16:
|
||||
> Installation guide for users who are not familiar with golang
|
||||
|
||||
| | Requests per second | p50 | p99 |
|
||||
| --- | --- | --- | --- |
|
||||
| Write | 15,708 | 0.8 ms | 2.6 ms |
|
||||
| Random read | 47,019 | 0.3 ms | 0.7 ms |
|
||||
Step 1: install go on your machine and setup the environment by following the instructions at:
|
||||
|
||||
`make benchmark` runs [warp][S3Benchmark] mixed S3 traffic against a local `weed server`:
|
||||
https://golang.org/doc/install
|
||||
|
||||
make sure to define your $GOPATH
|
||||
|
||||
|
||||
Step 2: checkout this repo:
|
||||
```bash
|
||||
git clone https://github.com/seaweedfs/seaweedfs.git
|
||||
```
|
||||
Step 3: download, compile, and install the project by executing the following command
|
||||
|
||||
```bash
|
||||
cd seaweedfs/weed && make install
|
||||
```
|
||||
|
||||
Once this is done, you will find the executable "weed" in your `$GOPATH/bin` directory
|
||||
|
||||
For more installation options, including how to run with Docker, see the [Getting Started guide](https://github.com/seaweedfs/seaweedfs/wiki/Getting-Started).
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## Disk Related Topics ##
|
||||
|
||||
### Hard Drive Performance ###
|
||||
|
||||
When testing read performance on SeaweedFS, it basically becomes a performance test of your hard drive's random read speed. Hard drives usually get 100MB/s~200MB/s.
|
||||
|
||||
### Solid State Disk ###
|
||||
|
||||
To modify or delete small files, SSD must delete a whole block at a time, and move content in existing blocks to a new block. SSD is fast when brand new, but will get fragmented over time and you have to garbage collect, compacting blocks. SeaweedFS is friendly to SSD since it is append-only. Deletion and compaction are done on volume level in the background, not slowing reading and not causing fragmentation.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## Benchmark ##
|
||||
|
||||
My Own Unscientific Single Machine Results on Mac Book with Solid State Disk, CPU: 1 Intel Core i7 2.6GHz.
|
||||
|
||||
Write 1 million 1KB file:
|
||||
```
|
||||
Concurrency Level: 16
|
||||
Time taken for tests: 66.753 seconds
|
||||
Completed requests: 1048576
|
||||
Failed requests: 0
|
||||
Total transferred: 1106789009 bytes
|
||||
Requests per second: 15708.23 [#/sec]
|
||||
Transfer rate: 16191.69 [Kbytes/sec]
|
||||
|
||||
Connection Times (ms)
|
||||
min avg max std
|
||||
Total: 0.3 1.0 84.3 0.9
|
||||
|
||||
Percentage of the requests served within a certain time (ms)
|
||||
50% 0.8 ms
|
||||
66% 1.0 ms
|
||||
75% 1.1 ms
|
||||
80% 1.2 ms
|
||||
90% 1.4 ms
|
||||
95% 1.7 ms
|
||||
98% 2.1 ms
|
||||
99% 2.6 ms
|
||||
100% 84.3 ms
|
||||
```
|
||||
|
||||
Randomly read 1 million files:
|
||||
```
|
||||
Concurrency Level: 16
|
||||
Time taken for tests: 22.301 seconds
|
||||
Completed requests: 1048576
|
||||
Failed requests: 0
|
||||
Total transferred: 1106812873 bytes
|
||||
Requests per second: 47019.38 [#/sec]
|
||||
Transfer rate: 48467.57 [Kbytes/sec]
|
||||
|
||||
Connection Times (ms)
|
||||
min avg max std
|
||||
Total: 0.0 0.3 54.1 0.2
|
||||
|
||||
Percentage of the requests served within a certain time (ms)
|
||||
50% 0.3 ms
|
||||
90% 0.4 ms
|
||||
98% 0.6 ms
|
||||
99% 0.7 ms
|
||||
100% 54.1 ms
|
||||
```
|
||||
|
||||
### Run WARP and launch a mixed benchmark. ###
|
||||
|
||||
```
|
||||
make benchmark
|
||||
warp: Benchmark data written to "warp-mixed-2025-12-05[194844]-kBpU.csv.zst"
|
||||
|
||||
Mixed operations.
|
||||
Operation: DELETE, 10%, Concurrency: 20, Ran 42s.
|
||||
* Throughput: 55.13 obj/s
|
||||
@@ -375,19 +647,16 @@ Operation: STAT, 30%, Concurrency: 20, Ran 42s.
|
||||
Cluster Total: 3302.88 MiB/s, 550.51 obj/s over 43s.
|
||||
```
|
||||
|
||||
Read throughput is bounded by the random read speed of the disks, and grows with every volume server added. More numbers, including multi-node, FUSE, and Hadoop, are in [Benchmarks][Benchmarks], [S3 API Benchmark][S3Benchmark], [FIO benchmark][FIO], and [Independent Benchmarks][IndependentBenchmarks].
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## Enterprise ##
|
||||
|
||||
For enterprise users, please visit [seaweedfs.com](https://seaweedfs.com) for the SeaweedFS Enterprise Edition,
|
||||
which has a self-healing storage format with better data protection.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# Enterprise #
|
||||
|
||||
For enterprise users, please visit [seaweedfs.com](https://seaweedfs.com) for the SeaweedFS Enterprise Edition,
|
||||
which has advanced features, including data recovery, self-healing storage,
|
||||
customizable erasure coding, EC vacuum and repair, etc.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# License #
|
||||
## License ##
|
||||
|
||||
Licensed under the Apache License, Version 2.0 (the "License");
|
||||
you may not use this file except in compliance with the License.
|
||||
@@ -401,114 +670,9 @@ WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
See the License for the specific language governing permissions and
|
||||
limitations under the License.
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
# Sponsors #
|
||||
|
||||
<h3 align="center"><a href="https://www.patreon.com/seaweedfs">Sponsor SeaweedFS via Patreon</a></h3>
|
||||
|
||||
SeaweedFS is an independent Apache-licensed open source project with its ongoing development made
|
||||
possible entirely thanks to the support of these awesome [backers](https://github.com/seaweedfs/seaweedfs/blob/master/backers.md).
|
||||
If you'd like to grow SeaweedFS even stronger, please consider joining our
|
||||
<a href="https://www.patreon.com/seaweedfs">sponsors on Patreon</a>.
|
||||
|
||||
Your support will be really appreciated by me and other supporters!
|
||||
|
||||
<!--
|
||||
<h4 align="center">Platinum</h4>
|
||||
|
||||
<p align="center">
|
||||
<a href="" target="_blank">
|
||||
<img src="https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/note/sponsor_nodion.png" width="200" alt="nodion">
|
||||
</a>
|
||||
</p>
|
||||
-->
|
||||
|
||||
### Gold Sponsors
|
||||
[](https://www.nodion.com)
|
||||
[](https://www.piknik.com)
|
||||
[](https://www.keepsec.ca)
|
||||
[](https://zyner.org)
|
||||
The text of this page is available for modification and reuse under the terms of the Creative Commons Attribution-Sharealike 3.0 Unported License and the GNU Free Documentation License (unversioned, with no invariant sections, front-cover texts, or back-cover texts).
|
||||
|
||||
[Back to TOC](#table-of-contents)
|
||||
|
||||
## Star History
|
||||
|
||||

|
||||
|
||||
[WeedMini]: https://github.com/seaweedfs/seaweedfs/wiki/Quick-Start-with-weed-mini
|
||||
[DockerComposeS3]: https://github.com/seaweedfs/seaweedfs/wiki/Docker-Compose-for-S3
|
||||
[HelmRecipes]: https://github.com/seaweedfs/seaweedfs/wiki/Helm-Chart-Recipes
|
||||
[Operator]: https://github.com/seaweedfs/seaweedfs-operator
|
||||
[SeaweedFsCsiDriver]: https://github.com/seaweedfs/seaweedfs-csi-driver
|
||||
[GettingStarted]: https://github.com/seaweedfs/seaweedfs/wiki/Getting-Started
|
||||
[ProductionSetup]: https://github.com/seaweedfs/seaweedfs/wiki/Production-Setup
|
||||
[ErasureCoding]: https://github.com/seaweedfs/seaweedfs/wiki/Erasure-Coding-for-warm-storage
|
||||
[RustVolume]: https://github.com/seaweedfs/seaweedfs/wiki/Rust-Volume-Server
|
||||
[Benchmarks]: https://github.com/seaweedfs/seaweedfs/wiki/Benchmarks
|
||||
[S3Benchmark]: https://github.com/seaweedfs/seaweedfs/wiki/S3-API-Benchmark
|
||||
[FIO]: https://github.com/seaweedfs/seaweedfs/wiki/FIO-benchmark
|
||||
[IndependentBenchmarks]: https://github.com/seaweedfs/seaweedfs/wiki/Independent-Benchmarks
|
||||
[FailoverMaster]: https://github.com/seaweedfs/seaweedfs/wiki/Failover-Master-Server
|
||||
[WeedShell]: https://github.com/seaweedfs/seaweedfs/wiki/weed-shell
|
||||
[Worker]: https://github.com/seaweedfs/seaweedfs/wiki/Worker
|
||||
[FilerStores]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Stores
|
||||
[Replication]: https://github.com/seaweedfs/seaweedfs/wiki/Replication
|
||||
[TieredStorage]: https://github.com/seaweedfs/seaweedfs/wiki/Tiered-Storage
|
||||
[CloudTier]: https://github.com/seaweedfs/seaweedfs/wiki/Cloud-Tier
|
||||
[SuperLargeFiles]: https://github.com/seaweedfs/seaweedfs/wiki/Data-Structure-for-Large-Files
|
||||
[Versioning]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Object-Versioning
|
||||
[ObjectLock]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Object-Lock-and-Retention
|
||||
[Lifecycle]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Lifecycle
|
||||
[CORS]: https://github.com/seaweedfs/seaweedfs/wiki/S3-CORS
|
||||
[ConditionalOps]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Conditional-Operations
|
||||
[RenameObject]: https://github.com/seaweedfs/seaweedfs/wiki/S3-RenameObject
|
||||
[BucketPolicies]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Bucket-Policies
|
||||
[PolicyConditions]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Policy-Conditions
|
||||
[PolicyVariables]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Policy-Variables
|
||||
[OIDC]: https://github.com/seaweedfs/seaweedfs/wiki/OIDC-Integration
|
||||
[K8sSA]: https://github.com/seaweedfs/seaweedfs/wiki/Kubernetes-ServiceAccount-Authentication
|
||||
[SSE]: https://github.com/seaweedfs/seaweedfs/wiki/Server-Side-Encryption
|
||||
[AuditLog]: https://github.com/seaweedfs/seaweedfs/wiki/S3-API-Audit-log
|
||||
[BucketQuota]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Bucket-Quota
|
||||
[RateLimiting]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Rate-Limiting
|
||||
[AmazonS3API]: https://github.com/seaweedfs/seaweedfs/wiki/Amazon-S3-API
|
||||
[S3vsMinio]: https://github.com/seaweedfs/seaweedfs/wiki/Supported-APIs-vs-Minio
|
||||
[S3TableBucket]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Table-Bucket
|
||||
[LanceCatalog]: https://github.com/seaweedfs/seaweedfs/wiki/SeaweedFS-Lance-Catalog
|
||||
[IcebergCatalog]: https://github.com/seaweedfs/seaweedfs/wiki/SeaweedFS-Iceberg-Catalog
|
||||
[SparkIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Spark-Iceberg-Integration
|
||||
[TrinoIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Trino-Iceberg-Integration
|
||||
[DremioIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Dremio-Iceberg-Integration
|
||||
[DuckDBIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/DuckDB-Iceberg-Integration
|
||||
[DorisIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/Doris-Iceberg-Integration
|
||||
[RisingWaveIceberg]: https://github.com/seaweedfs/seaweedfs/wiki/RisingWave-Iceberg-Integration
|
||||
[LanceDB]: https://github.com/seaweedfs/seaweedfs/wiki/LanceDB-Integration
|
||||
[Lakekeeper]: https://github.com/seaweedfs/seaweedfs/wiki/Lakekeeper-Iceberg-Integration
|
||||
[IcebergMaintenance]: https://github.com/seaweedfs/seaweedfs/wiki/Iceberg-Table-Maintenance
|
||||
[LanceMaintenance]: https://github.com/seaweedfs/seaweedfs/wiki/Lance-Maintenance-Worker
|
||||
[S3TablesSecurity]: https://github.com/seaweedfs/seaweedfs/wiki/S3-Tables-Security
|
||||
[Hadoop]: https://github.com/seaweedfs/seaweedfs/wiki/Hadoop-Compatible-File-System
|
||||
[CloudDrive]: https://github.com/seaweedfs/seaweedfs/wiki/Cloud-Drive-Architecture
|
||||
[CacheRemote]: https://github.com/seaweedfs/seaweedfs/wiki/Cache-Remote-Storage
|
||||
[GatewayToRemoteObjectStore]: https://github.com/seaweedfs/seaweedfs/wiki/Gateway-to-Remote-Object-Storage
|
||||
[ActiveActiveAsyncReplication]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Active-Active-cross-cluster-continuous-synchronization
|
||||
[FilerStoreReplication]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Store-Replication
|
||||
[AsyncBackup]: https://github.com/seaweedfs/seaweedfs/wiki/Async-Backup
|
||||
[MetaBackup]: https://github.com/seaweedfs/seaweedfs/wiki/Async-Filer-Metadata-Backup
|
||||
[CDC]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Change-Data-Capture
|
||||
[Webhook]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Notification-Webhook
|
||||
[Mount]: https://github.com/seaweedfs/seaweedfs/wiki/FUSE-Mount
|
||||
[MountWindows]: https://github.com/seaweedfs/seaweedfs/wiki/Mount-on-Windows
|
||||
[WebDAV]: https://github.com/seaweedfs/seaweedfs/wiki/WebDAV
|
||||
[SFTP]: https://github.com/seaweedfs/seaweedfs/wiki/SFTP-Server
|
||||
[TUS]: https://github.com/seaweedfs/seaweedfs/wiki/TUS-Resumable-Uploads
|
||||
[FilerDataEncryption]: https://github.com/seaweedfs/seaweedfs/wiki/Filer-Data-Encryption
|
||||
[FIPS]: https://github.com/seaweedfs/seaweedfs/wiki/Cryptography-and-FIPS-Compliance
|
||||
[AdminUI]: https://github.com/seaweedfs/seaweedfs/wiki/Admin-UI
|
||||
[Metrics]: https://github.com/seaweedfs/seaweedfs/wiki/System-Metrics
|
||||
[VolumeServerTTL]: https://github.com/seaweedfs/seaweedfs/wiki/Store-file-with-a-Time-To-Live
|
||||
[SeaweedUp]: https://github.com/seaweedfs/seaweedfs/wiki/Deployment-with-seaweed-up
|
||||
[BlobStoreArchitecture]: https://github.com/seaweedfs/seaweedfs/wiki/Blob-Store-Architecture
|
||||
[Components]: https://github.com/seaweedfs/seaweedfs/wiki/Components
|
||||
[WhitePaper]: https://github.com/seaweedfs/seaweedfs/wiki/SeaweedFS_Architecture.pdf
|
||||
## Stargazers over time
|
||||
[](https://starchart.cc/seaweedfs/seaweedfs)
|
||||
|
||||
-344
@@ -1,344 +0,0 @@
|
||||
# SeaweedFS HTTP REST API
|
||||
|
||||
SeaweedFS exposes three HTTP surfaces:
|
||||
|
||||
| Service | Default port | Addressing |
|
||||
|---------|--------------|------------|
|
||||
| Filer | 8888 | File system paths (`/dir/name`) |
|
||||
| Master | 9333 | File id assignment and cluster topology |
|
||||
| Volume server | 8080 | File content by file id (`vid,fid`) |
|
||||
|
||||
Most clients only need the filer API (paths) or the S3 API. The master and
|
||||
volume APIs are the lower-level blob store interface.
|
||||
|
||||
Conventions applying to all three:
|
||||
|
||||
- Responses are JSON unless noted otherwise. Append `&pretty=y` to pretty-print.
|
||||
- A file id (`fid`) has the form `volumeId,fileKeyCookie`, e.g. `3,01637037d6`.
|
||||
An optional suffix selects a reserved id from a `count` assignment
|
||||
(`3,01637037d6_1`, `_2`, ...), and an optional extension
|
||||
(`3,01637037d6.jpg`) sets the content type on reads.
|
||||
- `replication` is a 3-digit replica placement `xyz`: `x` copies in other
|
||||
data centers, `y` on other racks in the same data center, `z` on other
|
||||
volume servers on the same rack. `000` = no replication, `001` = one copy
|
||||
on the same rack, `010` = one copy on a different rack, `100` = one copy in
|
||||
another data center, `200` = two copies in two other data centers, `110` =
|
||||
one copy in another data center plus one on another rack.
|
||||
- `ttl` units: `m` minute, `h` hour, `d` day, `w` week, `M` month, `y` year.
|
||||
|
||||
## Filer API (port 8888)
|
||||
|
||||
The filer presents a POSIX-like namespace over the volume servers.
|
||||
|
||||
### Upload a file
|
||||
|
||||
```bash
|
||||
# PUT the raw body to the target path
|
||||
curl -T /home/chris/myphoto.jpg "http://localhost:8888/dir/myphoto.jpg"
|
||||
|
||||
# or POST as multipart form (the part filename becomes the entry name)
|
||||
curl -F file=@/home/chris/myphoto.jpg "http://localhost:8888/dir/"
|
||||
```
|
||||
|
||||
Response `201 Created`:
|
||||
|
||||
```json
|
||||
{"name":"myphoto.jpg","size":43234,"eTag":"0x6c656...","mtime":"...","chunks":[...]}
|
||||
```
|
||||
|
||||
Query parameters:
|
||||
|
||||
| Parameter | Description | Default |
|
||||
|-----------|-------------|---------|
|
||||
| `collection` | collection name | empty |
|
||||
| `replication` | replica placement code | filer default |
|
||||
| `ttl` | file expiration, e.g. `3d` | never |
|
||||
| `disk` | disk type to store on | filer default |
|
||||
| `fsync` | `true` fsyncs on the volume server | false |
|
||||
| `dataCenter` | preferred data center | empty |
|
||||
| `rack` | preferred rack | empty |
|
||||
| `dataNode` | preferred volume server | empty |
|
||||
| `saveInside` | store small content inside the metadata instead of a volume | false |
|
||||
| `maxMB` | split the upload into chunks of this many MB | filer `-maxMB` |
|
||||
| `mode` | unix permission bits, e.g. `0644` | `0660` |
|
||||
| `op` | `append` appends to an existing file | overwrite |
|
||||
| `skipCheckParentDir` | `true` skips the parent-directory existence check | false |
|
||||
|
||||
### Create a directory
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:8888/dir/newdir/"
|
||||
```
|
||||
|
||||
A POST to a path ending in `/` with no content creates the directory,
|
||||
including missing parents.
|
||||
|
||||
### Read a file
|
||||
|
||||
```bash
|
||||
curl "http://localhost:8888/dir/myphoto.jpg"
|
||||
```
|
||||
|
||||
Supports `Range` requests (`Accept-Ranges: bytes`), `ETag`, and the
|
||||
`If-None-Match` / `If-Modified-Since` conditional headers. `HEAD` returns
|
||||
headers only. Entry headers stored as extended attributes are echoed back,
|
||||
minus internal `Seaweed-` and `xattr-` keys.
|
||||
|
||||
Entry metadata instead of content:
|
||||
|
||||
```bash
|
||||
curl "http://localhost:8888/dir/myphoto.jpg?metadata=true"
|
||||
```
|
||||
|
||||
`metadata=true&resolveManifest=true` additionally resolves chunked-manifest
|
||||
entries into their real chunk list.
|
||||
|
||||
### List a directory
|
||||
|
||||
```bash
|
||||
curl -H "Accept: application/json" "http://localhost:8888/dir/?limit=10&lastFileName=a.jpg"
|
||||
```
|
||||
|
||||
| Parameter | Description | Default |
|
||||
|-----------|-------------|---------|
|
||||
| `limit` | max entries per page | filer `-dirListLimit` |
|
||||
| `lastFileName` | resume listing after this entry name | empty |
|
||||
| `namePattern` | include only names matching the wildcard | empty |
|
||||
| `namePatternExclude` | exclude names matching the wildcard | empty |
|
||||
|
||||
The JSON response carries `Path`, `Entries`, `Limit`, `LastFileName`,
|
||||
`ShouldDisplayLoadMore`, and `EmptyFolder`. Without the `Accept` header the
|
||||
filer renders its HTML browser.
|
||||
|
||||
### Move and copy
|
||||
|
||||
```bash
|
||||
curl -X POST "http://localhost:8888/dir/newname.jpg?mv.from=/dir/myphoto.jpg"
|
||||
curl -X POST "http://localhost:8888/dir/copy.jpg?cp.from=/dir/myphoto.jpg"
|
||||
```
|
||||
|
||||
`mv.from` renames or moves the source to the request path (`204 No Content`).
|
||||
`cp.from` copies it.
|
||||
|
||||
### Append
|
||||
|
||||
```bash
|
||||
curl -T chunk2.bin "http://localhost:8888/dir/file.bin?op=append"
|
||||
```
|
||||
|
||||
### Delete
|
||||
|
||||
```bash
|
||||
curl -X DELETE "http://localhost:8888/dir/myphoto.jpg"
|
||||
curl -X DELETE "http://localhost:8888/dir/?recursive=true"
|
||||
```
|
||||
|
||||
| Parameter | Description | Default |
|
||||
|-----------|-------------|---------|
|
||||
| `recursive` | delete a non-empty directory tree | false; when the filer runs with `filer.options.recursive_delete=true`, deletes are recursive unless `recursive=false` |
|
||||
| `ignoreRecursiveError` | keep deleting remaining entries after an error | false |
|
||||
| `skipChunkDeletion` | remove only the metadata, keep volume data | false |
|
||||
|
||||
### Tagging
|
||||
|
||||
Tags are carried as `Seaweed-`-prefixed request headers, not query
|
||||
parameters; `?tagging` selects the tagging handler and `?tagging=K1,K2`
|
||||
lists the keys to remove. Header names are canonicalized on write
|
||||
(`Seaweed-k1` is stored as `Seaweed-K1`), and the delete list is matched
|
||||
case-sensitively against the stored names.
|
||||
|
||||
```bash
|
||||
curl -X PUT -H "Seaweed-k1: v1" -H "Seaweed-k2: v2" "http://localhost:8888/dir/file.jpg?tagging"
|
||||
curl -X DELETE "http://localhost:8888/dir/file.jpg?tagging=K1,K2"
|
||||
```
|
||||
|
||||
### Read by file id
|
||||
|
||||
```bash
|
||||
curl "http://localhost:8888/?proxyChunkId=3,01637037d6"
|
||||
```
|
||||
|
||||
The filer proxies the chunk read to the right volume server, so only the
|
||||
filer port needs to be exposed.
|
||||
|
||||
### Resumable uploads
|
||||
|
||||
The filer serves the [TUS protocol](https://tus.io/) for resumable uploads
|
||||
(`POST`, `PATCH`, `HEAD` on upload URLs). It is enabled by default at
|
||||
`/.tus`; `-tusBasePath` changes the endpoint base path.
|
||||
|
||||
### Health
|
||||
|
||||
`GET /healthz` and `GET /readyz` return `200 OK`.
|
||||
|
||||
## Master API (port 9333)
|
||||
|
||||
Write-affecting endpoints are automatically proxied to the current leader, so
|
||||
any master in the quorum can serve them.
|
||||
|
||||
### Assign a file id
|
||||
|
||||
```bash
|
||||
curl "http://localhost:9333/dir/assign?count=1&replication=001&collection=turbo&dataCenter=dc1&ttl=3d&disk=ssd"
|
||||
{"count":1,"fid":"3,01637037d6","url":"127.0.0.1:8080","publicUrl":"localhost:8080"}
|
||||
```
|
||||
|
||||
Upload the file content to `http://<url>/<fid>` afterwards. With `count>1`,
|
||||
use `<fid>_1`, `<fid>_2`, ... for the additional ids.
|
||||
|
||||
| Parameter | Description | Default |
|
||||
|-----------|-------------|---------|
|
||||
| `count` | file ids to reserve | 1 |
|
||||
| `collection` | collection name | empty |
|
||||
| `dataCenter` | preferred data center | empty |
|
||||
| `rack` | preferred rack | empty |
|
||||
| `dataNode` | preferred volume server | empty |
|
||||
| `replication` | replica placement | master `-defaultReplication` |
|
||||
| `ttl` | file expiration, e.g. `3d` | never |
|
||||
| `disk` | disk type | empty |
|
||||
| `dataSize` | expected file size in bytes | 0 |
|
||||
| `preallocate` | bytes to preallocate for new volumes | master `-volumePreallocate` |
|
||||
| `writableVolumeCount` | grow this many volumes when none are writable | master default |
|
||||
| `memoryMapMaxSizeMb` | memory-mapped file size (Windows) | 0 |
|
||||
|
||||
### Look up a volume or file id
|
||||
|
||||
```bash
|
||||
curl "http://localhost:9333/dir/lookup?volumeId=3"
|
||||
{"locations":[{"url":"localhost:8080","publicUrl":"localhost:8080"}]}
|
||||
```
|
||||
|
||||
| Parameter | Description | Default |
|
||||
|-----------|-------------|---------|
|
||||
| `volumeId` | volume id; a full `vid,fid` is accepted too | required |
|
||||
| `fileId` | like `volumeId`, but also returns a write JWT when security is on | empty |
|
||||
| `collection` | speeds up the lookup | empty |
|
||||
| `read` | `yes` generates a read JWT instead of a write JWT | empty |
|
||||
|
||||
### Store a file in one call
|
||||
|
||||
```bash
|
||||
curl -F file=@/home/chris/report.pdf "http://localhost:9333/submit?collection=turbo&replication=001"
|
||||
{"fileName":"report.pdf","fid":"3,01637037d6","fileUrl":"localhost:8080/3,01637037d6","size":43234,"eTag":"0x6c656..."}
|
||||
```
|
||||
|
||||
`POST /submit` accepts multipart file data plus the `dir/assign` placement
|
||||
parameters (`count`, `collection`, `dataCenter`, `rack`, `replication`,
|
||||
`ttl`, `disk`), assigns a file id, uploads to the volume server, and returns
|
||||
the result.
|
||||
|
||||
### Redirect to a file
|
||||
|
||||
```bash
|
||||
curl -v "http://localhost:9333/3,01637037d6"
|
||||
```
|
||||
|
||||
`GET /{fileId}` answers `308 Permanent Redirect` to a volume server holding
|
||||
the file, preserving the query string (e.g. image-resize parameters).
|
||||
|
||||
### Cluster status
|
||||
|
||||
```bash
|
||||
curl "http://localhost:9333/dir/status?pretty=y" # full topology tree
|
||||
curl "http://localhost:9333/vol/status?pretty=y" # every volume on every node
|
||||
curl "http://localhost:9333/collection/info?collection=turbo"
|
||||
curl "http://localhost:9333/collection/info?collection=turbo&detail=true"
|
||||
```
|
||||
|
||||
`collection/info` returns aggregated `TotalSize`, `FileCount`, `UsedSize`,
|
||||
`VolumeCount`; `detail=true` splits them per volume layout.
|
||||
|
||||
### Grow volumes
|
||||
|
||||
```bash
|
||||
curl "http://localhost:9333/vol/grow?count=4&replication=001&collection=turbo&ttl=5d&disk=ssd&dataCenter=dc1&rack=rack1"
|
||||
{"count":4}
|
||||
```
|
||||
|
||||
`count` is required; the placement parameters match `dir/assign`. One volume
|
||||
serves one write at a time, so pre-allocated volumes raise write concurrency.
|
||||
|
||||
### Vacuum deleted space
|
||||
|
||||
```bash
|
||||
curl "http://localhost:9333/vol/vacuum?garbageThreshold=0.4"
|
||||
```
|
||||
|
||||
| Parameter | Description | Default |
|
||||
|-----------|-------------|---------|
|
||||
| `garbageThreshold` | minimum deleted-bytes ratio before a volume is compacted | master `-garbageThreshold` (0.3) |
|
||||
|
||||
Vacuuming makes a volume read-only, copies live needles to a new volume, and
|
||||
swaps it in.
|
||||
|
||||
### Delete a collection
|
||||
|
||||
```bash
|
||||
curl "http://localhost:9333/col/delete?collection=benchmark"
|
||||
```
|
||||
|
||||
Deletes all volumes of the collection, including erasure-coded shards.
|
||||
`204 No Content` on success.
|
||||
|
||||
### Health
|
||||
|
||||
```bash
|
||||
curl -I "http://localhost:9333/healthz" # liveness
|
||||
curl -I "http://localhost:9333/readyz" # readiness
|
||||
curl "http://localhost:9333/" # web UI
|
||||
```
|
||||
|
||||
## Volume server API (port 8080)
|
||||
|
||||
The volume server stores file content by file id. Clients normally get the
|
||||
volume URL from `dir/assign` or `dir/lookup`.
|
||||
|
||||
### Upload
|
||||
|
||||
```bash
|
||||
curl -F file=@/home/chris/myphoto.jpg "http://127.0.0.1:8080/3,01637037d6"
|
||||
{"name":"myphoto.jpg","size":43234,"eTag":"0x6c656...","mime":"image/jpeg","contentMd5":"..."}
|
||||
```
|
||||
|
||||
PUT or POST the body (or a multipart `file` part) to `/{vid},{fid}`.
|
||||
`204 No Content` is returned when the content is unchanged. `?ts=<unix>`
|
||||
sets the stored modification time.
|
||||
|
||||
### Read
|
||||
|
||||
```bash
|
||||
curl "http://127.0.0.1:8080/3,01637037d6"
|
||||
curl "http://127.0.0.1:8080/3,01637037d6.jpg" # sets Content-Type from the extension
|
||||
```
|
||||
|
||||
Supports `Range` and `HEAD`. Image files can be resized server-side:
|
||||
|
||||
| Parameter | Description |
|
||||
|-----------|-------------|
|
||||
| `width`, `height` | resize bounds in pixels |
|
||||
| `mode` | `fit` (contain) or `fill` (cover); omitted resizes to `width`/`height` |
|
||||
| `crop_x1`, `crop_y1`, `crop_x2`, `crop_y2` | explicit crop rectangle |
|
||||
| `cm` | `false` returns the chunk-manifest blob instead of resolving it |
|
||||
| `readDeleted` | `true` reads soft-deleted needles |
|
||||
| `collection` | passed through redirects for the right volume |
|
||||
|
||||
### Delete
|
||||
|
||||
```bash
|
||||
curl -X DELETE "http://127.0.0.1:8080/3,01637037d6"
|
||||
{"size":43234}
|
||||
```
|
||||
|
||||
`?ts=<unix>` sets the deletion timestamp. Replicated volumes propagate the
|
||||
delete to every replica.
|
||||
|
||||
### Status
|
||||
|
||||
```bash
|
||||
curl "http://localhost:8080/status?pretty=y" # disk and volume inventory
|
||||
curl -I "http://localhost:8080/healthz" # liveness/readiness
|
||||
```
|
||||
|
||||
`OPTIONS` preflights answer CORS headers. When `-port.public` differs from
|
||||
`-port`, the volume server opens a separate read-only public listener on
|
||||
that port; `-publicUrl` sets the address it advertises to clients.
|
||||
File diff suppressed because it is too large
Load Diff
+15
-69
@@ -1,78 +1,24 @@
|
||||
# Security Policy
|
||||
|
||||
## Supported versions
|
||||
## Reporting a Vulnerability
|
||||
|
||||
Security fixes land in the latest release. Please reproduce against a recent
|
||||
release or `master` before reporting; issues that only reproduce on old,
|
||||
unsupported versions are not eligible for a fix or an advisory.
|
||||
If you find a security issue in SeaweedFS, please report it privately:
|
||||
|
||||
## Reporting a vulnerability
|
||||
- Email: support@seaweedfs.com
|
||||
- Do not open a public GitHub issue
|
||||
|
||||
Report privately through GitHub private vulnerability reporting (the "Report a
|
||||
vulnerability" button under the repository's Security tab). This keeps the
|
||||
report, the fix, and any CVE in one place. Do not open a public issue.
|
||||
Please include:
|
||||
- A clear description of the issue
|
||||
- Steps to reproduce (if possible)
|
||||
- Affected versions
|
||||
|
||||
### What a report must include
|
||||
## Response
|
||||
|
||||
We can only act on reports that show real impact. Please include:
|
||||
- We will respond as soon as possible (usually within 1 business day)
|
||||
- We will investigate and work on a fix
|
||||
- We may coordinate disclosure with you
|
||||
|
||||
- Affected version (a release tag or `master` commit you reproduced on)
|
||||
- The exact deployment and configuration: which components are running
|
||||
(master, volume, filer, S3, admin), which ports are reachable by the
|
||||
attacker, and what authentication is enabled
|
||||
- The attacker's starting position: unauthenticated, a valid S3 user, an admin,
|
||||
or someone with access to the internal cluster network
|
||||
- The trust boundary that is crossed (e.g. an unauthenticated client reading
|
||||
another tenant's data, an S3 user escalating to admin)
|
||||
- A minimal, working reproduction or proof of concept
|
||||
- Expected vs. actual behavior
|
||||
## Notes
|
||||
|
||||
A report without a working reproduction and a clear trust boundary is a
|
||||
hardening suggestion, not a vulnerability. We are glad to receive those, but
|
||||
they are handled on the normal issue tracker, not as security advisories.
|
||||
|
||||
### Automated and AI-assisted reports
|
||||
|
||||
Output from static analysis, dependency scanners, fuzzers, or LLMs is welcome
|
||||
only when you have manually validated it and can supply a working reproduction
|
||||
against a supported version, per the requirements above. Raw tool output,
|
||||
speculative findings, or generated reports without a demonstrated exploit will
|
||||
be closed as hardening suggestions.
|
||||
|
||||
## Trust model
|
||||
|
||||
SeaweedFS is built to run with its cluster components (master, volume servers,
|
||||
and the raw filer API) on a trusted network. Those internal APIs are not an
|
||||
authentication boundary unless you explicitly enable a control (for example
|
||||
volume JWT or filer authentication) and that control is bypassed. Exposing an
|
||||
internal port directly to untrusted clients is a deployment mistake, not a
|
||||
vulnerability in SeaweedFS.
|
||||
|
||||
Reports are in scope when they cross a boundary SeaweedFS is meant to enforce,
|
||||
for example:
|
||||
|
||||
- Unauthenticated access to data or operations that require authentication
|
||||
- One S3 identity reading, writing, or deleting another identity's data
|
||||
- Privilege escalation from a normal S3 user to administrative capability
|
||||
- Bypass of Object Lock / retention where it is configured
|
||||
- Remotely triggered data corruption or loss
|
||||
|
||||
Reports are generally out of scope when they require:
|
||||
|
||||
- Direct access to an internal cluster port that is meant to be private
|
||||
- Full master, filer, or volume server access (already a full compromise)
|
||||
- An insecure example configuration rather than a documented secure setup
|
||||
- Local-only impact on a host the attacker already controls
|
||||
|
||||
## CVE assignment
|
||||
|
||||
When a report is confirmed, we publish an advisory and request the CVE through
|
||||
GitHub. CVEs assigned by third parties without coordinating with us, or for
|
||||
issues that do not cross a boundary described above, may be disputed.
|
||||
|
||||
## Response and disclosure
|
||||
|
||||
- We aim to acknowledge a valid report within a few business days.
|
||||
- We will investigate, work on a fix, and coordinate a disclosure timeline
|
||||
with you.
|
||||
- Please allow time for a fix before any public disclosure.
|
||||
- Please allow time for a fix before public disclosure
|
||||
- If you’re unsure whether something is a security issue, feel free to reach out
|
||||
|
||||
@@ -1,167 +0,0 @@
|
||||
# Design: Serializing Bucket Configuration Mutations
|
||||
|
||||
Issue #9651 — concurrent `PutBucketVersioning` + `PutBucketEncryption` (as Terraform
|
||||
issues them in parallel) intermittently lose the encryption write.
|
||||
|
||||
## Root cause
|
||||
|
||||
The bucket's entire config lives in one filer entry, `/buckets/<name>`. Every
|
||||
config API does a read-modify-write of that single entry, and the writes are not
|
||||
serialized:
|
||||
|
||||
- `updateBucketConfig(bucket, fn)` (`s3api_bucket_config.go:468`) — sources from a
|
||||
possibly-stale cached `BucketConfig`, mutates `Entry.Extended`, writes the
|
||||
**whole** entry. Used by: versioning, object-lock config, lifecycle, ACL/owner.
|
||||
- `UpdateBucketMetadata` → `setBucketMetadata` (`:1042`) — reads a fresh entry,
|
||||
mutates `Entry.Content`, writes the **whole** entry. Used by: encryption, CORS,
|
||||
tagging, ownership, policy, notification.
|
||||
|
||||
Two ingredients produce the lost update:
|
||||
|
||||
1. **No serialization** of the read→modify→write (the cache mutexes only guard the
|
||||
in-memory map, not the RMW).
|
||||
2. **Whole-entry rewrite from an independent snapshot** — `updateBucketConfig`
|
||||
rebuilds from a stale cached `BucketConfig` whose `Content` predates the
|
||||
concurrent encryption write, so writing the whole entry reverts `Content`.
|
||||
|
||||
Sequential calls always pass (each sees the previous write), so it only surfaces
|
||||
under concurrency — and CI's slower IO widens the window (the "2 of ~12 runs").
|
||||
|
||||
## Goals
|
||||
|
||||
- No lost updates across concurrent bucket-config changes — for **all** config
|
||||
fields, not just versioning/encryption.
|
||||
- Correct for a single S3 gateway (the reported case) and for multiple gateways.
|
||||
- Reuse the filer primitives just merged (per-path lock, `WriteCondition`,
|
||||
`ObjectTransaction`); do not reintroduce a distributed lock.
|
||||
- Minimal blast radius: the fix lands at the two chokepoint helpers.
|
||||
|
||||
## Non-goals
|
||||
|
||||
- Changing the one-entry-per-bucket storage model.
|
||||
- Multi-filer-concurrent bucket writes (addressed only as an optional phase 3).
|
||||
|
||||
## The two ingredients map to two complementary fixes
|
||||
|
||||
### Fix A — serialize + read fresh (closes the window for whole-entry writers)
|
||||
|
||||
Both `updateBucketConfig` and `UpdateBucketMetadata` must run their RMW under one
|
||||
per-bucket critical section, and **re-read the entry fresh from the filer inside
|
||||
it** — not rebuild from the cached `BucketConfig`. The lock alone is insufficient:
|
||||
without the fresh read, two serialized writers still each apply a stale snapshot.
|
||||
|
||||
### Fix B — field-level updates (removes the collision entirely)
|
||||
|
||||
The two writers touch disjoint fields (`Extended[versioning]` vs `Content`). If
|
||||
each path updated only its own field instead of rewriting the whole entry, neither
|
||||
could clobber the other regardless of ordering. This is the structural fix and
|
||||
makes serialization a defense-in-depth concern rather than a correctness
|
||||
requirement for cross-field cases.
|
||||
|
||||
## Where to serialize (layering)
|
||||
|
||||
The bucket entry is a single filer entry, so unlike object writes there is no
|
||||
sharding — the question is purely the scope of the lock:
|
||||
|
||||
| Layer | Serializes across | Cost | Notes |
|
||||
|---|---|---|---|
|
||||
| 1. Gateway-local per-bucket lock | one gateway process | tiny | fixes the reported (single-gateway/CI) case |
|
||||
| 2. Filer per-path lock via conditional write | all gateways on one filer | small | reuses #9640 `CreateEntry`+`WriteCondition` |
|
||||
| 3. Route-by-key to bucket-key owner filer | all gateways and filers | medium | same mechanism as the object DLM-removal |
|
||||
|
||||
## Recommended plan (phased)
|
||||
|
||||
### Phase 1 — minimal fix for #9651 (gateway-local lock + fresh read)
|
||||
|
||||
Add a bounded per-bucket lock table to `S3ApiServer`, reusing the same
|
||||
`util.LockTable` the filer uses for its per-path lock:
|
||||
|
||||
```go
|
||||
// in S3ApiServer
|
||||
bucketConfigLocks *util.LockTable[string] // serialize bucket-entry RMW
|
||||
|
||||
func (s3a *S3ApiServer) withBucketConfigLock(bucket string, fn func() s3err.ErrorCode) s3err.ErrorCode {
|
||||
lk := s3a.bucketConfigLocks.AcquireLock("bucketConfig", bucket, util.ExclusiveLock)
|
||||
defer s3a.bucketConfigLocks.ReleaseLock(bucket, lk)
|
||||
return fn()
|
||||
}
|
||||
```
|
||||
|
||||
Wrap the RMW in **both** chokepoints, and inside the lock read the entry fresh:
|
||||
|
||||
- `updateBucketConfig`: acquire the lock; re-read `/buckets/<name>` from the filer
|
||||
(not the cache); rebuild `BucketConfig` from that fresh entry; apply `fn`; write;
|
||||
invalidate cache; release.
|
||||
- `UpdateBucketMetadata`/`setBucketMetadata`: same lock key; it already reads fresh,
|
||||
so it just needs to share the critical section.
|
||||
|
||||
Both must use the **same** lock keyed on `bucket`, so versioning and encryption
|
||||
contend on one mutex. This closes the reported window. Limitation: only one
|
||||
gateway; two gateways behind a load balancer still race.
|
||||
|
||||
Test: parallel `PutBucketVersioning` + `PutBucketEncryption`, assert both persist
|
||||
(the exact Terraform scenario), plus an N-way parallel variant over distinct
|
||||
fields.
|
||||
|
||||
### Phase 2 — robust across gateways (field-level + CAS via merged primitives)
|
||||
|
||||
Move the writers off whole-entry rewrites:
|
||||
|
||||
- **Extended-based config** (versioning, object-lock, ownership, tagging-in-Extended)
|
||||
→ `ObjectTransaction` `PATCH_EXTENDED` on `/buckets/<name>`. The owner filer reads
|
||||
the entry fresh under its per-path lock and merges only the named keys, so the
|
||||
gateway never sends a whole-entry snapshot — this dissolves *both* ingredients for
|
||||
these fields.
|
||||
- **`Content`-based config** (encryption, CORS, tags blob) — **chosen and
|
||||
implemented (b3): extend `PATCH_EXTENDED` with `set_content`.** Under the same
|
||||
per-path lock the filer reads the entry fresh, merges extended attributes, and
|
||||
replaces `Content`, preserving the rest. So a content write becomes a field-level
|
||||
patch too — `setBucketMetadata` patches `Content`, `updateBucketConfig` patches
|
||||
extended keys, and the two serialize on the lock instead of racing whole-entry
|
||||
rewrites. This is cleaner than the alternatives below: no client-side retry, no
|
||||
storage migration, and it reuses `ObjectTransaction`'s existing atomic lock.
|
||||
- (b1, rejected) Conditional `CreateEntry` overwrite with `IF_ETAG_MATCH` + retry
|
||||
(#9640): correct but needs client-side retry, and the bucket directory entry has
|
||||
no reliable ETag to compare on.
|
||||
- (b2, future) Migrate each per-feature config out of the single `Content` blob
|
||||
into its own `Extended` key. Then even *intra-blob* writes (tags vs encryption)
|
||||
stop racing. Larger migration; tracked separately.
|
||||
|
||||
Once all paths are field-level patches, the phase-1 gateway lock is unnecessary —
|
||||
the filer enforces atomicity. (This is the path taken: phase 1 was skipped.)
|
||||
|
||||
### Phase 3 — multi-filer (only if needed)
|
||||
|
||||
If multiple filers can write `/buckets/<name>` concurrently, a filer-local per-path
|
||||
lock no longer suffices. Route bucket-config writes to
|
||||
`PrimaryForKey("/buckets/<name>")` (the lock-ring view) and serialize on that one
|
||||
owner filer — the same route-by-key design used to take object writes off the DLM.
|
||||
Overkill for rare config writes; include only if multi-filer bucket writes are real.
|
||||
|
||||
## Correctness summary
|
||||
|
||||
- Phase 1: all RMW for a bucket serialize within a gateway; the fresh read means the
|
||||
second writer observes the first's change. Closes #9651 for single-gateway.
|
||||
- Phase 2: `PATCH_EXTENDED` is atomic field-level merge at the filer (no snapshot);
|
||||
CAS turns a concurrent `Content` write into a retry, enforced under the filer's
|
||||
per-path lock — correct for any number of gateways sharing a filer.
|
||||
- Phase 3: one owner filer serializes all writers — correct across filers too.
|
||||
|
||||
## Scope checklist (every path that RMWs the bucket entry)
|
||||
|
||||
All of these funnel through the two chokepoints, so fixing the chokepoints covers
|
||||
them — but the fix must not leave any of them on an unserialized path:
|
||||
|
||||
- via `updateBucketConfig`: versioning, object-lock config, lifecycle, ACL/owner.
|
||||
- via `UpdateBucketMetadata`/`setBucketMetadata`: encryption, CORS, tagging,
|
||||
ownership controls, bucket policy, notification.
|
||||
- bucket create/delete (`CreateEntry`/`DeleteEntry` of `/buckets/<name>`) already
|
||||
go through the filer's per-path lock on `CreateEntry`; ensure they take the same
|
||||
bucket lock if they also patch config.
|
||||
|
||||
## Cache rule (must document in code)
|
||||
|
||||
Under the lock, **read the entry from the filer, never rebuild from the cached
|
||||
`BucketConfig`**. The cache is for reads; it must be invalidated on every write and
|
||||
never be the source for an RMW. This is the single most important detail — the lock
|
||||
without the fresh read does not fix the bug.
|
||||
@@ -1,418 +0,0 @@
|
||||
# SeaweedFS as an Apache CloudStack Object Storage Provider
|
||||
|
||||
A CloudStack ObjectStore plugin that makes SeaweedFS a first-class object storage
|
||||
backend inside Apache CloudStack, alongside the existing MinIO and Ceph RGW
|
||||
providers. This is a collaboration with proIO (Swen), who builds private clouds on
|
||||
CloudStack and wants SeaweedFS as a storage option.
|
||||
|
||||
## The request
|
||||
|
||||
> We can only add MinIO and Ceph as object storage [in CloudStack] today. I want
|
||||
> to get SeaweedFS into this project... What we need is to build a provider which
|
||||
> does the communication between Cloudstack and SeaweedFS.
|
||||
|
||||
This is **not** a SeaweedFS-side feature. The work lives in the Apache CloudStack
|
||||
repo (Java): a new plugin under `plugins/storage/object/seaweedfs/` that implements
|
||||
CloudStack's ObjectStore plugin framework and talks to SeaweedFS over its S3 and
|
||||
IAM APIs. SeaweedFS itself needs no changes for the core to work — its S3 API
|
||||
already covers every bucket operation CloudStack requires, and its IAM API covers
|
||||
user/credential management.
|
||||
|
||||
## How the CloudStack ObjectStore framework works
|
||||
|
||||
CloudStack 4.18+ introduced an Object Storage framework. An admin registers an
|
||||
object storage pool via `addObjectStoragePool` (URL + provider + credentials);
|
||||
tenants then create and manage buckets on it through CloudStack APIs. CloudStack
|
||||
manages pool and bucket lifecycle; the underlying provider handles the actual
|
||||
object protocol.
|
||||
|
||||
A provider is a plugin module implementing three interfaces:
|
||||
|
||||
### 1. `ObjectStoreProvider` — registration
|
||||
|
||||
`MinIOObjectStoreProviderImpl` is the reference. It is a Spring `@Component` that:
|
||||
- Returns a provider name (`"MinIO"`)
|
||||
- Returns `DataStoreProviderType.OBJECT`
|
||||
- In `configure()`, injects the lifecycle and driver implementations and calls
|
||||
`storeMgr.registerDriver(name, driver)`
|
||||
|
||||
### 2. `ObjectStoreLifeCycle` — pool add/remove
|
||||
|
||||
`MinIOObjectStoreLifeCycleImpl.initialize()` reads the URL, name, and
|
||||
`accesskey`/`secretkey` details from the `addObjectStoragePool` call, tests the
|
||||
connection by listing buckets, and persists an `ObjectStoreVO` via
|
||||
`ObjectStoreHelper`. The other methods (attachCluster/Host/Zone, maintain,
|
||||
deleteDataStore) are no-ops for object storage.
|
||||
|
||||
### 3. `ObjectStoreDriver` — bucket + user operations
|
||||
|
||||
`ObjectStoreDriver` (in `engine/storage/.../object/ObjectStoreDriver.java`) extends
|
||||
`DataStoreDriver` and defines the bucket/user contract. Every provider must
|
||||
implement:
|
||||
|
||||
| Method | Purpose |
|
||||
| --- | --- |
|
||||
| `createBucket(Bucket, boolean objectLock)` | Create a bucket |
|
||||
| `listBuckets(long storeId)` | List all buckets |
|
||||
| `deleteBucket(BucketTO, long storeId)` | Delete a bucket |
|
||||
| `createUser(long accountId, long storeId)` | Provision a user + credentials for a CloudStack account |
|
||||
| `setBucketPolicy` / `getBucketPolicy` / `deleteBucketPolicy` | Bucket policy CRUD |
|
||||
| `setBucketEncryption` / `deleteBucketEncryption` | SSE config |
|
||||
| `setBucketVersioning` / `deleteBucketVersioning` | Versioning enable/suspend |
|
||||
| `setBucketQuota(BucketTO, long storeId, long size)` | Per-bucket quota |
|
||||
| `getAllBucketsUsage(long storeId)` | Usage map for billing/accounting |
|
||||
| `getBucketAcl` / `setBucketAcl` | ACLs (MinIO/Ceph return null / no-op) |
|
||||
|
||||
`BaseObjectStoreDriverImpl` provides no-op defaults for the `DataStoreDriver`
|
||||
methods (`createAsync`, `deleteAsync`, `copyAsync`, `canCopy`, `resize`,
|
||||
`getTO`, `getStoreTO`), so object-store providers only implement the bucket/user
|
||||
methods above.
|
||||
|
||||
## How the four existing providers differ (and where SeaweedFS lands)
|
||||
|
||||
CloudStack ships four object-store providers. Three are relevant; the simulator
|
||||
is a test stub.
|
||||
|
||||
| Concern | MinIO | Ceph RGW | Cloudian HyperStore | SeaweedFS |
|
||||
| --- | --- | --- | --- | --- |
|
||||
| Bucket CRUD | `MinioClient` (S3) | `AmazonS3` (AWS SDK v1) | `AmazonS3` (AWS SDK v1) | `AmazonS3` (AWS SDK v1) |
|
||||
| Bucket policy | `MinioClient` | `AmazonS3` | `AmazonS3` | `AmazonS3` |
|
||||
| Versioning | `MinioClient` | `AmazonS3` | `AmazonS3` | `AmazonS3` |
|
||||
| Encryption | `MinioClient` | not implemented | `AmazonS3` | `AmazonS3` |
|
||||
| **User creation** | `MinioAdminClient` | `RgwAdmin` | **`AmazonIdentityManagement`** | **`AmazonIdentityManagement`** |
|
||||
| **Per-bucket quota** | `MinioAdminClient` | `RgwAdmin` | **not supported** (throws) | **S3 extension** (`PUT /{bucket}?seaweedfs-quota`, SigV4, `s3:PutBucketQuota`) |
|
||||
| **Usage reporting** | `MinioAdminClient` | `RgwAdmin` | Cloudian admin API | S3 `ListObjectsV2` (MVP); Prometheus / SOSAPI `capacity.xml` (recommended) |
|
||||
|
||||
**Cloudian HyperStore is the direct precedent.** It is an S3-compatible store
|
||||
that, like SeaweedFS, manages users via the **standard AWS IAM API** using the
|
||||
AWS IAM Java SDK (`com.amazonaws.services.identitymanagement`). Its driver
|
||||
(`CloudianHyperStoreObjectStoreDriverImpl`) and util
|
||||
(`CloudianHyperStoreUtil`) are the template this design follows almost line for
|
||||
line. Cloudian even validates the quota limitation the same way this design
|
||||
proposes for the MVP: `setBucketQuota` throws for any non-zero size and only
|
||||
accepts `0` (no quota).
|
||||
|
||||
The SeaweedFS plugin is therefore a **simpler Cloudian** — same AWS S3 + IAM SDK
|
||||
clients, same store-details keys (`s3Url`, `iamUrl`, `accesskey`, `secretkey`),
|
||||
same IAM-user-with-restricted-policy pattern, but with no proprietary admin
|
||||
client at all (Cloudian has its own `CloudianClient` for its admin API; SeaweedFS
|
||||
needs only S3 + IAM). For quota, the plugin uses a narrow SeaweedFS S3 extension
|
||||
(see below); for usage reporting, it falls back to S3 `ListObjectsV2` in the MVP
|
||||
and recommends Prometheus or SOSAPI `capacity.xml` for production scale.
|
||||
|
||||
### Quota via the S3 `?seaweedfs-quota` extension
|
||||
|
||||
SeaweedFS supports bucket quota natively (server-side enforcement via a
|
||||
read-only flag when usage exceeds the limit). Rather than exposing the broad
|
||||
admin REST API (which would require a global bearer token and grant cluster-wide
|
||||
admin access), the integration uses a **narrow, scoped S3 subresource**:
|
||||
|
||||
- `PUT /{bucket}?seaweedfs-quota` — set bucket quota (IAM permission `s3:PutBucketQuota`)
|
||||
- `GET /{bucket}?seaweedfs-quota` — get bucket quota (IAM permission `s3:GetBucketQuota`)
|
||||
|
||||
**PUT request body** (JSON):
|
||||
```json
|
||||
{"quota_size": 100, "quota_unit": "GB", "quota_enabled": true}
|
||||
```
|
||||
|
||||
**GET response body** (JSON):
|
||||
```json
|
||||
{"quota_size": 107374182400, "quota_unit": "B", "quota_enabled": true}
|
||||
```
|
||||
|
||||
Note: GET always returns `quota_unit: "B"` and the absolute byte count, not
|
||||
the original unit. A disabled-but-retained quota returns a positive
|
||||
`quota_size` with `quota_enabled: false`.
|
||||
|
||||
Quota is stored on the bucket's filer entry (positive = enabled, negative =
|
||||
disabled but retained, zero = no quota), matching the existing admin REST API
|
||||
behavior. When quota is cleared, the bucket's read-only flag is also lifted.
|
||||
|
||||
**Authentication** uses the existing S3 SigV4 flow — no new global secret is
|
||||
needed. The CloudStack service credential (the `accesskey`/`secretkey` on the
|
||||
object store) is the admin credential used for all driver operations: bucket
|
||||
CRUD, IAM user provisioning, and quota management. It must have broad S3 and
|
||||
IAM permissions. The per-account IAM users created by `createUser` are the
|
||||
ones with restricted permissions (full S3 access except bucket
|
||||
creation/deletion). A future hardening could split quota management onto a
|
||||
separate credential scoped to only `s3:PutBucketQuota`/`s3:GetBucketQuota`,
|
||||
but the MVP uses the single admin credential for simplicity, matching how
|
||||
the MinIO and Ceph providers work.
|
||||
|
||||
The plugin's `setBucketQuota` signs and sends the `PUT /{bucket}?seaweedfs-quota`
|
||||
request using the AWS SDK v1 `AWSS3V4Signer` for SigV4 signing, then sends the
|
||||
signed request via `java.net.http.HttpClient` (the AWS S3 SDK doesn't natively
|
||||
support custom subresources, so we sign manually and send the request
|
||||
ourselves). The `seaweedfs-quota` query parameter is included in the signed
|
||||
canonical query string.
|
||||
|
||||
### Usage reporting
|
||||
|
||||
`getAllBucketsUsage` must return a `Map<String, Long>` of bucket name → size.
|
||||
MinIO uses `MinioAdminClient.getDataUsageInfo`; Ceph uses
|
||||
`RgwAdmin.listBucketInfo`. SeaweedFS has no admin rollup endpoint, so the MVP
|
||||
plugin computes it by listing buckets and summing object sizes via S3
|
||||
`ListObjectsV2` — expensive for large stores.
|
||||
|
||||
For production scale, SeaweedFS already exposes per-bucket size in:
|
||||
- **Prometheus metrics** (`bucket_size_bytes` gauge, refreshed every minute)
|
||||
- **SOSAPI `capacity.xml`** (reports capacity, available space, and usage
|
||||
through the S3 endpoint)
|
||||
|
||||
Operators should consume one of those instead of S3 list-based aggregation for
|
||||
large deployments. The MVP's list-based approach is correct but slow; flag it as
|
||||
a known limitation.
|
||||
|
||||
## SeaweedFS API surface (what the plugin relies on)
|
||||
|
||||
SeaweedFS exposes two relevant APIs, both AWS-compatible:
|
||||
|
||||
### S3 API (`weed s3`)
|
||||
Full S3-compatible surface. Confirmed against the SeaweedFS S3 wiki and code:
|
||||
- `CreateBucket`, `HeadBucket`, `ListBuckets`, `DeleteBucket`
|
||||
- `PutBucketPolicy`, `GetBucketPolicy`, `DeleteBucketPolicy`
|
||||
- `PutBucketVersioning` (Enabled / Suspended), `GetBucketVersioning`
|
||||
- `PutBucketEncryption`, `GetBucketEncryption`, `DeleteBucketEncryption`
|
||||
- `PutBucketAcl`, `GetBucketAcl`
|
||||
- `ListObjectsV2`, `HeadObject`, `GetObject`, `PutObject`, `DeleteObject`
|
||||
- Bucket quota via extended attributes / `s3.bucket.quota` (enforced server-side,
|
||||
surfaced as a read-only state when exceeded — see PR #10224)
|
||||
|
||||
### IAM API (`weed iam` / `iamapi`)
|
||||
AWS IAM-compatible REST endpoints, implemented in `weed/iamapi/`. Confirmed by
|
||||
the test suite which uses the **AWS IAM SDK** (`aws-sdk-go/service/iam`) against
|
||||
the same handlers CloudStack would call:
|
||||
- `CreateUser`, `DeleteUser`, `ListUsers`, `GetUser`
|
||||
- `CreateAccessKey`, `DeleteAccessKey`, `ListAccessKeys`
|
||||
- `PutUserPolicy`, `GetUserPolicy`, `DeleteUserPolicy`
|
||||
- `AttachUserPolicy`, `ListAttachedUserPolicies`
|
||||
|
||||
This means the CloudStack plugin can manage SeaweedFS users with the **AWS IAM
|
||||
Java SDK** (`com.amazonaws.services.identitymanagement.AmazonIdentityManagement`),
|
||||
exactly the way the AWS IAM Go SDK is used in SeaweedFS's own tests. No proprietary
|
||||
admin client is needed. **Cloudian HyperStore already does exactly this** in the
|
||||
CloudStack tree — the SeaweedFS plugin follows the same pattern.
|
||||
|
||||
## Design
|
||||
|
||||
### Module layout
|
||||
|
||||
New CloudStack plugin module, mirroring `plugins/storage/object/cloudian/`
|
||||
(the closest precedent — same AWS S3 + IAM SDK approach):
|
||||
|
||||
```
|
||||
plugins/storage/object/seaweedfs/
|
||||
pom.xml
|
||||
src/main/java/org/apache/cloudstack/storage/datastore/
|
||||
driver/SeaweedFSObjectStoreDriverImpl.java
|
||||
lifecycle/SeaweedFSObjectStoreLifeCycleImpl.java
|
||||
provider/SeaweedFSObjectStoreProviderImpl.java
|
||||
util/SeaweedFSObjectStoreUtil.java
|
||||
src/test/java/org/apache/cloudstack/storage/datastore/
|
||||
driver/SeaweedFSObjectStoreDriverImplTest.java
|
||||
provider/SeaweedFSObjectStoreProviderImplTest.java
|
||||
src/main/resources/META-INF/cloudstack/storage-object-seaweedfs/
|
||||
module.properties
|
||||
spring-storage-object-seaweedfs-context.xml
|
||||
```
|
||||
|
||||
### `SeaweedFSObjectStoreProviderImpl`
|
||||
|
||||
Direct copy of `MinIOObjectStoreProviderImpl` with `providerName = "SeaweedFS"`,
|
||||
injecting the SeaweedFS lifecycle and driver. Registers via
|
||||
`storeMgr.registerDriver`.
|
||||
|
||||
### `SeaweedFSObjectStoreLifeCycleImpl`
|
||||
|
||||
Copy of `MinIOObjectStoreLifeCycleImpl`. `initialize()` reads `url`, `name`,
|
||||
`accesskey`, `secretkey` from the `addObjectStoragePool` details map, tests the
|
||||
connection by calling `AmazonS3.listBuckets()` against the SeaweedFS S3 endpoint,
|
||||
and persists the `ObjectStoreVO`. No proprietary client needed — the AWS S3 SDK
|
||||
is enough for the health check.
|
||||
|
||||
### `SeaweedFSObjectStoreDriverImpl`
|
||||
|
||||
The substantive class. Uses two AWS SDK v1 clients (same dependency Ceph already
|
||||
pulls in, so no new CloudStack dependency):
|
||||
|
||||
- `AmazonS3` for bucket operations (path-style, endpoint-pinned, `us-east-1`
|
||||
region placeholder — same as Ceph's `getS3Client`)
|
||||
- `AmazonIdentityManagement` for user/credential operations, pointed at the
|
||||
SeaweedFS IAM endpoint
|
||||
|
||||
#### Bucket operations — straightforward S3
|
||||
|
||||
| Interface method | Implementation |
|
||||
| --- | --- |
|
||||
| `createBucket` | `s3.createBucket(name)`; reject if `doesBucketExistV2`; persist access/secret key + URL on `BucketVO` (same as Ceph) |
|
||||
| `listBuckets` | `s3.listBuckets()` → wrap as `BucketObject` (same as Ceph) |
|
||||
| `deleteBucket` | `s3.deleteBucket(name)` (same as Ceph) |
|
||||
| `setBucketPolicy` | `s3.setBucketPolicy(...)` with the same public/private JSON the MinIO/Ceph drivers build |
|
||||
| `getBucketPolicy` / `deleteBucketPolicy` | `s3.getBucketPolicy` / `s3.deleteBucketPolicy` |
|
||||
| `setBucketVersioning` | `s3.setBucketVersioningConfiguration(Enabled)` |
|
||||
| `deleteBucketVersioning` | `s3.setBucketVersioningConfiguration(Suspended)` |
|
||||
| `setBucketEncryption` | `s3.setBucketEncryptionConfiguration(SSE-S3 rule)` |
|
||||
| `deleteBucketEncryption` | `s3.deleteBucketEncryptionConfiguration` |
|
||||
| `getBucketAcl` / `setBucketAcl` | no-op / null (same as MinIO and Ceph) |
|
||||
|
||||
#### User creation — the key difference
|
||||
|
||||
MinIO calls `MinioAdminClient.addUser`; Ceph calls `RgwAdmin.createUser`. SeaweedFS
|
||||
exposes the standard AWS IAM API, so the plugin calls:
|
||||
|
||||
```java
|
||||
AmazonIdentityManagement iam = getIamClient(storeId);
|
||||
String userName = "acs-" + account.getUuid();
|
||||
|
||||
// CreateUser (idempotent — check GetUser first, like Ceph does)
|
||||
iam.createUser(new CreateUserRequest(userName));
|
||||
|
||||
// CreateAccessKey → returns the access key + secret key to persist
|
||||
CreateAccessKeyResult result = iam.createAccessKey(
|
||||
new CreateAccessKeyRequest().withUserName(userName));
|
||||
AccessKey key = result.getAccessKey();
|
||||
|
||||
// Persist per-account, same pattern as Ceph's CEPH_ACCESS_KEY/CEPH_SECRET_KEY
|
||||
details.put(SEAWEEDFS_ACCESS_KEY, key.getAccessKeyId());
|
||||
details.put(SEAWEEDFS_SECRET_KEY, key.getSecretAccessKey());
|
||||
_accountDetailsDao.persist(accountId, details);
|
||||
```
|
||||
|
||||
This is the cleanest mapping of the three providers: no proprietary admin client,
|
||||
just the AWS IAM SDK that CloudStack already has access to. The IAM endpoint URL
|
||||
is provided as `iamUrl` in the store details. If `iamUrl` is omitted, the driver
|
||||
defaults it to `s3Url` — SeaweedFS registers its embedded IAM API at `POST /` on
|
||||
the same S3 endpoint (`UnifiedPostHandler` in `s3api_server.go`), so the IAM
|
||||
endpoint is the same as the S3 endpoint unless the deployment runs a separate
|
||||
`weed iam` server.
|
||||
|
||||
#### Bucket quota — S3 `?seaweedfs-quota` extension
|
||||
|
||||
This is the one genuine gap. MinIO and Ceph both have an admin API to set a
|
||||
per-bucket quota that the backend enforces. SeaweedFS enforces bucket quota
|
||||
server-side, but the configuration path was **not exposed over a standard S3 or
|
||||
IAM API** — it was only set via the admin REST API or shell commands.
|
||||
|
||||
The integration adds a **narrow S3 subresource** to SeaweedFS:
|
||||
- `PUT /{bucket}?seaweedfs-quota` — set bucket quota (IAM permission `s3:PutBucketQuota`)
|
||||
- `GET /{bucket}?seaweedfs-quota` — get bucket quota (IAM permission `s3:GetBucketQuota`)
|
||||
|
||||
This is implemented in SeaweedFS PR #11279. It uses SigV4 authentication and
|
||||
dedicated IAM permissions, so the CloudStack service credential can be scoped
|
||||
to quota management only — no global admin token, no cluster-wide admin access.
|
||||
The enforcement already exists (PR #10224); this PR only adds the HTTP
|
||||
configuration surface.
|
||||
|
||||
An earlier approach (PR #11278, closed) added bearer-token auth to the broad
|
||||
admin REST API. After review, that was unnecessary for this integration —
|
||||
static S3 config plus standard S3 APIs plus one scoped quota mutation API is
|
||||
sufficient and far safer.
|
||||
|
||||
> **Note on AWS tools compatibility.** `?seaweedfs-quota` is a SeaweedFS-specific
|
||||
> S3 subresource, not part of the AWS S3 API. Standard AWS tools (`aws s3api`,
|
||||
> `s3cmd`, `rclone`) cannot call it directly. This is the same limitation MinIO
|
||||
> and Ceph have — MinIO quota lives behind a separate admin API (`mc admin
|
||||
> bucket quota`), and Ceph quota lives behind the Admin Ops API
|
||||
> (`radosgw-admin quota set`). Neither is callable via `aws s3api` either.
|
||||
> SeaweedFS's approach is the closest to standard S3 because it uses the same
|
||||
> endpoint and same SigV4 credentials, just with a custom query parameter.
|
||||
> Interactive quota management remains available via `weed shell`; the S3
|
||||
> extension exists for programmatic integration (CloudStack) where the
|
||||
> integrator can sign SigV4 requests but cannot run shell commands.
|
||||
|
||||
#### Usage reporting
|
||||
|
||||
`getAllBucketsUsage` must return a `Map<String, Long>` of bucket name → size.
|
||||
MinIO uses `MinioAdminClient.getDataUsageInfo`; Ceph uses
|
||||
`RgwAdmin.listBucketInfo`. SeaweedFS has no admin rollup endpoint, so the MVP
|
||||
plugin computes it by listing buckets and summing object sizes via S3
|
||||
`ListObjectsV2` — expensive for large stores. Better options exist in
|
||||
SeaweedFS already:
|
||||
- **Prometheus metrics** (`bucket_size_bytes` gauge, refreshed every minute)
|
||||
- **SOSAPI `capacity.xml`** (reports capacity, available space, and usage
|
||||
through the S3 endpoint — note: the current "return zero on backend error"
|
||||
behavior should be validated before using it for billing)
|
||||
|
||||
For the MVP, `listBuckets` + per-bucket size via the S3 API is correct but slow;
|
||||
flag it as a known limitation. Operators should consume Prometheus or SOSAPI
|
||||
for production-scale usage reporting.
|
||||
|
||||
### Spring wiring
|
||||
|
||||
`spring-storage-object-seaweedfs-context.xml` registers the provider bean,
|
||||
identical to the MinIO one. `module.properties` sets
|
||||
`name=storage-object-seaweedfs`, `parent=storage`.
|
||||
|
||||
### `pom.xml`
|
||||
|
||||
Depends on `aws-java-sdk-s3` and `aws-java-sdk-iam` — both already in the
|
||||
CloudStack dependency tree (Ceph uses the S3 SDK; the IAM SDK is the standard AWS
|
||||
bundle). No new third-party dependency, unlike MinIO which pulls in the MinIO
|
||||
Java client.
|
||||
|
||||
## What changes on the SeaweedFS side
|
||||
|
||||
**One narrow S3 extension is required for quota management.** SeaweedFS PR #11279
|
||||
adds the `?seaweedfs-quota` S3 subresource:
|
||||
|
||||
- `PUT /{bucket}?seaweedfs-quota` — set bucket quota (IAM permission `s3:PutBucketQuota`)
|
||||
- `GET /{bucket}?seaweedfs-quota` — get bucket quota (IAM permission `s3:GetBucketQuota`)
|
||||
|
||||
This is authenticated via standard S3 SigV4 and authorized via dedicated IAM
|
||||
permissions, so no global admin token is needed. The enforcement already exists
|
||||
(PR #10224); this PR only adds the HTTP configuration surface.
|
||||
|
||||
One follow-up improvement on the SeaweedFS side would close the usage reporting
|
||||
gap:
|
||||
|
||||
1. **Validate SOSAPI `capacity.xml` usage calculation** — the current "return
|
||||
zero on backend error" behavior should be validated before using it for
|
||||
billing. If reliable, CloudStack can consume it directly instead of
|
||||
list-based aggregation.
|
||||
|
||||
## Open questions for proIO / Swen
|
||||
|
||||
1. **IAM endpoint path.** ~~Where does `weed iam` listen relative to the S3
|
||||
endpoint in a typical proIO deployment?~~ **Resolved.** SeaweedFS registers
|
||||
its embedded IAM API at `POST /` on the same S3 endpoint
|
||||
(`UnifiedPostHandler`), so the driver defaults `iamUrl` to `s3Url`. A
|
||||
separate `iamUrl` is only needed if the deployment runs a standalone
|
||||
`weed iam` server on a different host/port.
|
||||
2. **Quota requirements.** Do proIO's customers need server-enforced per-bucket
|
||||
quotas, or is CloudStack-side accounting sufficient for the first release?
|
||||
The `?seaweedfs-quota` S3 extension (PR #11279) provides server-enforced
|
||||
quotas via a scoped credential; this is the recommended path.
|
||||
3. **Object Lock.** `createBucket` takes an `objectLock` boolean. MinIO supports
|
||||
it; Ceph ignores it. SeaweedFS has Object Lock support. Should the plugin pass
|
||||
it through?
|
||||
4. **Contribution model.** Does proIO want to submit the PR to
|
||||
`apache/cloudstack` themselves (with SeaweedFS maintainers as reviewers), or
|
||||
the reverse? Apache CloudStack requires an ICLA for non-trivial contributions.
|
||||
|
||||
## Files
|
||||
|
||||
All in the `apache/cloudstack` repo (new module):
|
||||
|
||||
| File | Purpose |
|
||||
| --- | --- |
|
||||
| `plugins/storage/object/seaweedfs/pom.xml` | Maven module |
|
||||
| `.../datastore/util/SeaweedFSObjectStoreUtil.java` | S3 + IAM client builders, constants, URL validators |
|
||||
| `.../datastore/provider/SeaweedFSObjectStoreProviderImpl.java` | Spring provider registration |
|
||||
| `.../datastore/lifecycle/SeaweedFSObjectStoreLifeCycleImpl.java` | Pool add/health-check |
|
||||
| `.../datastore/driver/SeaweedFSObjectStoreDriverImpl.java` | Bucket + user ops via S3 + IAM SDK |
|
||||
| `.../resources/META-INF/cloudstack/storage-object-seaweedfs/module.properties` | Module name |
|
||||
| `.../resources/META-INF/cloudstack/storage-object-seaweedfs/spring-storage-object-seaweedfs-context.xml` | Spring bean |
|
||||
| `plugins/pom.xml` | Register `storage/object/seaweedfs` module |
|
||||
|
||||
No files in `seaweedfs/seaweedfs` for the MVP.
|
||||
|
||||
### SeaweedFS-side changes (PR #11279)
|
||||
|
||||
| File | Purpose |
|
||||
| --- | --- |
|
||||
| `weed/s3api/s3_constants/s3_action_strings.go` | Add `S3_ACTION_PUT_BUCKET_QUOTA` and `S3_ACTION_GET_BUCKET_QUOTA` |
|
||||
| `weed/s3api/s3_constants/s3_actions.go` | Add coarse-grained `ACTION_PUT_BUCKET_QUOTA` and `ACTION_GET_BUCKET_QUOTA` |
|
||||
| `weed/s3api/s3_action_resolver.go` | Map `seaweedfs-quota` query param to fine-grained s3: actions |
|
||||
| `weed/s3api/s3api_bucket_quota_handlers.go` | New — `PutBucketQuotaHandler` and `GetBucketQuotaHandler` |
|
||||
| `weed/s3api/s3api_bucket_quota_handlers_test.go` | New — tests for unit conversion, validation, and error paths |
|
||||
| `weed/s3api/s3api_server.go` | Register the two routes in the bucket subrouter |
|
||||
@@ -1,696 +0,0 @@
|
||||
# Lance Catalog for SeaweedFS
|
||||
|
||||
A second catalog surface next to the Iceberg REST catalog, speaking the Lance Namespace
|
||||
REST spec, over the same table buckets and the same filer.
|
||||
|
||||
## Why
|
||||
|
||||
Gravitino 1.1 added a Lance REST service and 1.3 ships it as a standalone server; Lakekeeper
|
||||
added Lance in the same window by a completely different route. That is the useful signal:
|
||||
two unrelated catalogs decided independently that Lance had to be first-class, not a niche.
|
||||
The client side is already there — `lance-spark` (`LanceNamespaceSparkCatalog`
|
||||
with `impl=rest`), `lance-ray`, and the generated Python/Java/Rust clients all talk the same
|
||||
OpenAPI. Implementing the spec means those engines work against SeaweedFS with no
|
||||
SeaweedFS-specific code on the client.
|
||||
|
||||
The second reason is that Gravitino's own documentation names the gap it cannot close:
|
||||
DuckDB, pandas and DataFusion "do not support Lance REST natively yet" and have to fetch a
|
||||
location from the catalog and then open the dataset directly. Gravitino cannot help there,
|
||||
because it does not own the storage. SeaweedFS does. That is the whole design opportunity
|
||||
below.
|
||||
|
||||
## Prior art: three families
|
||||
|
||||
Upstream lists twelve catalog implementations, and they fall into three shapes. Knowing
|
||||
which one we are building matters more than any individual API decision.
|
||||
|
||||
**1. Storage-native, no service.** The Lance Directory Catalog. V1 is a directory listing
|
||||
where every `<name>.lance/` child of a prefix is a table; V2 adds a `__manifest` table —
|
||||
itself a Lance table — holding `object_id`/`object_type`/`location` rows, with nested
|
||||
namespaces, hash-prefixed table directories, and optional managed versioning. No server, no
|
||||
credentials, no governance. This is the floor every other implementation has to beat.
|
||||
|
||||
**2. Protocol-native server.** Someone implements the Lance Namespace REST OpenAPI and
|
||||
clients connect with `impl=rest`. Gravitino is the only one of the twelve that does this,
|
||||
and it is what this design proposes.
|
||||
|
||||
**3. Client-side adapters onto an existing catalog.** Nine of the twelve. The Lance client
|
||||
translates namespace operations into whatever the backing catalog already speaks: Apache
|
||||
Polaris, Unity Catalog, AWS Glue, Hive Metastore v2 and v3, Google BigLake, Dataproc,
|
||||
Microsoft OneLake — and Apache Iceberg REST. Two flavors:
|
||||
|
||||
- Catalogs with a real non-Iceberg table concept mark the format directly. Polaris uses its
|
||||
Generic Table API with `format = lance`; Unity uses an `EXTERNAL` table with
|
||||
`table_type=lance` in properties and the path in `storage_location`; Glue uses
|
||||
`EXTERNAL_TABLE` plus `table_type=lance` in `Parameters`, path in
|
||||
`StorageDescriptor.Location`.
|
||||
- Catalogs with no such concept fake one. The Iceberg REST adapter registers **a regular
|
||||
Iceberg table with a dummy schema — a single nullable string column named `dummy`** —
|
||||
carrying the property `table_type=lance`, and treats the Iceberg table location as the
|
||||
Lance dataset root.
|
||||
|
||||
Every adapter in family 3 lands in the same place: `DeclareTable`/`ListTables`/
|
||||
`DescribeTable`/`DeregisterTable` only, `DropNamespace` in RESTRICT mode only,
|
||||
`load_detailed_metadata=false` only, and `managed_versioning=false`. They are a name-to-
|
||||
location map and nothing more.
|
||||
|
||||
Lakekeeper is the instructive outlier. It has the same generic-table concept Polaris has,
|
||||
but no upstream adapter exists for it — there is no `lance-namespace` reference anywhere in
|
||||
its repository and no page for it in the supported-catalogs list. So Polaris's generic tables
|
||||
are reachable from a stock Lance client and Lakekeeper's are not, despite being the same
|
||||
idea. Shipping the concept is not the same as shipping the integration.
|
||||
|
||||
## Gravitino and Lakekeeper: the two opposite bets
|
||||
|
||||
Both shipped Lance support in the same window and did not build the same thing.
|
||||
|
||||
**Gravitino implements the protocol.** Its `lance/` module serves the Lance Namespace REST
|
||||
spec on its own port (`:9101/lance`), so stock `lance-spark` and `lance-ray` connect with
|
||||
`impl=rest` and no vendor-specific client. The cost is governance: storage credentials are
|
||||
static properties on the catalog (`lance.storage.access_key_id`, `secret_access_key`,
|
||||
`endpoint`, `region`, `allow_http`), optionally overridden per table, handed to the engine
|
||||
as-is. No STS, no expiry, no per-table scoping.
|
||||
|
||||
**Lakekeeper refuses the protocol and governs the object instead.** There is no
|
||||
`lance-namespace` anywhere in the repository; Lance arrived in 0.13.0 (2026-06-30, issue
|
||||
#1673 `Generic Table API with Lance`) as one `format` string on a Lakekeeper-native Generic
|
||||
Table API:
|
||||
|
||||
```
|
||||
POST/GET/DELETE /lakekeeper/v1/{prefix}/namespaces/{ns}/generic-tables[/{table}]
|
||||
GET /lakekeeper/v1/{prefix}/namespaces/{ns}/generic-tables/{table}/credentials
|
||||
POST /lakekeeper/v1/{prefix}/generic-tables/rename
|
||||
```
|
||||
|
||||
`format` is opaque, `schema` and `statistics` are stored but never validated, and the
|
||||
catalog writes no format-specific metadata — engines go straight to the location. In
|
||||
exchange Lance tables get everything Iceberg tables get: STS-vended prefix-scoped
|
||||
credentials, OpenFGA per-action permissions (16 actions), soft-delete with undrop, a
|
||||
protection flag, rename, pagination, and name uniqueness across Iceberg tables, views and
|
||||
generic tables in one namespace. The price is that no stock Lance client can talk to it —
|
||||
you need `pylakekeeper`, which exists mainly to translate vended credentials into
|
||||
`lance_storage_options`.
|
||||
|
||||
So: protocol fidelity and weak governance, or strong governance and client lock-in. Both
|
||||
documented their limit honestly, and it is the same limit. Lakekeeper's capability table
|
||||
says it outright — "Commit coordination: the catalog does not arbitrate writes — engines
|
||||
write directly." Gravitino does not claim it either. Neither of them coordinates a Lance
|
||||
commit, which is exactly the thing a store can do and a control plane cannot.
|
||||
|
||||
We do not have to choose. Serve the Lance protocol natively the way Gravitino does, over
|
||||
the `s3tables` entries that already carry ARNs, policies, tags and maintenance config, and
|
||||
the governance comes from the layer underneath rather than from a proprietary API on top.
|
||||
That is only available to us because we are the store, which is also what makes the third
|
||||
option — arbitrating the commit — available.
|
||||
|
||||
## We are probably already a Lance catalog, and that is a problem
|
||||
|
||||
The Iceberg REST adapter does not care whose Iceberg catalog it is talking to. It needs
|
||||
`/v1/config?warehouse=`, `/v1/{prefix}/namespaces`, `/v1/{prefix}/namespaces/{ns}/tables`
|
||||
and unit-separator (`\x1F`) multi-level namespaces. We serve all of those, and
|
||||
`parseNamespace` in `weed/s3api/iceberg/utils.go:22` already splits on `\x1F`. So a stock
|
||||
Lance client pointed at our Iceberg catalog on :8181 with the Iceberg impl should already
|
||||
create, list, describe and deregister Lance tables today, with no SeaweedFS change at all.
|
||||
|
||||
That is worth testing before writing a line of the design above, for two reasons. It is a
|
||||
free baseline — and possibly a free announcement. And it is a data-loss hazard.
|
||||
|
||||
A Lance table registered this way is an Iceberg table whose metadata references no data
|
||||
files, sitting on top of a Lance dataset that uses `data/` for its fragments — the same
|
||||
subdirectory name Iceberg uses. The maintenance worker's orphan cleaner walks exactly
|
||||
`<table>/metadata` and `<table>/data`, and deletes every file not referenced by a snapshot
|
||||
and older than `orphan_older_than_hours`
|
||||
(`weed/worker/tasks/iceberg/operations.go:331`, default 72). Against an adapter-registered
|
||||
Lance table, every fragment is unreferenced by construction. Run maintenance and the
|
||||
dataset is deleted.
|
||||
|
||||
Maintenance is disabled by default (`handler.go:334`), so this is a latent hazard rather
|
||||
than a live one: it needs an operator to enable Iceberg maintenance on a bucket that also
|
||||
holds adapter-registered Lance tables. But it costs nothing to close — detection should
|
||||
skip any table carrying a non-Iceberg format marker (`table_type` property, or
|
||||
`Format != "ICEBERG"` once the format field is honest), and that guard is worth landing on
|
||||
its own regardless of whether the rest of this design ever gets built. It is the same
|
||||
"catalog-only, no maintenance" marker the generic-format question needs.
|
||||
|
||||
## Where we differ from Gravitino
|
||||
|
||||
Gravitino is a metadata service in front of somebody else's object store:
|
||||
|
||||
```
|
||||
Spark / Ray Spark / Ray / pandas / duckdb
|
||||
| |
|
||||
Lance REST Lance REST (direct S3)
|
||||
| | |
|
||||
Gravitino SeaweedFS S3 gateway ----+
|
||||
| |
|
||||
S3 keys handed out SeaweedFS filer + volumes
|
||||
|
|
||||
somebody else's S3
|
||||
```
|
||||
|
||||
It resolves a name to a location plus `lance.storage.*` credentials, and steps out of the
|
||||
way. Everything a Lance table actually is — `_versions/`, `data/`, `_indices/` — is opaque
|
||||
to it.
|
||||
|
||||
We are the store. Three things follow that Gravitino cannot do:
|
||||
|
||||
1. The catalog and a plain directory listing can be made to agree, so a client with no
|
||||
catalog at all still sees the right tables.
|
||||
2. `_versions/` is a filer directory listing, not an object-store `LIST`. Version history
|
||||
is cheap and can back the admin UI.
|
||||
3. We can offer a genuinely atomic commit reservation. Lance's commit protocol needs
|
||||
put-if-not-exists; our S3 layer does not currently provide one (see
|
||||
[Commit safety](#commit-safety)). The filer does.
|
||||
|
||||
## Placement
|
||||
|
||||
The Iceberg catalog is a thin HTTP shell over `s3tables.Manager`; the storage work lives in
|
||||
`weed/s3api/s3tables`. Table buckets live under `TablesPath = s3_constants.DefaultBucketsPath`,
|
||||
i.e. the same filer tree the S3 gateway serves, so `s3://bucket/ns/table/` is simultaneously
|
||||
a catalog entry and an S3 prefix. Catalog entries are filer directories carrying `s3tables.*`
|
||||
extended attributes. `Table.Format` already exists and is hard-checked against `"ICEBERG"`
|
||||
in `weed/s3api/s3tables/handler_table.go:48`.
|
||||
|
||||
So:
|
||||
|
||||
```
|
||||
weed/s3api/lance/ new: HTTP surface, id codec, error model
|
||||
weed/s3api/s3tables/ extended: Format "LANCE", lance state xattr, version entries
|
||||
weed/command/s3.go new: -port.lance (default 9101), startLanceServer
|
||||
```
|
||||
|
||||
`Format: "LANCE"` on the table entry is the whole storage-model change for phase 1.
|
||||
Everything else — namespaces, ARNs, policies, tags, ownership — is shared verbatim.
|
||||
|
||||
```
|
||||
s3tables.Manager (filer)
|
||||
|
|
||||
+------------------------+------------------------+
|
||||
| |
|
||||
weed/s3api/iceberg weed/s3api/lance
|
||||
Iceberg REST :8181 Lance REST :9101
|
||||
| |
|
||||
Iceberg tables Lance datasets
|
||||
\ /
|
||||
+-------------------- s3 :8333 -----------------+
|
||||
|
|
||||
SeaweedFS volumes
|
||||
```
|
||||
|
||||
## Identifier mapping
|
||||
|
||||
Lance identifiers are `["ns", ..., "table"]`, encoded in the URL as a single string joined
|
||||
by a delimiter that defaults to `$`. The delimiter alone means the root namespace, so
|
||||
`/v1/namespace/$/list` lists the root's children.
|
||||
|
||||
Iceberg had to invent a warehouse selector because its identifier is flat and every table
|
||||
bucket is a separate catalog. Lance does not need that — its identifier is already
|
||||
hierarchical, and Gravitino uses exactly three levels (`["lance_catalog", "sales", "orders"]`).
|
||||
That maps onto us without inventing anything:
|
||||
|
||||
```
|
||||
$ root -> list of table buckets
|
||||
$analytics level 1 -> a table bucket
|
||||
$analytics$sales level 2 -> a namespace in that bucket
|
||||
$analytics$sales$orders table
|
||||
```
|
||||
|
||||
`spark.sql.catalog.lance.parent = analytics` then makes `sales.orders` resolve, which is the
|
||||
same shape Gravitino's Spark example uses.
|
||||
|
||||
Levels 2..N join into one `s3tables` namespace with `.`, matching what the Iceberg catalog
|
||||
already does with `flattenNamespacePath`. The flattened form is only the directory name —
|
||||
`namespaceMetadata.Namespace []string` in the xattr keeps the authoritative parts, so the
|
||||
mapping stays invertible even though `.` is a legal character inside a namespace part.
|
||||
Reject `$` in any name part with `InvalidInput`; our charsets already exclude it, so no
|
||||
escaping scheme is needed.
|
||||
|
||||
Root-level `ListNamespaces` returning table buckets means an unauthenticated or
|
||||
broadly-scoped caller can enumerate buckets. Filter it through the same
|
||||
`s3tables/permissions.go` check `ListTableBuckets` uses, not a separate path.
|
||||
|
||||
`CreateNamespace` on a one-part identifier creates a table bucket, and it does so only if
|
||||
the caller is permitted to — the namespace never creates a bucket as a side effect of
|
||||
creating something inside it. A table bucket is a tenant resource with its own policy, ARN
|
||||
and lifecycle, and conjuring one because a client said `CREATE SCHEMA` is a privilege
|
||||
escalation dressed as a convenience. Lakekeeper draws the same line explicitly: its client
|
||||
creates tables, not warehouses.
|
||||
|
||||
## Storage layout
|
||||
|
||||
Lay tables out as:
|
||||
|
||||
```
|
||||
s3://<table-bucket>/<flattened-namespace>/<table>/
|
||||
data/
|
||||
_versions/
|
||||
_indices/
|
||||
```
|
||||
|
||||
**Built without the `.lance` suffix this design originally proposed.** The suffix would have
|
||||
made every namespace prefix a valid Lance Directory Catalog V1 root, since V1 recognises a
|
||||
table by exactly that naming. It does not survive contact with the storage layer: the
|
||||
catalog entry *is* the dataset directory, `validateTableName` excludes `.` from the charset,
|
||||
and a suffixed entry name would leak into ARNs, policy documents and the S3 Tables API,
|
||||
where the same table would answer to two different names. Making `GetTablePath` format-aware
|
||||
instead spreads an "unless it is Lance" branch through code that has no business knowing —
|
||||
the exact cross-cutting cost this design rejects family 3 for.
|
||||
|
||||
So one name, one directory. What survives is direct access by URI, which is the larger half
|
||||
of the story and needs no naming convention at all:
|
||||
|
||||
```python
|
||||
# with the catalog
|
||||
spark.sql("SELECT * FROM lance.sales.orders")
|
||||
|
||||
# without it, same bytes
|
||||
lance.dataset("s3://analytics/sales/orders")
|
||||
```
|
||||
|
||||
DuckDB, pandas and DataFusion still reach the data with no catalog running, which is the gap
|
||||
Gravitino's documentation admits to. What they no longer get for free is *enumeration* — a
|
||||
directory-catalog client pointed at the namespace prefix will not list these as tables. If
|
||||
that turns out to matter, the cheapest fix is a repair-style tool that materialises `.lance`
|
||||
aliases, not a rename of the catalog entry.
|
||||
|
||||
Note also that the directory catalog's own V2 mode puts child-namespace tables in
|
||||
`<hash>_<ns$table>` directories at the root and creates no physical subdirectories for
|
||||
namespaces, so full directory-catalog fidelity was never on offer anyway. We are a
|
||||
server-backed catalog; the human-readable prefix layout is worth more than partial V1
|
||||
lookalike behaviour.
|
||||
|
||||
## The table bucket was not a neutral container
|
||||
|
||||
This design assumed a table bucket is a place to put a table's files. It is
|
||||
not: `validateTableBucketObjectPath` runs on every S3 write into one and
|
||||
validated the path against Iceberg's layout, so a Lance client got 403 on
|
||||
`data/*.lance`, on `_versions/`, and on `_transactions/` — a directory Lance
|
||||
writes that neither the spec documentation nor this design anticipated. Nothing
|
||||
about the catalog worked end to end until that changed.
|
||||
|
||||
The layout guard now admits the union of what the supported formats write, and
|
||||
treats any underscore-prefixed top-level directory as belonging to the format,
|
||||
checking only that the path stays inside the table. Enumerating Lance's
|
||||
internal directories by name is exactly the mistake that missed
|
||||
`_transactions`. Iceberg writes none of them, so it loses nothing.
|
||||
|
||||
Found by pointing the real Python client at a running gateway, not by reading
|
||||
the spec. Worth remembering for the next format: the premise to check first is
|
||||
whether the storage layer will accept its files at all.
|
||||
|
||||
## Table lifecycle
|
||||
|
||||
Lance has three table states, and the spec pins them to marker files:
|
||||
|
||||
| State | Marker | Created by | Visible in ListTables |
|
||||
| --- | --- | --- | --- |
|
||||
| declared | `.lance-reserved` | `DeclareTable` | yes, when `include_declared=true` |
|
||||
| created | `_versions/` present | client writes, or `CreateTable` | yes |
|
||||
| deregistered | `.lance-deregistered` | `DeregisterTable` | no; data preserved |
|
||||
|
||||
Record the state in an xattr (`s3tables.lanceState`) on the catalog entry *and* write the
|
||||
marker file into the table directory. The xattr is what the catalog reads; the marker is
|
||||
what keeps a directory-catalog client honest. Dual-write is the price of the interop claim
|
||||
above, and it is one extra filer write on three rarely-called operations.
|
||||
|
||||
`DeclareTable` is the operation `lance-spark` actually calls on `CREATE TABLE` (it replaced
|
||||
the legacy `create-empty`), so it is not optional in practice even though the spec marks
|
||||
only a subset as required.
|
||||
|
||||
`DeregisterTable` preserving data is the same shape as our Iceberg rename, where the catalog
|
||||
entry moves and the data stays put — reuse `TableDataDirFromMetadataLocation`'s idea rather
|
||||
than re-deriving the data path from the catalog name.
|
||||
|
||||
## Commit safety
|
||||
|
||||
This is the part I got wrong, and the correction removed a feature rather than adding one.
|
||||
|
||||
Lance commits a version by writing `_versions/{v}.manifest` with put-if-not-exists: exactly
|
||||
one writer is supposed to win, and the loser rebases. In lance 10 that path is not optional
|
||||
and needs nothing bolted on — `commit_handler_from_url` hands every `s3://` dataset a
|
||||
`ConditionalPutCommitHandler`, which calls `put_opts` with `PutMode::Create`, which
|
||||
object_store's S3 backend sends as `If-None-Match: *`.
|
||||
|
||||
I originally read our gateway as evaluating that header check-then-act, and designed around
|
||||
it. That was already out of date. `buildWriteCondition`
|
||||
(`weed/s3api/s3api_object_routed_write.go`) reduces `If-None-Match: *` to a filer
|
||||
`WriteCondition{IF_NOT_EXISTS}`, and `putToFiler` routes the create to the object's owner
|
||||
filer, which evaluates the precondition under its per-path lock; when routing is not
|
||||
available it falls back to the object write lock, which evaluates it under the lock too.
|
||||
Either way it is atomic. Sixteen concurrent writers of the same fresh key get one 200 and
|
||||
fifteen 412s, repeatedly.
|
||||
|
||||
So the store already has the primitive Lance needs, cluster-wide, for every conditional-PUT
|
||||
client and not just this one.
|
||||
|
||||
### What that removed
|
||||
|
||||
An earlier draft of this design offered the catalog as an **external manifest store**:
|
||||
`managed_versioning: true` plus `CreateTableVersion` and friends, with the reserve step as a
|
||||
filer `CreateEntry` with `o_excl`. It was implemented, tested, and shipped behind a default-off
|
||||
flag — and it should not exist.
|
||||
|
||||
- It solves a problem this store does not have. The spec offers that path for stores that
|
||||
cannot order commits themselves.
|
||||
- It moves a table's version history out of the dataset and into the catalog, so a reader
|
||||
that does not go through this namespace no longer sees the whole picture. That is a real
|
||||
cost paid for nothing.
|
||||
- lance 10 cannot even use it past the first commit: `NamespaceManifestStore::put_if_not_exists`
|
||||
answers "put_if_not_exists is not supported for namespace-backed stores", which is exactly
|
||||
what a second `append` needs.
|
||||
|
||||
The version operations now answer `Unsupported` alongside the other operations the catalog
|
||||
does not serve, and `managed_versioning` is answered `false`. The property they were
|
||||
protecting is covered instead by a test that races eight writers at the manifest key through
|
||||
S3 and asserts one wins — testing the path Lance actually takes.
|
||||
|
||||
## Credential vending
|
||||
|
||||
Iceberg needed a header (`X-Iceberg-Access-Delegation: vended-credentials`) and a bespoke
|
||||
response shape. Lance has it in the spec: `vend_credentials: true` on the request,
|
||||
`storage_options` on the response, with `expires_at_millis` as the well-known expiry key.
|
||||
|
||||
Reuse the existing vendor interface unchanged — `iceberg.CredentialVendor` /
|
||||
`STSService.AssumeRoleForPrincipal` scoped to the table prefix (#10777) — and map its output
|
||||
to the storage options Lance passes through to `object_store`:
|
||||
|
||||
```
|
||||
aws_access_key_id, aws_secret_access_key, aws_session_token,
|
||||
aws_region, aws_endpoint, allow_http, expires_at_millis
|
||||
```
|
||||
|
||||
Those are the names `pylakekeeper` emits as `lance_storage_options`, which is the shape
|
||||
Lakekeeper's tested S3 path actually feeds to Lance. `object_store` also accepts the
|
||||
un-prefixed aliases (`endpoint`, `region`) that the directory catalog's `storage.` prefix
|
||||
strips down to and that Gravitino's `lance.storage.endpoint` resolves to, but the `aws_`
|
||||
forms are the ones with a tested integration behind them, so emit those. `aws_endpoint`
|
||||
should come from `deriveS3AdvertisedEndpoint()`, the same source the Iceberg `FileIO` config
|
||||
uses, and `allow_http` must be set when that endpoint is plain HTTP or every read fails with
|
||||
a TLS error that looks like a credential problem — Lakekeeper vends both automatically for
|
||||
exactly this reason, and calls out that there is then no per-vendor branch in client code.
|
||||
|
||||
We emit this server-side, in the `storage_options` field the Lance spec already defines,
|
||||
which is strictly better than Lakekeeper's arrangement: no client library has to translate
|
||||
anything, so vending works from any stock Lance client rather than only from theirs.
|
||||
|
||||
Guard the same way #10777 had to after review: bucket-scoped list grants need an `s3:prefix`
|
||||
condition, and a location containing `*` or `?` must be refused rather than widened into a
|
||||
resource pattern.
|
||||
|
||||
## Auth and authorization
|
||||
|
||||
Authentication reuses `S3Authenticator` and `CredentialValidator` as-is. The Lance spec maps
|
||||
identity to headers — `api_key` to `x-api-key`, `auth_token` to `Authorization: Bearer` — and
|
||||
SigV4 keeps working because it is the same authenticator the Iceberg catalog already fronts.
|
||||
|
||||
Authorization needs nothing new. A Lance table gets the same ARN shape,
|
||||
`arn:aws:s3tables:...:bucket/B/table/NS/T`, so every existing table-bucket policy covers
|
||||
Lance tables with no new policy language and no second permission model. Route it through
|
||||
`s3tables/permissions.go` and inherit the `DefaultAllow` semantics the Iceberg server already
|
||||
mirrors from the S3 port.
|
||||
|
||||
One spec quirk worth honoring: request context entries prefixed `header.` become request
|
||||
headers, and every response header comes back as a `header.`-prefixed context entry. Echoing
|
||||
`x-request-id` through it costs nothing and makes tracing work.
|
||||
|
||||
## What to take from Lakekeeper
|
||||
|
||||
Rejecting Lakekeeper's API shape does not mean rejecting what it learned building it.
|
||||
|
||||
**Deregister is soft-delete, so implement it as one.** Lakekeeper gives generic tables
|
||||
soft-deletion with undrop and a `protected` flag that makes a drop require `force=true`.
|
||||
Lance already has the concept — `DeregisterTable` preserves the data and hides the table —
|
||||
so the `.lance-deregistered` marker is a soft-delete by another name, and a re-register is
|
||||
an undrop. A protection flag on table-bucket entries is worth having regardless of Lance:
|
||||
it is a few lines against the existing xattrs and it applies to Iceberg tables too.
|
||||
|
||||
**Enforce one identifier space across entry kinds.** Lakekeeper rejects a generic table
|
||||
whose name collides with an Iceberg table or view in the same namespace. Our catalog entries
|
||||
already share one filer directory and already carry `s3tables.entryType`, so this is
|
||||
structurally true — but it has to be enforced deliberately on every path, or a Lance handler
|
||||
happily loads an Iceberg table's directory and vice versa. That is the same crossover bug
|
||||
class as the view/table rename authorization fixed in #10776; the `catalogEntryKind` pattern
|
||||
from that change is the thing to reuse rather than re-derive.
|
||||
|
||||
**A re-vend path matters more than it looks.** Lakekeeper exposes `/credentials` separately
|
||||
from load, because STS credentials expire in the middle of long jobs and re-loading the
|
||||
whole table to refresh them is wasteful. In Lance the spec's answer is another
|
||||
`DescribeTable` with `vend_credentials: true`, which is fine — but it means `DescribeTable`
|
||||
must stay cheap when `load_detailed_metadata` is false, which is another reason not to open
|
||||
the dataset on that path.
|
||||
|
||||
**Generic tables are a cheap orthogonal win.** Lakekeeper's real insight is that Delta,
|
||||
Parquet, CSV, Vortex and Paimon all get governance for free once the catalog stops caring
|
||||
what the format is. Our `Table.Format` field already exists and the only thing stopping it
|
||||
is the hard `"ICEBERG"` check in `handler_table.go:48`. Loosening that and letting the S3
|
||||
Tables API register a table with an arbitrary format and a location — no metadata, no
|
||||
commits — is a small change that makes every format cataloguable. It is independent of this
|
||||
design and probably worth doing first, since `Format: "LANCE"` is then just a value rather
|
||||
than a special case.
|
||||
|
||||
**Skip remote signing.** It is Lakekeeper's fallback for S3-compatible stores with no STS,
|
||||
and their own documentation notes that Lance will not use it — format libraries with their
|
||||
own S3 client expect static credentials and do not implement the Iceberg signer protocol. We
|
||||
have STS, so vended credentials are the path, and the signer is not worth building for a
|
||||
client that cannot consume it.
|
||||
|
||||
## Errors
|
||||
|
||||
Lance uses `{code, error, detail, instance}` with numeric codes, not Iceberg's exception-type
|
||||
strings. The mapping is mechanical:
|
||||
|
||||
| HTTP | code | when |
|
||||
| --- | --- | --- |
|
||||
| 400 | 13 InvalidInput | charset violations, malformed id, route/body mismatch |
|
||||
| 401 | 16 Unauthenticated | |
|
||||
| 403 | 15 PermissionDenied | |
|
||||
| 404 | 1 NamespaceNotFound, 4 TableNotFound, 11 TableVersionNotFound | |
|
||||
| 409 | 2/5 AlreadyExists, 3 NamespaceNotEmpty, 14 ConcurrentModification | |
|
||||
| 501 | 0 Unsupported | every phase-3 data operation |
|
||||
|
||||
Route/body mismatch is a spec requirement, not a nicety: when the identifier appears in both
|
||||
the path and the body and they disagree, the server must return 400. Cheap to get right at
|
||||
the decode step, annoying to retrofit.
|
||||
|
||||
## Route surface
|
||||
|
||||
Phase 0 is not in this table: point a stock Lance client at the existing Iceberg catalog
|
||||
with the Iceberg impl, see how far it gets, and land the maintenance guard either way. That
|
||||
tells us what the native server actually has to beat.
|
||||
|
||||
Phase 1, the whole `lance-spark` and `lance-ray` contract:
|
||||
|
||||
```
|
||||
POST /v1/namespace/{id}/create CreateNamespace mode: Create|ExistOk|Overwrite
|
||||
GET /v1/namespace/{id}/list ListNamespaces
|
||||
POST /v1/namespace/{id}/describe DescribeNamespace
|
||||
POST /v1/namespace/{id}/drop DropNamespace mode: Fail|Skip, behavior: Restrict|Cascade
|
||||
POST /v1/namespace/{id}/exists NamespaceExists
|
||||
GET /v1/namespace/{id}/table/list ListTables ?include_declared, ?page_token, ?limit
|
||||
GET /v1/table ListAllTables
|
||||
POST /v1/table/{id}/declare DeclareTable
|
||||
POST /v1/table/{id}/describe DescribeTable ?with_table_uri, ?load_detailed_metadata, ?check_declared
|
||||
POST /v1/table/{id}/exists TableExists
|
||||
POST /v1/table/{id}/register RegisterTable mode: Create|Overwrite
|
||||
POST /v1/table/{id}/deregister DeregisterTable
|
||||
POST /v1/table/{id}/drop DropTable
|
||||
POST /v1/table/{id}/rename RenameTable
|
||||
```
|
||||
|
||||
`DescribeTable` with `load_detailed_metadata=false` needs only `location`, which is the
|
||||
common case and which we can answer from xattrs alone. With `load_detailed_metadata=true`
|
||||
the spec wants `version`, `schema` and `stats`, which means reading the Lance manifest. For
|
||||
phase 1, return the fields we can derive from the filer — `version` from the highest entry in
|
||||
`_versions/`, given V2 naming is `{u64::MAX - version:020}.manifest` and V1 is
|
||||
`{version}.manifest` — and omit `schema`/`stats` rather than fabricating them. The spec
|
||||
tolerates a partial response here; it does not tolerate a wrong one.
|
||||
|
||||
Phase 2 was the five version operations plus `managed_versioning`; it was built and then
|
||||
removed, for the reasons under Commit safety.
|
||||
|
||||
Phase 3 is the data plane: `CreateTable`, `InsertIntoTable`, `MergeInsertIntoTable`,
|
||||
`UpdateTable`, `DeleteFromTable`, `QueryTable`, `CountTableRows`, and the index and tag
|
||||
operations. These exchange Arrow IPC, and more to the point they require reading and writing
|
||||
the Lance file format, for which no Go implementation exists. Return `Unsupported` (code 0)
|
||||
and say so in the docs. `arrow-go/v18` is already an indirect dependency, so Arrow framing is
|
||||
not the blocker — Lance is.
|
||||
|
||||
## Does a Lance table need maintenance?
|
||||
|
||||
Yes, and one part of it has no Iceberg equivalent. The client exposes three jobs:
|
||||
|
||||
- `optimize.compact_files()` — Lance writes a fragment per write batch, so a table fed by
|
||||
small appends accumulates small files exactly the way an Iceberg table does.
|
||||
- `optimize.optimize_indices()` — **rows written after an index was built are not covered by
|
||||
it.** A vector search against a stale index silently misses recent data. That is a
|
||||
correctness-shaped failure, not a slow query, and it is specific to what people use Lance
|
||||
for.
|
||||
- `cleanup_old_versions()` — every version is retained until something removes it. Lance can
|
||||
do this itself: `optimize.enable_auto_cleanup()` sets it on the dataset, so this one need
|
||||
not be an external job at all.
|
||||
|
||||
None of it can run in the Go worker. All three read and rewrite Lance files, which needs
|
||||
Lance format code that does not exist in Go, and there is no useful subset either: deciding
|
||||
which fragments an old version still references means parsing Lance manifests.
|
||||
|
||||
So the maintenance worker must not touch a Lance table, and it declines by reading the format
|
||||
the catalog recorded rather than by failing to parse Iceberg metadata.
|
||||
|
||||
## The worker can be Rust, and it is not a sidecar
|
||||
|
||||
The Go worker is not the only worker. `weed/pb/plugin.proto` defines `PluginControlService`,
|
||||
a language-agnostic gRPC stream that external maintenance workers connect on: the worker
|
||||
opens `WorkerStream`, sends `WorkerHello` with the job types it can `detect` and `execute`,
|
||||
answers `RequestConfigSchema` with a `JobTypeDescriptor`, replies to `RunDetectionRequest`
|
||||
with `JobProposal`s and to `ExecuteJobRequest` with `JobProgressUpdate`s and `JobCompleted`.
|
||||
`weed worker -admin=host:23646` is the Go reference implementation of exactly that contract,
|
||||
from outside the admin process.
|
||||
|
||||
Nothing in it is Go-specific, and the Rust toolchain is already in the tree.
|
||||
`seaweed-volume/build.rs` compiles protos straight out of `../weed/pb/` with `tonic_build`,
|
||||
including `filer.proto`, on tonic 0.12 and prost 0.13. A Lance worker is that same build
|
||||
with `plugin.proto` added and the `lance` crate as a dependency — the real one, no FFI and
|
||||
no Python.
|
||||
|
||||
Three job types, one per real maintenance operation:
|
||||
|
||||
| Job type | Calls | Detected from |
|
||||
| --- | --- | --- |
|
||||
| `lance_compact` | `optimize.compact_files` | fragment count and sizes |
|
||||
| `lance_optimize_indices` | `optimize.optimize_indices` | rows an index does not cover |
|
||||
| `lance_cleanup_versions` | `cleanup_old_versions` | version count and age |
|
||||
|
||||
What the existing machinery then supplies for free is the part worth noticing. Scheduling,
|
||||
retries, dedupe by `dedupe_key`, progress reporting, per-job concurrency limits and the
|
||||
admin settings page all come from the protocol: a worker that answers `RequestConfigSchema`
|
||||
with a descriptor gets its configuration form rendered in the admin UI without a line of Go
|
||||
or templ. A Rust worker is a first-class maintenance worker, not an appendage.
|
||||
|
||||
The remaining wiring is small and mostly decided already. `RunDetectionRequest` carries a
|
||||
`ClusterContext` with filer and S3 addresses plus a free-form `metadata` map, which is where
|
||||
the Lance namespace URL goes; the worker lists Lance tables from the namespace, which is the
|
||||
catalog of record and already filters by format. It gets at the data by asking
|
||||
`DescribeTable` for `storage_options` with `vend_credentials`, so the worker is just another
|
||||
client of the STS path rather than a component with its own credentials. And when it commits
|
||||
a compaction it goes through `CreateTableVersion` like any other writer, which is what
|
||||
managed versioning was for.
|
||||
|
||||
## The worker is also the only thing that can describe the table
|
||||
|
||||
Admin can render an Iceberg table because it can read Iceberg metadata. It cannot read
|
||||
Lance: it knows the dataset's location and its format string, and that is the whole of it.
|
||||
The details page showed a location and two empty panels, which is an honest answer and a
|
||||
useless one.
|
||||
|
||||
The worker already knows. Detection opens every dataset to decide whether it needs
|
||||
compacting, so at that moment it holds the schema, the row count, the fragment count and
|
||||
the version count. It just had no way to say so — every message on the stream was about
|
||||
work.
|
||||
|
||||
So `WorkerObservations` is a body on `WorkerToAdminMessage`: a repeated `ObjectObservation`
|
||||
of `object_id`, `object_kind`, `format`, and a `ConfigValue` map the worker fills with
|
||||
whatever it can cheaply say. Admin keeps the last observation per object and serves it back
|
||||
with the time it was taken and the worker that took it. Nothing schedules from it, and it is
|
||||
not authoritative — it is a cache with its staleness on the label, which is why the page
|
||||
badges it rather than presenting it as metadata it read itself.
|
||||
|
||||
The keys are the worker's to choose, which keeps the protocol out of the business of knowing
|
||||
what a Lance table is. A worker for any other format admin cannot parse describes itself the
|
||||
same way.
|
||||
|
||||
## A bucket declares its format
|
||||
|
||||
Format was recorded per table, which is enough for the storage layer and not enough for
|
||||
anything that has to answer a question about a bucket. The admin UI printed one Iceberg
|
||||
endpoint for every bucket, including the ones holding Lance datasets, where that endpoint
|
||||
serves nothing; an empty bucket had no format at all.
|
||||
|
||||
So `CreateTableBucket` takes an optional `format`, stored with the rest of the bucket
|
||||
metadata. Empty means `ICEBERG` - what AWS S3 Tables serves, and therefore what an SDK
|
||||
that has never heard of the field means. `CreateTable` refuses another format, and
|
||||
`CreateView` refuses outright outside an Iceberg bucket, a view being Iceberg metadata.
|
||||
The Lance namespace declares `LANCE` for the buckets it creates.
|
||||
|
||||
**Enforced rather than defaulted**, because the point of showing a format at all is the
|
||||
endpoint that follows from it, and that endpoint is only truthful if the bucket holds one
|
||||
format. **Buckets that already exist stay undeclared** and keep taking anything: nothing is
|
||||
migrated, and the UI shows "unset" as a fact about the bucket's age rather than a fault.
|
||||
That state is also the only way to hold both formats at once, which is what the
|
||||
Iceberg-REST adapter path produces.
|
||||
|
||||
## Sample rows are fetched, not cached
|
||||
|
||||
The same asymmetry has a second half. Admin renders an Iceberg table's rows by
|
||||
reading its Parquet files directly; for Lance it has nothing to read with, so the data
|
||||
page offered a Browse Data button that led to an empty grid.
|
||||
|
||||
`RequestObjectPreview` / `ObjectPreviewResponse` mirror the config-schema round trip
|
||||
already on the stream: admin asks, the worker scans the dataset and hands back rows it
|
||||
has already rendered as text, because it is the only side that knows the types. Admin
|
||||
picks the worker from the observation store, so the one that last described a table is
|
||||
the one asked to read it.
|
||||
|
||||
The rows are deliberately not cached, and that is the line between the two channels. An
|
||||
observation describes an object, so a copy with a timestamp on it is useful. Rows are the
|
||||
object's contents: a copy held in admin would be stale, larger, and nobody's business.
|
||||
The page fetches on load, bounded, or says why it cannot.
|
||||
|
||||
## The sidecar question
|
||||
|
||||
The data plane is a different problem, and this design previously conflated the two.
|
||||
Maintenance rides the worker protocol; `QueryTable` and `InsertIntoTable` do not, because
|
||||
they are synchronous REST operations on the namespace's own surface. Serving those means a
|
||||
Rust process that answers HTTP, either behind the Go namespace as a proxy target or in front
|
||||
of it. It would make SeaweedFS a store you can run vector search *in* rather than one you
|
||||
read vectors *out of*, which is the larger prize and the reason to keep the option open.
|
||||
|
||||
Neither should gate phase 1. Phases 1 and 2 are pure Go over the filer and are worth
|
||||
shipping on their own — they are what makes Spark and Ray work.
|
||||
|
||||
## Testing
|
||||
|
||||
Mirror the Iceberg package: `httptest` plus a fake filer client for the handler tests, in
|
||||
`weed/s3api/lance`. Then an integration suite under `test/s3tables/catalog/` next to the
|
||||
existing `pyiceberg_test.go`, driving the generated Python `lance-namespace` client against
|
||||
a live gateway. Three things that suite must cover and unit tests cannot:
|
||||
|
||||
- the storage-options key names actually work, i.e. a client that gets `storage_options` from
|
||||
`DescribeTable` can open the dataset;
|
||||
- a table created through the catalog is visible to `lance.dataset()` by URI and to a V1
|
||||
directory-catalog client rooted at the namespace prefix;
|
||||
- concurrent writers do not lose a commit, which is the phase-2 acceptance test and the
|
||||
thing that justifies the external manifest store.
|
||||
|
||||
Phase 1 is validated: `lance_namespace` 0.11.1 with `impl=rest` drives the namespace,
|
||||
`lance.write_dataset` writes to the vended location with the vended `storage_options`, and
|
||||
the rows read back. Note that this client version drops `check_declared` and
|
||||
`include_declared` on the wire, so `is_only_declared` reads null through it however the
|
||||
server behaves.
|
||||
|
||||
The commit path is validated at both levels. The mechanism: eight writers race the same
|
||||
manifest key through S3 with `If-None-Match: *`, and exactly one wins. The property that
|
||||
actually matters, which single-winner exclusivity does not by itself establish: eight
|
||||
writers append to one dataset concurrently through lance, and afterwards every batch is
|
||||
still there — the losers saw the conflict, rebased, and committed again. That second test
|
||||
is also the sequence managed versioning could not complete at all, since its store answers
|
||||
"put_if_not_exists is not supported" to the second commit.
|
||||
|
||||
One more that belongs in the Iceberg suite, not this one: a Lance dataset registered through
|
||||
the Iceberg adapter must survive a full maintenance pass. Reading the code, that test should
|
||||
fail today; it has not been run.
|
||||
|
||||
## Open questions
|
||||
|
||||
- Root-level `ListNamespaces` enumerating table buckets is convenient and is a listing
|
||||
surface we do not have on the Iceberg side. Decide whether it is gated behind a flag.
|
||||
- Whether the `.lance` directory suffix is worth the divergence from the Iceberg layout. I
|
||||
think yes — it is what makes the catalog optional — but it means the two catalogs' tables
|
||||
do not look alike on disk, and the admin UI has to know that.
|
||||
- Names: our charsets are lowercase-only and Lance identifiers are arbitrary strings. Reject
|
||||
and document, as Iceberg does, or case-fold. Rejecting is right, but see #10734 for how
|
||||
case handling bites when only one side normalizes.
|
||||
- Whether to land generic-format registration first. Dropping the `"ICEBERG"` check and
|
||||
letting a table carry an arbitrary format plus a location is smaller than this whole
|
||||
design, gets Delta and Parquet catalogued as a side effect, and turns `Format: "LANCE"`
|
||||
into an ordinary value. The argument against is that it invites tables the maintenance
|
||||
worker cannot service, so it needs a "catalog-only, no maintenance" marker to be honest.
|
||||
+13
-11
@@ -2,21 +2,23 @@ FROM ubuntu:22.04
|
||||
|
||||
LABEL author="Chris Lu"
|
||||
|
||||
# Use faster mirrors and optimize package installation
|
||||
# Note: This e2e test image intentionally runs as root for simplicity and compatibility.
|
||||
# Production images (Dockerfile.go_build) use proper user isolation with su-exec.
|
||||
# For testing purposes, running as root avoids permission complexities and dependency
|
||||
# on Alpine-specific tools like su-exec (not available in Ubuntu repos).
|
||||
|
||||
# apt-install prefers Azure's mirror, which archive.ubuntu.com is slow enough from
|
||||
# GitHub-hosted runners to justify, and falls through to archive.ubuntu.com when
|
||||
# Azure is unreachable - which it periodically is, and Acquire::Retries against a
|
||||
# single mirror just retries a dead host. Images built FROM this one install
|
||||
# through it for the same reason.
|
||||
COPY apt-install /usr/local/bin/apt-install
|
||||
RUN chmod +x /usr/local/bin/apt-install && \
|
||||
apt-install curl fio fuse ca-certificates && \
|
||||
rm -rf /tmp/* /var/tmp/*
|
||||
|
||||
RUN apt-get -o Acquire::Retries=5 -o Acquire::http::Timeout=30 update && \
|
||||
DEBIAN_FRONTEND=noninteractive apt-get -o Acquire::Retries=5 -o Acquire::http::Timeout=30 install -y \
|
||||
--no-install-recommends \
|
||||
--no-install-suggests \
|
||||
curl \
|
||||
fio \
|
||||
fuse \
|
||||
ca-certificates \
|
||||
&& apt-get clean \
|
||||
&& rm -rf /var/lib/apt/lists/* \
|
||||
&& rm -rf /tmp/* \
|
||||
&& rm -rf /var/tmp/*
|
||||
RUN mkdir -p /etc/seaweedfs /data/filerldb2
|
||||
|
||||
COPY ./weed /usr/bin/
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
FROM golang:1.26 AS builder
|
||||
FROM golang:1.25 AS builder
|
||||
|
||||
RUN apt-get update && \
|
||||
apt-get install -y build-essential wget ca-certificates && \
|
||||
|
||||
@@ -1,6 +1,4 @@
|
||||
# Pin the builder to the host arch and cross-compile the (CGO-free) Go binary,
|
||||
# so arm64/arm/386 targets skip QEMU emulation of the whole compile.
|
||||
FROM --platform=$BUILDPLATFORM golang:1.26-alpine AS builder
|
||||
FROM golang:1.25-alpine AS builder
|
||||
RUN apk add git g++ fuse
|
||||
RUN mkdir -p /go/src/github.com/seaweedfs/
|
||||
ARG BRANCH=${BRANCH:-master}
|
||||
@@ -14,15 +12,9 @@ RUN cd /go/src/github.com/seaweedfs/seaweedfs && \
|
||||
git checkout $BRANCH) || \
|
||||
(echo "ERROR: Branch/commit $BRANCH not found in repository" && \
|
||||
echo "Available branches:" && git branch -a && exit 1))
|
||||
# seaweed-common only exists on revisions that have it; a BRANCH predating it
|
||||
# still needs the directory so the COPY into rust_builder below never fails.
|
||||
RUN mkdir -p /go/src/github.com/seaweedfs/seaweedfs/seaweed-common
|
||||
ARG TARGETOS TARGETARCH TARGETVARIANT
|
||||
RUN cd /go/src/github.com/seaweedfs/seaweedfs/weed \
|
||||
&& export LDFLAGS="-X github.com/seaweedfs/seaweedfs/weed/util/version.COMMIT=$(git rev-parse --short HEAD)" \
|
||||
&& export GOOS=$TARGETOS GOARCH=$TARGETARCH \
|
||||
&& case "$TARGETARCH" in arm) export GOARM="${TARGETVARIANT#v}";; esac \
|
||||
&& CGO_ENABLED=0 go build -tags "$TAGS" -ldflags "-extldflags -static ${LDFLAGS}" -o /go/bin/weed .
|
||||
&& CGO_ENABLED=0 go install -tags "$TAGS" -ldflags "-extldflags -static ${LDFLAGS}"
|
||||
|
||||
# Rust volume server: use pre-built binary from CI when available (placed in
|
||||
# weed-volume-prebuilt/ by the build-rust-binaries job), otherwise compile
|
||||
@@ -32,11 +24,7 @@ FROM alpine:3.23 as rust_builder
|
||||
ARG TARGETARCH
|
||||
ARG TAGS
|
||||
COPY weed-volume-prebuilt/ /prebuilt/
|
||||
COPY weed-worker-prebuilt/ /prebuilt-worker/
|
||||
COPY --from=builder /go/src/github.com/seaweedfs/seaweedfs/seaweed-volume /build/seaweed-volume
|
||||
# seaweed-common is a path dependency of seaweed-volume that lives beside it,
|
||||
# so the source build below needs it in the same relative position.
|
||||
COPY --from=builder /go/src/github.com/seaweedfs/seaweedfs/seaweed-common /build/seaweed-common
|
||||
COPY --from=builder /go/src/github.com/seaweedfs/seaweedfs/weed /build/weed
|
||||
WORKDIR /build/seaweed-volume
|
||||
RUN if [ -f "/prebuilt/weed-volume-${TARGETARCH}" ]; then \
|
||||
@@ -54,30 +42,12 @@ RUN if [ -f "/prebuilt/weed-volume-${TARGETARCH}" ]; then \
|
||||
echo "Skipping Rust build for $TARGETARCH (unsupported)" && \
|
||||
touch /weed-volume; \
|
||||
fi
|
||||
# The Rust maintenance worker is taken pre-built or not at all: the lance jobs
|
||||
# it carries pull in arrow and datafusion, a far larger dependency tree than
|
||||
# the image build can carry, so an architecture CI did not build for gets the
|
||||
# same empty placeholder the entrypoint refuses to exec.
|
||||
RUN if [ -f "/prebuilt-worker/weed-worker-${TARGETARCH}" ]; then \
|
||||
echo "Using pre-built Rust worker for ${TARGETARCH}" && \
|
||||
cp "/prebuilt-worker/weed-worker-${TARGETARCH}" /weed-worker; \
|
||||
else \
|
||||
echo "No pre-built Rust worker for ${TARGETARCH}" && \
|
||||
touch /weed-worker; \
|
||||
fi
|
||||
|
||||
# Pre-built binaries arrive via GitHub Actions artifacts, which drop the
|
||||
# executable bit, so the copied file is 0644 and exec fails with "Permission
|
||||
# denied". Restore it (no-op for the empty placeholders, which stay size 0).
|
||||
RUN chmod 0755 /weed-volume /weed-worker
|
||||
|
||||
FROM alpine AS final
|
||||
LABEL author="Chris Lu"
|
||||
COPY --from=builder /go/bin/weed /usr/bin/
|
||||
# Copy Rust volume server binary (real binary on amd64/arm64, empty placeholder on other platforms)
|
||||
COPY --from=rust_builder /weed-volume /usr/bin/weed-volume
|
||||
# Same for the Rust maintenance worker, which serves Lance table buckets
|
||||
COPY --from=rust_builder /weed-worker /usr/bin/weed-worker
|
||||
RUN mkdir -p /etc/seaweedfs
|
||||
COPY --from=builder /go/src/github.com/seaweedfs/seaweedfs/docker/filer.toml /etc/seaweedfs/filer.toml
|
||||
COPY --from=builder /go/src/github.com/seaweedfs/seaweedfs/docker/entrypoint.sh /entrypoint.sh
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
FROM golang:1.26 AS builder
|
||||
FROM golang:1.25 AS builder
|
||||
|
||||
RUN apt-get update
|
||||
RUN apt-get install -y build-essential libsnappy-dev zlib1g-dev libbz2-dev libgflags-dev liblz4-dev libzstd-dev
|
||||
|
||||
@@ -1,4 +1,4 @@
|
||||
FROM golang:1.26 AS builder
|
||||
FROM golang:1.25 AS builder
|
||||
|
||||
RUN apt-get update
|
||||
RUN apt-get install -y build-essential libsnappy-dev zlib1g-dev libbz2-dev libgflags-dev liblz4-dev libzstd-dev
|
||||
|
||||
@@ -15,9 +15,3 @@ COPY tarantool /opt/tarantool/app
|
||||
# build app
|
||||
RUN tt build app
|
||||
|
||||
# the base image's default healthcheck assumes a single-instance layout and
|
||||
# checks a control socket path that doesn't exist for this multi-instance
|
||||
# app, so it never reports healthy; check instance status instead.
|
||||
HEALTHCHECK --interval=5s --timeout=3s --start-period=15s --retries=6 \
|
||||
CMD tt status app | awk 'NR>2{if ($2!="RUNNING") exit 1} END{if (NR<=2) exit 1}'
|
||||
|
||||
|
||||
@@ -127,9 +127,6 @@ test_tarantool: tags = tarantool
|
||||
test_tarantool: build_tarantool_dev_env build
|
||||
docker compose -f compose/test-tarantool-filer.yml -p seaweedfs up
|
||||
|
||||
test_keycloak_s3: build
|
||||
docker compose -f compose/test-keycloak-s3.yml -p seaweedfs up
|
||||
|
||||
clean:
|
||||
rm ./weed
|
||||
|
||||
|
||||
@@ -31,49 +31,6 @@ docker compose -f seaweedfs-dev-compose.yml -p seaweedfs up
|
||||
|
||||
```
|
||||
|
||||
## Verify an image signature
|
||||
|
||||
Every image CI pushes to `chrislusf/seaweedfs` and `ghcr.io/chrislusf/seaweedfs` is signed with [cosign](https://docs.sigstore.dev/cosign/verifying/verify/), keyless, by the GitHub Actions workflow that built it, so there is no key to fetch or pin. The signature is attached to the image digest and covers the multi-arch index and each platform image in it; `latest` is the release image under another tag and verifies the same way. Images published before September 2026 predate signing.
|
||||
|
||||
```bash
|
||||
cosign verify \
|
||||
--certificate-oidc-issuer https://token.actions.githubusercontent.com \
|
||||
--certificate-identity-regexp '^https://github.com/seaweedfs/seaweedfs/\.github/workflows/container_release_unified\.yml@' \
|
||||
chrislusf/seaweedfs:latest
|
||||
```
|
||||
|
||||
cosign prints the digest it verified. Deploy by that digest, or let an admission controller resolve the tag, so what runs is what was checked.
|
||||
|
||||
The identity is `https://github.com/seaweedfs/seaweedfs/.github/workflows/<workflow>@<ref>`. The ref is `refs/tags/<version>` for a release and `refs/heads/master` when a variant was republished by hand. The workflow is `container_release_unified.yml` for the release images, `container_dev.yml` for `dev`, `container_latest.yml` for a `latest` rebuilt by hand, `container_release_foundationdb.yml` for the `_large_disk_foundationdb` release image, and `container_foundationdb_version.yml` or `container_rocksdb_version.yml` for the per-version builds. The regexp above accepts release images only; `container_[a-z_]+\.yml@` accepts everything this repository publishes, `dev` included.
|
||||
|
||||
The same check as a Kyverno policy, release images only:
|
||||
|
||||
```yaml
|
||||
apiVersion: kyverno.io/v1
|
||||
kind: ClusterPolicy
|
||||
metadata:
|
||||
name: verify-seaweedfs-images
|
||||
spec:
|
||||
validationFailureAction: Enforce
|
||||
webhookTimeoutSeconds: 30
|
||||
rules:
|
||||
- name: signed-by-the-release-workflow
|
||||
match:
|
||||
any:
|
||||
- resources:
|
||||
kinds:
|
||||
- Pod
|
||||
verifyImages:
|
||||
- imageReferences:
|
||||
- "docker.io/chrislusf/seaweedfs:*"
|
||||
- "ghcr.io/chrislusf/seaweedfs:*"
|
||||
attestors:
|
||||
- entries:
|
||||
- keyless:
|
||||
issuer: https://token.actions.githubusercontent.com
|
||||
subject: https://github.com/seaweedfs/seaweedfs/.github/workflows/container_release_unified.yml@refs/tags/*
|
||||
```
|
||||
|
||||
## Local Development
|
||||
|
||||
```bash
|
||||
|
||||
@@ -1,14 +1,11 @@
|
||||
FROM alpine:latest
|
||||
|
||||
# Install required packages
|
||||
RUN apk upgrade --no-cache && \
|
||||
apk add --no-cache \
|
||||
RUN apk add --no-cache \
|
||||
ca-certificates \
|
||||
fuse \
|
||||
curl \
|
||||
jq \
|
||||
libcrypto3 \
|
||||
libssl3
|
||||
jq
|
||||
|
||||
# Copy our locally built binary
|
||||
COPY weed-local /usr/bin/weed
|
||||
|
||||
@@ -1,25 +0,0 @@
|
||||
#!/bin/sh
|
||||
# Install packages, falling through to the next Ubuntu mirror when one is
|
||||
# unreachable. See docker/Dockerfile.e2e.
|
||||
set -e
|
||||
|
||||
# Every rewrite starts from the pristine list, so a mirror that just failed does
|
||||
# not become the pattern the next rewrite has to match.
|
||||
[ -f /etc/apt/sources.list.orig ] || cp /etc/apt/sources.list /etc/apt/sources.list.orig
|
||||
|
||||
for mirror in azure.archive.ubuntu.com archive.ubuntu.com; do
|
||||
# Any archive host, so this works whether the pristine list came from the
|
||||
# base image (archive.ubuntu.com) or a CI runner (azure.archive.ubuntu.com).
|
||||
sed "s|http://[a-z0-9.]*archive\.ubuntu\.com/ubuntu|http://$mirror/ubuntu|g; s|http://security\.ubuntu\.com/ubuntu|http://$mirror/ubuntu|g" \
|
||||
/etc/apt/sources.list.orig > /etc/apt/sources.list
|
||||
if apt-get -o Acquire::Retries=3 -o Acquire::http::Timeout=15 update && \
|
||||
DEBIAN_FRONTEND=noninteractive apt-get -o Acquire::Retries=3 -o Acquire::http::Timeout=15 install -y \
|
||||
--no-install-recommends --no-install-suggests "$@"; then
|
||||
apt-get clean
|
||||
rm -rf /var/lib/apt/lists/*
|
||||
exit 0
|
||||
fi
|
||||
echo "apt: $mirror unreachable, trying the next mirror" >&2
|
||||
done
|
||||
|
||||
exit 1
|
||||
@@ -30,5 +30,3 @@ sleep_minutes = 17 # sleep minutes between each script execution
|
||||
bucket = "volume_bucket" # an existing bucket
|
||||
endpoint = "http://server2:8333"
|
||||
storage_class = "STANDARD_IA"
|
||||
# upload_concurrency = 5 # concurrent multipart part uploads per volume (volume.tier.upload -concurrent overrides)
|
||||
# download_concurrency = 5 # concurrent multipart part downloads per volume (volume.tier.download -concurrent overrides)
|
||||
|
||||
Some files were not shown because too many files have changed in this diff Show More
Reference in New Issue
Block a user